Home›Compute

Compute

AI infrastructure and compute: GPU availability, cloud pricing, hardware releases, and how compute constraints shape model architecture decisions.

83 articles

Compute deep dives from the blog

All posts →
AI Engineering

Caveman: How Stone-Age Grammar Cuts AI Agent Token Costs by 65%

8 min read · Read →
AI Agents

The True Cost of Running AI Agents at Scale — Where the Money Actually Goes

10 min read · Read →
AI Engineering

How to Cut LLM API Costs by 70%+ Using Prompt Caching and Model Routing

7 min read · Read →
60 articles
AI’s GPU focus meets a CPU reality check at Dell and AMD
SiliconANGLE AI· Today
AI’s GPU focus meets a CPU reality check at Dell and AMD

Agentic AI is rewriting the business development playbook for chipmakers and server builders. Graphics processing units still grab the headlines, but as supercomputing and AI converge, the next wave of demand is landing on central processing units that must fit within data centers’ existing po...

AI’s hidden energy tax: More than 80% of scale-up traffic is just memory moving around
SiliconANGLE AI· Today
AI’s hidden energy tax: More than 80% of scale-up traffic is just memory moving around

The article highlights that over 80% of data traffic in large‑scale AI deployments is spent moving memory rather than performing compute, creating a hidden energy tax as inference workloads dominate. GPUs often idle while waiting for data because high‑bandwidth memory (HBM) is tightly coupled to processors and cannot…

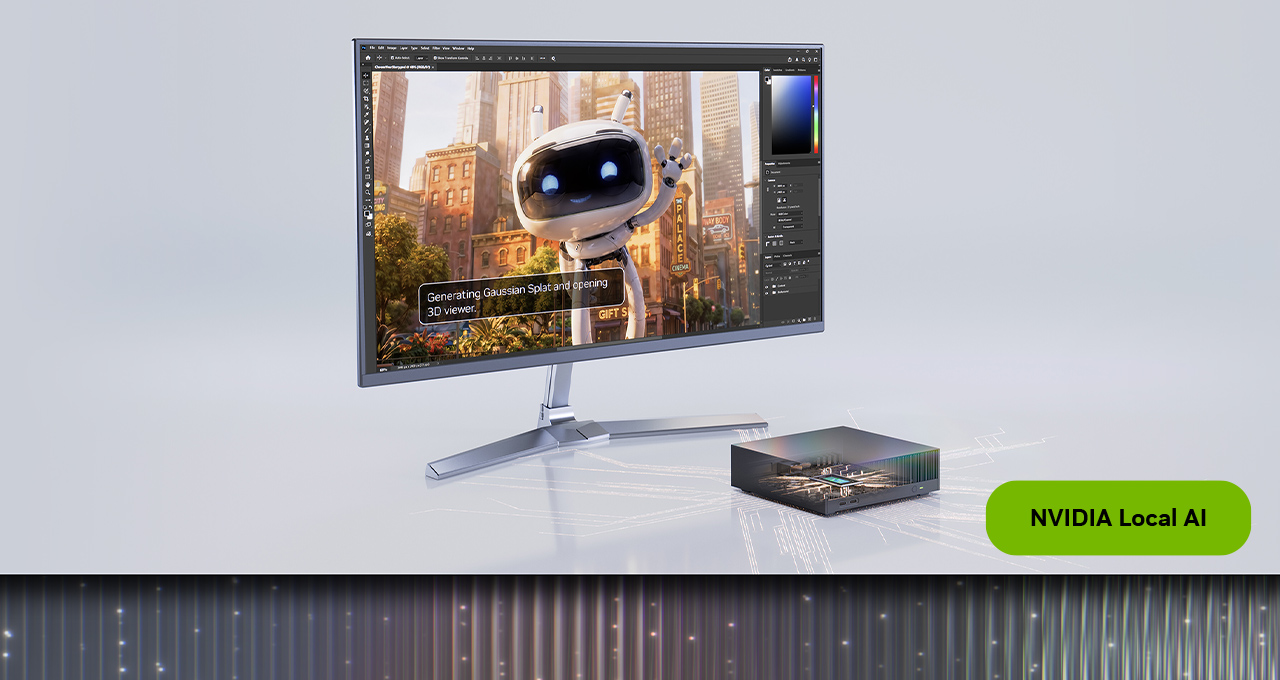
NVIDIA RTX Spark Compact Desktops Out Now
NVIDIA Blog· 7 min read· Today
NVIDIA RTX Spark Compact Desktops Out Now

NVIDIA’s RTX Spark compact desktops, now shipping from ASUS, Dell and MSI, pack a 20‑core NVIDIA Grace CPU, a Blackwell RTX GPU with 6,144 CUDA cores and up to 128 GB of unified memory, delivering up to 1 PFLOP of AI performance and enabling on‑device execution of 120‑billion‑parameter LLMs, real‑time 90 GB+ 3D…

AI and supercomputing merge as universities build GPU clusters at cloud-provider scale
SiliconANGLE AI· Today
AI and supercomputing merge as universities build GPU clusters at cloud-provider scale

Universities racing to build AI infrastructure are learning that raw compute changes the pace of science itself, from molecular discovery to materials engineering. AI and high-performance computing are converging, and campus technology leaders are now building like cloud operators. The Texas A&M...

How we raised Databricks cluster rate limits by 7.5×
Databricks Blog· 6 min read· Yesterday
How we raised Databricks cluster rate limits by 7.5×

The Compute Platform team at Databricks increased the cluster rate limits by 7.5×, enabling far higher throughput for cluster provisioning. This change directly expands the capacity of Databricks workloads without requiring additional hardware. Engineers can now scale job execution more aggressively while staying…

Dell bets liquid-cooled, software-defined storage can keep AI factories fed
SiliconANGLE AI· Yesterday
Dell bets liquid-cooled, software-defined storage can keep AI factories fed
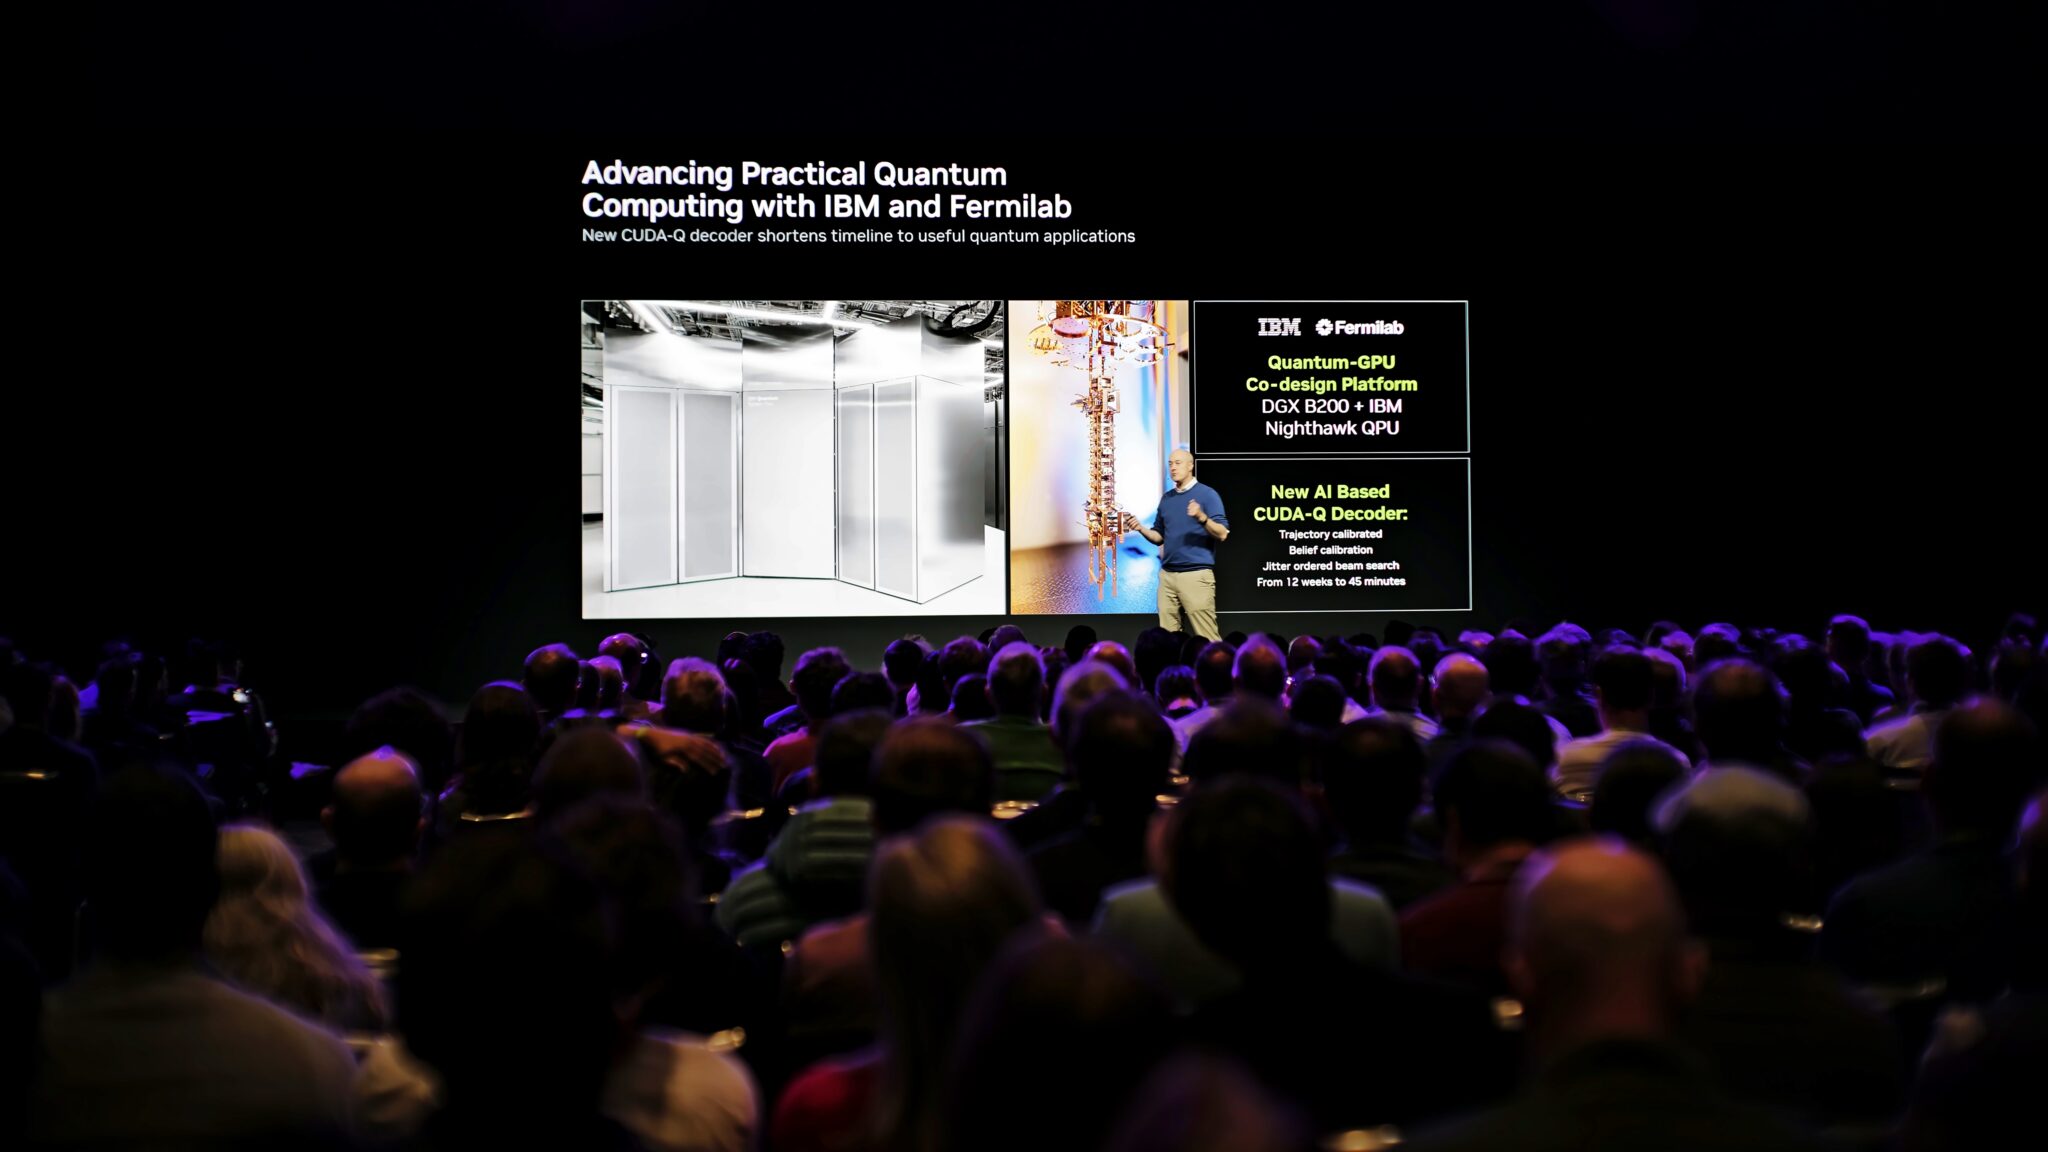
Dell Technologies is positioning its PowerEdge servers with liquid‑cooled, software‑defined storage to handle the growing density of AI factories, enabling nodes to switch roles as workloads shift from training to inference and agents. By integrating flexible storage directly into compute racks, Dell aims to reduce…

Ian Buck Kicks Off NVIDIA’s Week at SC26 as Science Enters the Age of Agents
NVIDIA Blog· 4 min read· Yesterday
Ian Buck Kicks Off NVIDIA’s Week at SC26 as Science Enters the Age of Agents
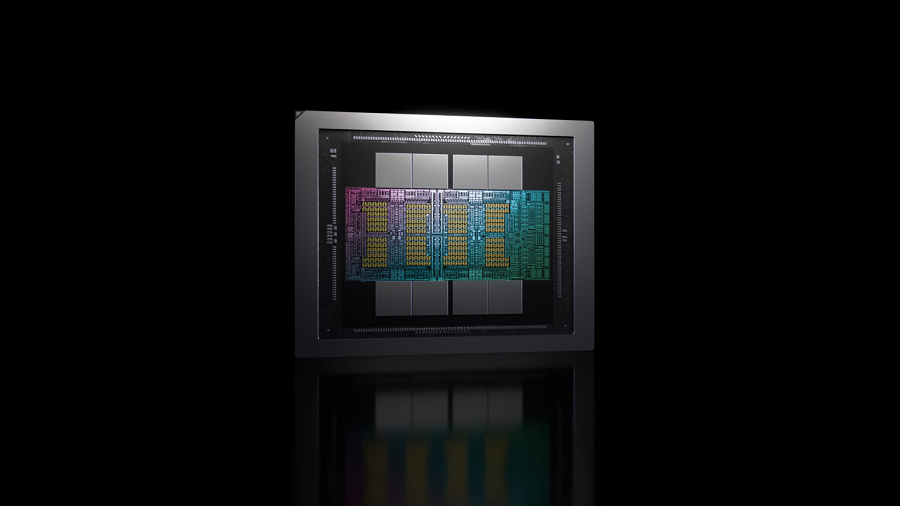
NVIDIA unveiled new AI agent tooling at SC26, including the Nemotron for Science model built on Nemotron 3.5 Super VL with a chemistry dataset, and showcased agents that autonomously plan experiments, run simulations, and fix software setups. Benchmarks highlighted an agent that repaired 81% of GROMACS test cases in…

At SC26, Nvidia debuts new Rubin HPC chip, scientific research libraries
SiliconANGLE AI· 2 days ago
At SC26, Nvidia debuts new Rubin HPC chip, scientific research libraries
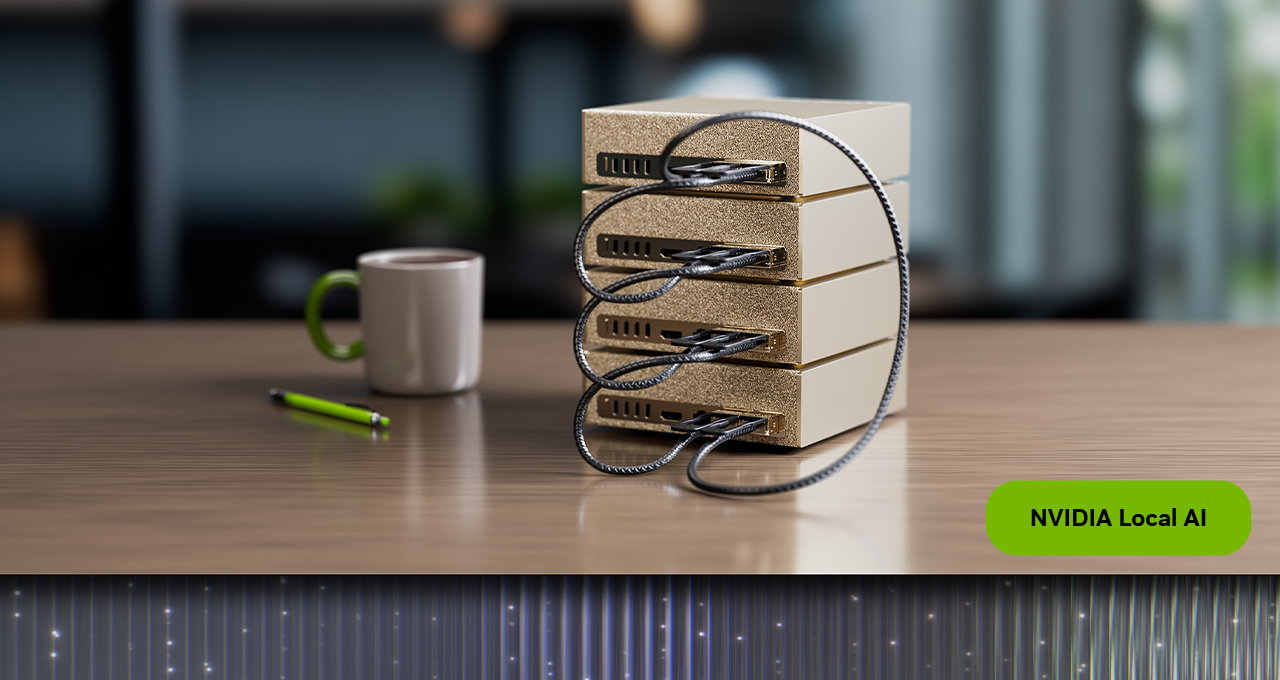
Nvidia announced the Rubin HPC graphics card, which offers significantly more cores than the company’s current flagship GPU, targeting accelerated scientific research workloads. The launch also includes over half a dozen new software tools aimed at scientists and engineers. These offerings collectively aim to boost…

NVIDIA DGX Spark Developer Kit Turns a Desk Into a Supercomputing Lab
NVIDIA Blog· 4 min read· 2 days ago
NVIDIA DGX Spark Developer Kit Turns a Desk Into a Supercomputing Lab

NVIDIA unveiled the DGX Spark Developer Kit, a four‑node desktop‑sized HPC cluster built on the GB10 Grace Blackwell Superchip that links nodes in a ring via ConnectX‑7 networking without a switch. The kit aggregates 512 GB of memory and 20 TB of NVMe storage, enabling local deployment of up to 700 B‑parameter models…

Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics
NVIDIA Blog· 4 min read· 2 days ago
Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics

Lambda is deploying NVIDIA Photonics co‑packaged optics (CPO) switches to interconnect over 10,000 GPUs across NVIDIA GB300 NVL72 racks, achieving up to a 10% latency reduction at pod scale and up to 5× better power efficiency with 15× higher reliability versus conventional pluggable optics. Each switch provides 144 ×…

NVIDIA Expands Slurm to Bring Quantum Computing Into Supercomputing
NVIDIA Blog· 4 min read· 2 days ago
NVIDIA Expands Slurm to Bring Quantum Computing Into Supercomputing

NVIDIA’s new Slurm 26.11 release adds native quantum‑processor support, letting supercomputing centers schedule QPUs through the same workflow used for CPUs/GPUs and leveraging the QRMI and QDMI interfaces. The update also bundles a community‑driven orchestration layer for the CUDA‑Q open platform, including a…

NVIDIA Sweeps MLPerf Training and Endpoints as Vera Rubin Debuts With Leading Performance
NVIDIA Blog· 5 min read· 2 days ago
NVIDIA Sweeps MLPerf Training and Endpoints as Vera Rubin Debuts With Leading Performance

NVIDIA’s Vera Rubin platform swept every MLPerf Training v6.1 benchmark and, in its first MLPerf Endpoints submission, achieved more than 10× generational throughput‑per‑watt gains for agentic inference. The NVL72 system delivered up to 2× higher performance per GPU than the prior GB300 NVL72 and scaled DeepSeek‑V3…

NVIDIA CUDA-X Libraries Give Agents the Tools to Accelerate Scientific Discovery
NVIDIA Blog· 4 min read· 2 days ago
NVIDIA CUDA-X Libraries Give Agents the Tools to Accelerate Scientific Discovery

NVIDIA’s expanded CUDA‑X libraries—cuPhoton, cuPotential and cuSpa—deliver dramatic speedups for scientific workloads, cutting a month‑long black‑hole data correlation to eight minutes and boosting molecular simulation throughput by up to 3×. The cuPhoton.xBeam and cuPhoton.xLens modules run on distributed multi‑GPU…

CUDA at 20: How the Platform Transformed Scientific Computing
NVIDIA Blog· 4 min read· 2 days ago
CUDA at 20: How the Platform Transformed Scientific Computing
NVIDIA celebrated CUDA’s 20‑year anniversary at SC26, highlighting its evolution from the first CUDA programs in 2006 to a foundation for modern scientific and AI workloads. The platform now supports over 11 million developers, more than 1,000 CUDA‑X libraries, and has enabled landmark achievements such as training…

NVIDIA Announces Rubin HPC — A New GPU to Accelerate Agents for Science, Engineering and Analytics
NVIDIA Blog· 4 min read· 2 days ago
NVIDIA Announces Rubin HPC — A New GPU to Accelerate Agents for Science, Engineering and Analytics

NVIDIA unveiled the Rubin HPC GPU, part of the Vera Rubin platform, featuring a record‑breaking > 50,000 CUDA cores, sparse‑data acceleration, and seventh‑generation NVLink for fast GPU‑to‑GPU communication. The architecture is balanced to scale data movement with compute, targeting simulation‑heavy workloads such as…

OpenFold3 on Amazon SageMaker JumpStart: Predict biomolecular structures
AWS ML Blog· 20 min read· 5 days ago
OpenFold3 on Amazon SageMaker JumpStart: Predict biomolecular structures

** OpenFold3‑preview (version 0.4.1, checkpoint of3‑p2‑155k) is now available as a SageMaker JumpStart model that can be deployed to an asynchronous inference endpoint on GPU‑enabled instances (ml.g6.4xlarge default). The service accepts protein, DNA, RNA sequences and SMILES strings, returning all‑atom structures in…

AI Is Helping Care Teams Get Patients the Right Care, Sooner
NVIDIA Blog· 10 min read· 5 days ago
AI Is Helping Care Teams Get Patients the Right Care, Sooner

Dyania Health’s Synapsis AI is a clinical reasoning engine that ingests decades‑long free‑text patient records to surface evidence‑based clinical signals, running entirely on NVIDIA‑accelerated compute within a hospital firewall. The system was used at Cleveland Clinic to process over 7,800 aortic valve replacement…

What to expect during SC26: Join theCUBE Nov. 17–19
SiliconANGLE AI· 6 days ago
What to expect during SC26: Join theCUBE Nov. 17–19

SC26 in Chicago will focus on the convergence of high‑performance computing and artificial intelligence, highlighting advances in exascale computing, accelerated systems, data storage, and high‑speed networking. The event runs from Nov. 17–19 and features major industry players such as Dell Technologies Inc., Google…

Google’s GKE Labs turns reinforcement learning into a Kubernetes workload
SiliconANGLE AI· Nov 12, 2026
Google’s GKE Labs turns reinforcement learning into a Kubernetes workload

Google’s GKE Labs project packages reinforcement‑learning‑based model fine‑tuning as a native Kubernetes workload, unifying training, inference, and sandboxed agent execution into a single loop. By containerizing the RL pipeline, engineers can leverage standard K8s scheduling, scaling, and isolation mechanisms for…

Semantic diffing of formal policies with anti-unification
AWS ML Blog· 27 min read· Nov 11, 2026
Semantic diffing of formal policies with anti-unification

The article introduces an open‑source engine that computes semantic diffs of formal policies by using anti‑unification over an e‑graph to find the most specific common pattern between two expressions. By supplying algebraic laws and domain‑specific rules (e.g., equating external and internal destinations), the engine…

Detecting and recovering from silent data corruption on Amazon SageMaker HyperPod
AWS ML Blog· 37 min read· Nov 11, 2026
Detecting and recovering from silent data corruption on Amazon SageMaker HyperPod

The authors introduce three lightweight checks integrated into a PyTorch DistributedDataParallel (DDP) loop that detect silent data corruption on Amazon SageMaker HyperPod, pinpoint the faulty GPU node, and trigger automatic node recovery. The checks compare intermediate tensor values against a reference checksum,…

The attendee’s guide to the AWS re:Invent 2026 AI/ML track
AWS ML Blog· 23 min read· Nov 11, 2026
The attendee’s guide to the AWS re:Invent 2026 AI/ML track

The guide outlines AWS re:Invent 2026’s AI/ML track, highlighting over 140 sessions across breakout, chalk‑talk, builder, workshop, code‑talk, and lightning‑talk formats. It maps the AWS AI stack—from AI‑optimized data centers and Trainium or NVIDIA GPU chips to the AWS Context data foundation—so attendees can target…

Accelerate GPU training on Unity Catalog tables with UCDataset
Databricks Blog· 6 min read· Nov 9, 2026
Accelerate GPU training on Unity Catalog tables with UCDataset

The article announces UCDataset, a feature that enables faster GPU‑based training directly on Unity Catalog tables, reducing data movement overhead. By integrating UCDataset, engineers can keep data in place while leveraging GPU acceleration, streamlining end‑to‑end training pipelines. This approach promises cost…

Korea Advances Physical AI Across Industries With NVIDIA
NVIDIA Blog· 4 min read· Nov 9, 2026
Korea Advances Physical AI Across Industries With NVIDIA

Samsung Electronics leveraged NVIDIA’s cuISS, cuDSS, cuEST, cuEquivariance and PhysicsNeMo to accelerate semiconductor material and process simulations, achieving up to 5× faster quantum‑chemical runs and a ≈1,600× speedup (18 h → 41 s) for AI‑homogenized thermal‑mechanical analysis. Kakao Mobility will integrate…

How Amazon Marketplace evaluates content quality with Amazon SageMaker AI
AWS ML Blog· 18 min read· Nov 5, 2026
How Amazon Marketplace evaluates content quality with Amazon SageMaker AI
Amazon Marketplace leverages Amazon SageMaker to assess A+ Content quality at scale by rendering each product page as a single snapshot, then scoring it with a vision‑language model that incorporates OCR readability signals. The resulting scores feed into a CatBoost classifier, and SHAP values are used to explain and…

University of Utah retains operational sovereignty as Redtail expands research access
SiliconANGLE AI· Nov 5, 2026
University of Utah retains operational sovereignty as Redtail expands research access

The University of Utah’s Redtail AI factory supercomputer is expanding its research access while retaining operational sovereignty, allowing the university to control allocation, management, and security of the shared computing resources. This governance model ensures that the institution can prioritize internal…

More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge
NVIDIA Blog· 6 min read· Nov 5, 2026
More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge

NVIDIA’s full‑stack codesign approach boosts AI memory efficiency by jointly optimizing GPUs, CPUs, networking, storage, and software, achieving roughly 3 % more HBM capacity per GPU while delivering up to 30× higher agentic throughput per dollar on the SemiAnalysis AgentX workload. By strategically placing model…

Hamed Karimi wins ECML PKDD Test-of-Time Award
Amazon Science· 6 min read· Nov 5, 2026
Hamed Karimi wins ECML PKDD Test-of-Time Award

Amazon senior applied scientist Hamed Karimi and coauthors received the 2026 ECML PKDD Test‑of‑Time Award for their 2016 paper “Linear convergence of gradient and proximal‑gradient methods under the Polyak–Łojasiewicz condition,” which revived the 1963 Polyak‑Łojasiewicz inequality to prove linear convergence of…

Generative media inference startup fal raises $1.3B at a $16B valuation
SiliconANGLE AI· Nov 3, 2026
Generative media inference startup fal raises $1.3B at a $16B valuation

Generative media inference startup fal announced a $1.3 billion funding round, pushing its valuation to $16 billion. The capital will be used to expand computing power and grow its team beyond the current 185 employees. Fal offers a cloud platform that runs image, video, and audio generation models for developers.…

Building ultra-low-latency voice AI applications on AWS
AWS ML Blog· 13 min read· Nov 3, 2026
Building ultra-low-latency voice AI applications on AWS

Cartesia, an AWS Partner, demonstrates that purpose‑built State Space Models can deliver text‑to‑speech (TTS) and speech‑to‑text (STT) with sub‑100 ms latency at global scale. The Sonic model, built on this architecture, can be deployed directly on Amazon SageMaker AI or on self‑managed Amazon EC2 GPU instances,…

AI Is Changing How Semiconductor Fabs Work — and Engineers Are Moving Faster Because of It
NVIDIA Blog· 4 min read· Nov 3, 2026
AI Is Changing How Semiconductor Fabs Work — and Engineers Are Moving Faster Because of It

AI‑driven acceleration is reshaping semiconductor fab workflows by cutting simulation runtimes dramatically—COMSOL sees up to 10× speedups with NVIDIA cuDSS, Applied Materials’ Ginestra platform runs up to 10× faster, its ACE+ platform achieves up to 35× acceleration with NVIDIA PhysicsNeMo, and Siemens’ Calibre…

Things That Go Beep in the Night: Agentic AI Joins the Search for Extraterrestrial Signals
NVIDIA Blog· 4 min read· Oct 30, 2026
Things That Go Beep in the Night: Agentic AI Joins the Search for Extraterrestrial Signals

Breakthrough Listen and the SETI Institute have integrated agentic AI into the Allen Telescope Array, using NVIDIA’s Holoscan platform to ingest and process 2.4 terabits per second of raw sensor data on RTX PRO 6000 Blackwell GPUs, enabling real‑time steering, calibration, and signal‑processing via natural‑language…

Distributed training with Ray Train DLCs and EFA on EKS
AWS ML Blog· 18 min read· Oct 28, 2026
Distributed training with Ray Train DLCs and EFA on EKS

The post demonstrates scaling PyTorch training on Amazon EKS using the Ray Train Deep Learning Container (DLC) — public.ecr.aws/deep-learning-containers/ray:train-ml-cuda-v1.1 — which bundles CUDA, PyTorch 2.13.0, torchvision 0.28.0, NCCL, EFA userspace libraries, and the AWS OFI NCCL plugin. By defining a RayCluster…

Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model
SiliconANGLE AI· Oct 28, 2026
Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model
Nvidia announced Nemotron 3.5 Transcribe, an open‑source multilingual audio transcription and translation model that won a benchmark leaderboard. The release includes an open data pipeline that lets engineers fine‑tune the model for their own speech‑to‑text workloads. By consolidating detection, transcription, speaker…

Thin, Light and Built for Everything: NVIDIA RTX Spark Windows Laptops Gain New Models, Agent Tools and Games
NVIDIA Blog· 8 min read· Oct 28, 2026
Thin, Light and Built for Everything: NVIDIA RTX Spark Windows Laptops Gain New Models, Agent Tools and Games

NVIDIA RTX Spark laptops now ship with a Blackwell RTX GPU and Grace CPU unified in a single super‑chip offering up to 128 GB of memory and 1 PFLOP of FP4 AI performance, bringing personal‑AI supercomputer capabilities to thin‑and‑light Windows devices. The launch adds the open‑weight Nemotron 3.5 Transcribe speech…

Oracle brings Google’s TPUs to its cloud, adds ChatGPT integrations
SiliconANGLE AI· Oct 27, 2026
Oracle brings Google’s TPUs to its cloud, adds ChatGPT integrations

Oracle announced that its public cloud will now offer Google’s TPU AI accelerators, marking the first time Google supplies its chips to another hyperscaler, and will also add Cerebras wafer‑scale accelerators and OpenAI’s Jalapeño inference processor. This expands Oracle’s hardware portfolio with industry‑leading…

How AI Is Changing the Pace of Discovery for Millions Living With Dementia
NVIDIA Blog· 4 min read· Oct 27, 2026
How AI Is Changing the Pace of Discovery for Millions Living With Dementia
The C‑BRAIN consortium, launched in November 2025 and partnered with NVIDIA, is building a hybrid centralized‑federated AI platform to unlock “dark data” in Alzheimer’s research, reducing analysis time from weeks to hours. It currently runs 64 NVIDIA data‑center GPUs on‑premises plus Azure cloud nodes, and plans to…

Marvell’s early chipmaking gamble pays off amid AI demand
SiliconANGLE AI· Oct 26, 2026
Marvell’s early chipmaking gamble pays off amid AI demand

Marvell Technology Inc. pursued an early transition to advanced nanometer process nodes eight years ago, and this strategic gamble is now yielding benefits as AI workloads drive heightened demand for high‑density, high‑performance silicon. The company’s trajectory shows steady upward momentum, leveraging the…

Kazakhstan Expands Compute for Its AI Future
NVIDIA Blog· 6 min read· Oct 23, 2026
Kazakhstan Expands Compute for Its AI Future

Kazakhstan is accelerating its AI ecosystem by expanding accelerated compute infrastructure and launching initiatives like Kazakh‑language models, while NVIDIA announced an investment in local startup Higgsfield AI and highlighted its OpenShell tool for securely containing AI agents. The push ties the nation’s…

NVIDIA Unveils Minerva to Bring End-to-End Observability for AI Factories
NVIDIA Blog· 4 min read· Oct 22, 2026
NVIDIA Unveils Minerva to Bring End-to-End Observability for AI Factories
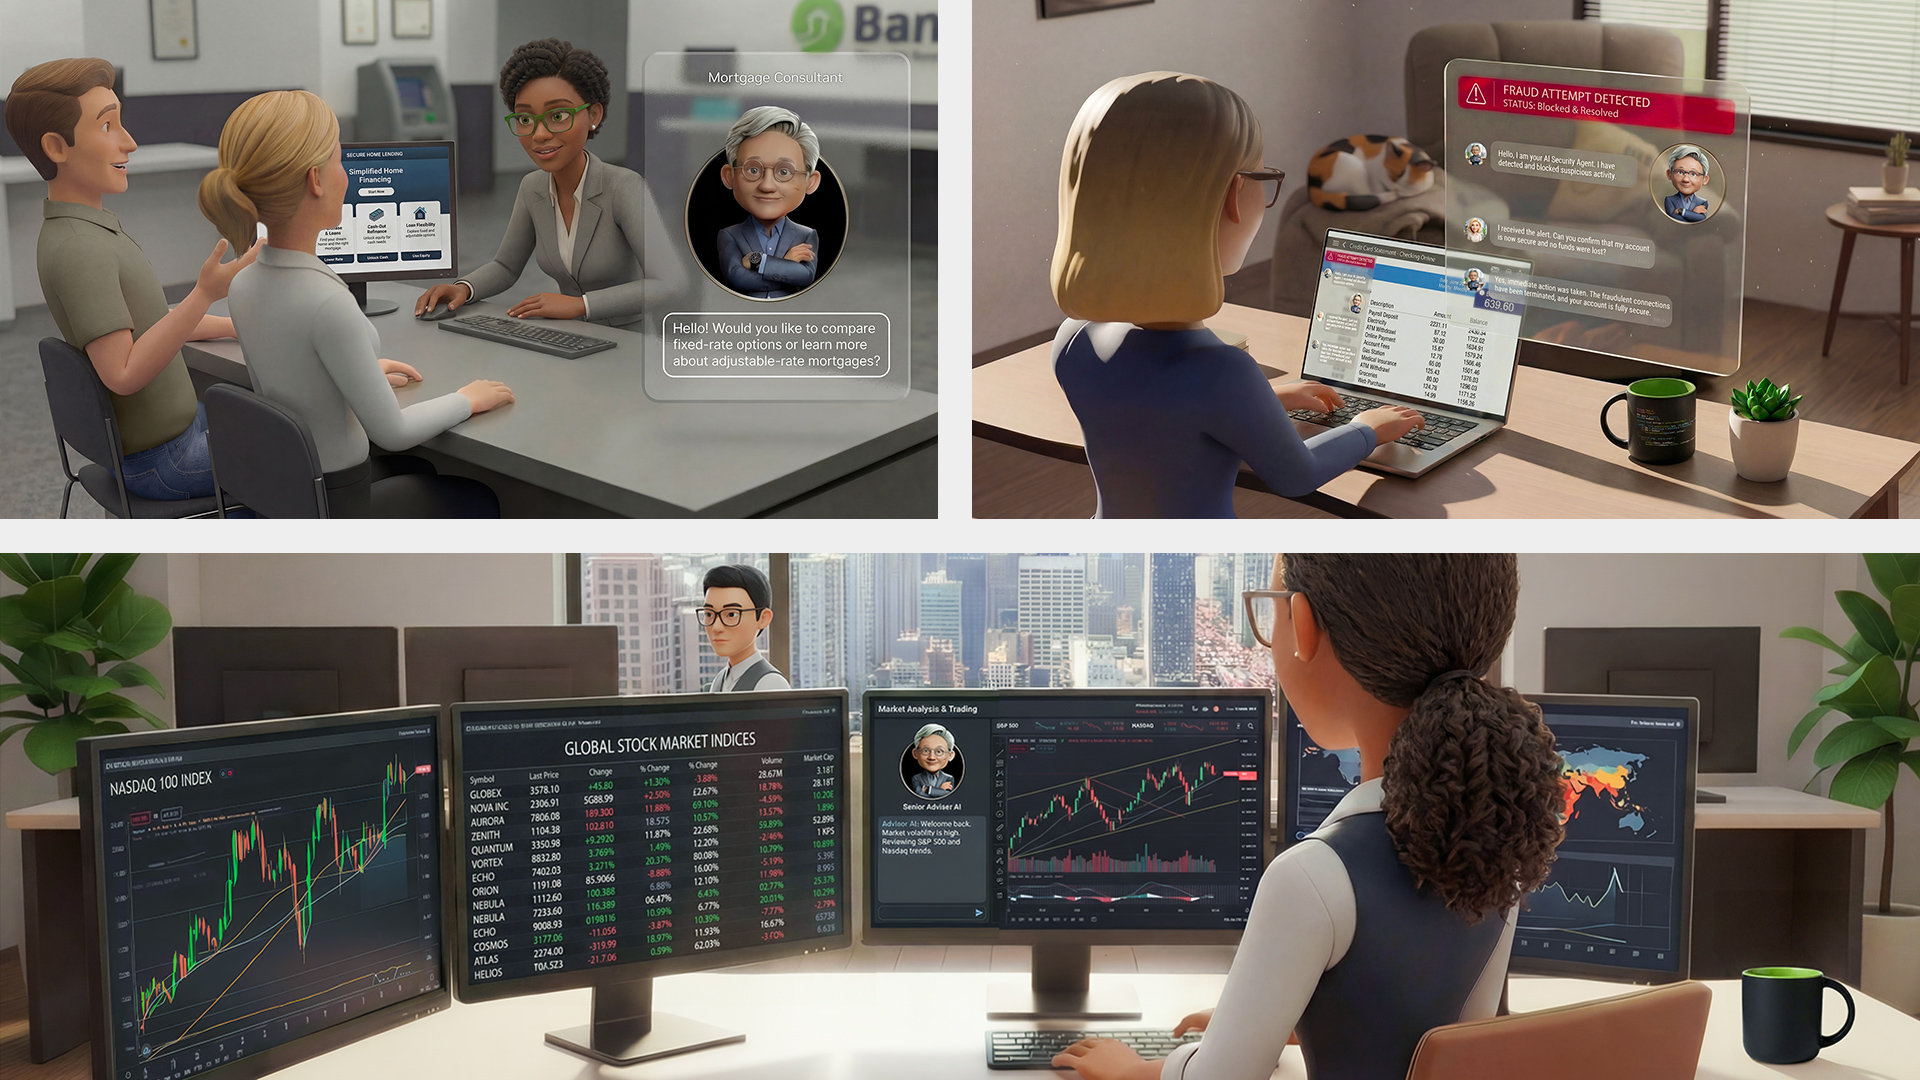
NVIDIA Minerva is an AIOps platform that aggregates telemetry from GPUs, networking, storage, schedulers, and workloads into a dynamic knowledge graph, applying supervised and unsupervised machine‑learning models to detect anomalies and predict failures across AI factories. It processes billions of data points per…

Leading European Financial Services Organizations Embrace Open Models to Build Proprietary Intelligence
NVIDIA Blog· 4 min read· Oct 22, 2026
Leading European Financial Services Organizations Embrace Open Models to Build Proprietary Intelligence

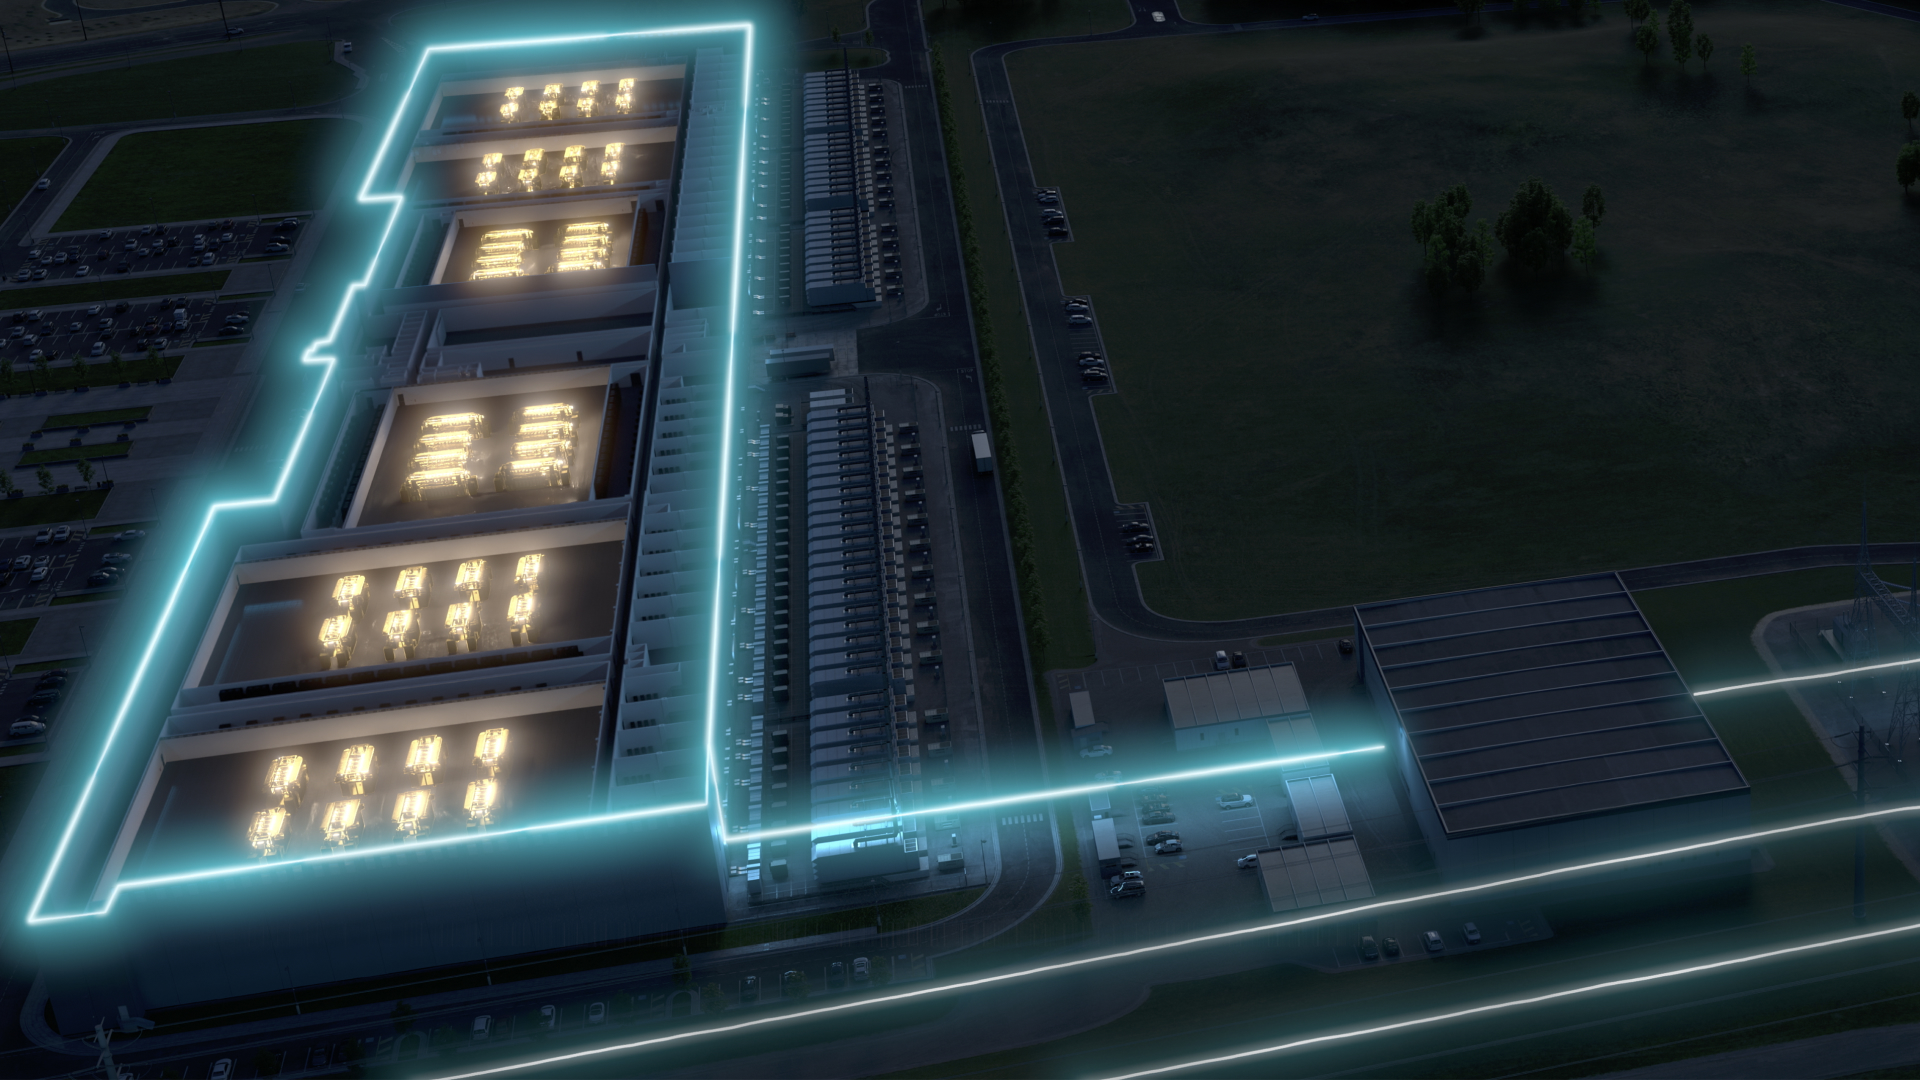
European financial firms are deploying open‑weight foundation models at production scale using NVIDIA‑accelerated hardware such as Blackwell Ultra and RTX PRO 6000 GPUs, with toolchains like cuDF, Dynamo‑Triton, and the Polars GPU engine. Revolut’s PRAGMA model serves 80 million customers and is engineered to scale…

How Companies Are Using NVIDIA DSX to Break the Power Bottleneck
NVIDIA Blog· 4 min read· Oct 22, 2026
How Companies Are Using NVIDIA DSX to Break the Power Bottleneck

NVIDIA DSX AI Factory Platform unifies grid, substation, and AI compute systems to tackle the power bottleneck, offering simulation (DSX Sim, SimReady), flexible load management (DSX Flex), and efficiency‑boosting components (DSX MaxLPS, DSX Exchange). Early adopters report up to 10 % more compute within the same…

Pioneers Across Europe Deploy NVIDIA Earth-2 Open Models to Power Real-World Weather and Climate Prediction
NVIDIA Blog· 4 min read· Oct 22, 2026
Pioneers Across Europe Deploy NVIDIA Earth-2 Open Models to Power Real-World Weather and Climate Prediction

NVIDIA Earth‑2 now includes StormScope EU, a regional short‑term forecasting model trained on European weather data that ingests EUMETSAT satellite observations across 16 Meteosat channels and outputs cloud predictions every 10 minutes. The open‑source PhysicsNeMo framework lets developers fine‑tune Earth‑2…

Train Qwen3 on AWS Trainium with torchtitan
AWS ML Blog· 11 min read· Oct 21, 2026
Train Qwen3 on AWS Trainium with torchtitan

This walkthrough demonstrates three ways to train the Qwen3‑4B‑Instruct‑2507 model on a single trn2.48xlarge Trainium instance using torchtitan‑neuron, including a Transformers v5 backend, torchtitan’s native Qwen3 spec, and a custom MoE kernel via the Neuron Kernel Interface. All methods share the same torchrun…

Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
Hugging Face Blog· 7 min read· Oct 21, 2026
Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.

This article demonstrates how to systematically profile inference on AWS Trainium using TorchNeuron, showing how to configure torch.profiler with a NeuronConfig and NeuronProfiler to capture both framework and hardware traces. It explains reading the key_averages() table with correlate_device_time=True to compare…

Google Cloud and NVIDIA Announce General Availability of NVIDIA Vera Rubin Infrastructure
NVIDIA Blog· 4 min read· Oct 21, 2026
Google Cloud and NVIDIA Announce General Availability of NVIDIA Vera Rubin Infrastructure

Google Cloud and NVIDIA announced the general availability of A5X instances built on NVIDIA Vera Rubin NVL72 GPUs, combining high‑bandwidth ConnectX‑9 SuperNICs, Virgo networking, and advanced liquid‑cooling for demanding agentic inference and reinforcement‑learning workloads. The platform will scale to as many as…

NVIDIA cuDSS Now Generally Available to Accelerate Engineering and Scientific Simulations
NVIDIA Blog· 4 min read· Oct 21, 2026
NVIDIA cuDSS Now Generally Available to Accelerate Engineering and Scientific Simulations
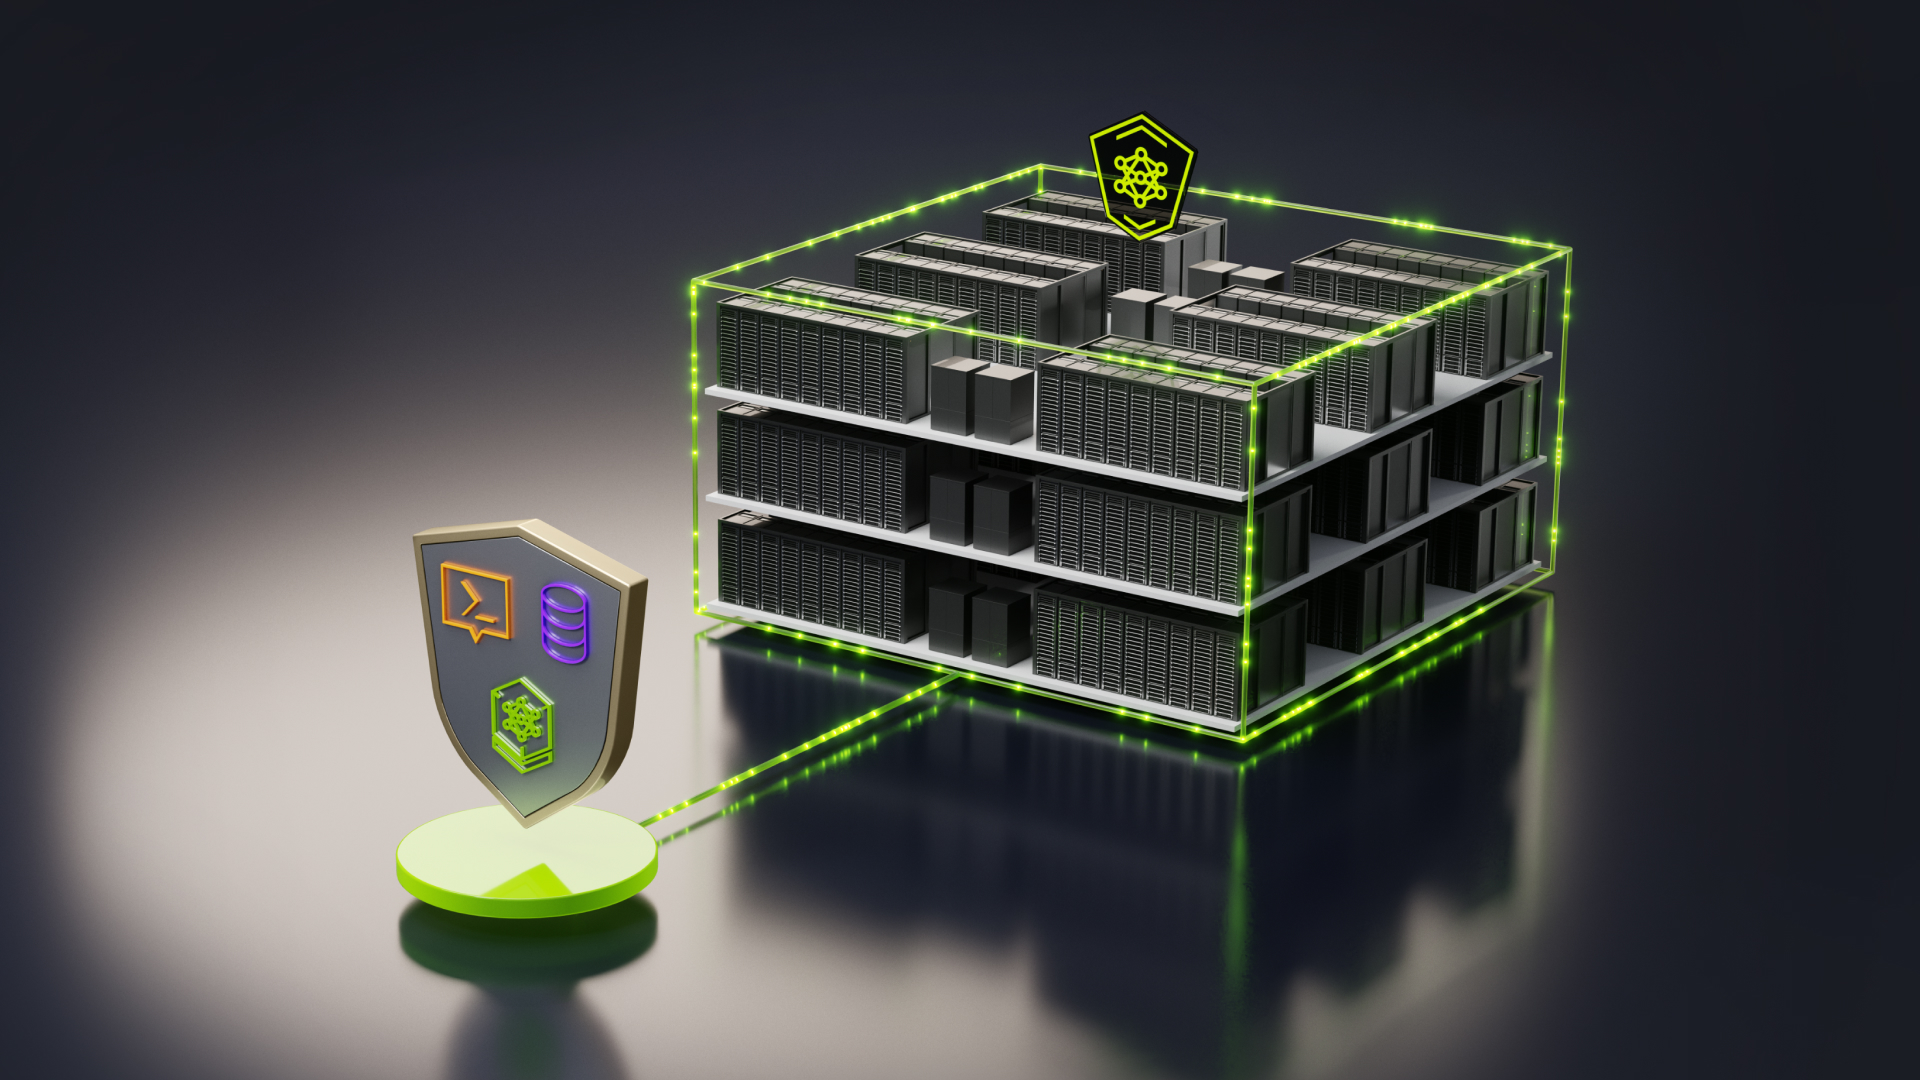
NVIDIA cuDSS, now generally available, is a CUDA‑X library that offloads large sparse linear system solves to GPUs, delivering order‑of‑magnitude speedups for engineering and scientific simulations. Reported accelerations include up to 10× on Applied Materials’ Ginestra platform, 4× on a ZEISS EUV lithography plasma…

NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure
NVIDIA Blog· 4 min read· Oct 21, 2026
NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure

NVIDIA announced the Confidential Bare Metal deployment option for its Confidential Computing stack, allowing frontier model builders to run sensitive workloads on dedicated third‑party bare‑metal infrastructure while retaining full control of models and data. The expanded security architecture now includes three…

Google unveils TorchTPU in a push to break Nvidia’s stranglehold on AI compute
SiliconANGLE AI· Oct 21, 2026
Google unveils TorchTPU in a push to break Nvidia’s stranglehold on AI compute

Google announced TorchTPU, a specialized fork of the open‑source PyTorch framework optimized for TPU hardware, aiming to erode Nvidia’s dominance in AI compute. The new library is positioned to remove a key performance advantage that Nvidia GPUs currently hold. For engineers, TorchTPU offers a pathway to leverage…

Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch
AWS ML Blog· 15 min read· Oct 20, 2026
Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch

i14’s Laplace 3B linear‑attention model replaces the KV cache with a fixed 29.5 MB recurrent state, enabling inference that scales independently of context length. Using TorchNeuron Native on an AWS trn2.48xlarge Trainium2 instance, the model trains at about 120,000 tokens / s and serves 11,544 output tokens / s…

European Leaders Turn to NVIDIA Vera CPUs to Build Local Infrastructure
NVIDIA Blog· 4 min read· Oct 20, 2026
European Leaders Turn to NVIDIA Vera CPUs to Build Local Infrastructure

NVIDIA’s new Vera CPUs are being adopted by European AI cloud providers and hardware vendors to accelerate agentic workloads that require fast CPU processing, high‑bandwidth memory, and scalable coherency. Vera’s per‑core performance, LPDDR5X memory bandwidth, and NVIDIA Scalable Coherency Fabric deliver performance…

Hugging Face ❤️ TorchTPU: TPUs, Natively
Hugging Face Blog· 5 min read· Oct 20, 2026
Hugging Face ❤️ TorchTPU: TPUs, Natively

Hugging Face + TorchTPU introduces a native PyTorch backend that makes TPUs a first‑class device, letting you load Transformers and Diffusers models with `device_map="tpu"` and run them in eager or compiled mode. The integration adds Pallas‑tuned kernels, distributed‑training support, and a `torch.compile` path for…

How Deepgram optimized voice AI at scale with AWS Trainium
AWS ML Blog· 9 min read· Oct 19, 2026
How Deepgram optimized voice AI at scale with AWS Trainium

Deepgram ported its Nova‑3 speech‑to‑text model to AWS Trainium2 using TorchNeuron and achieved an 11‑70 % increase in audio processed per dollar on batch workloads by running eight model replicas on a single trn2.3xlarge EC2 instance. The migration involved compiling the model with torch.compile, eliminating CPU…

RTX Spark Ignites Global Celebration as New Windows PCs Arrive
NVIDIA Blog· 4 min read· Oct 17, 2026
RTX Spark Ignites Global Celebration as New Windows PCs Arrive

NVIDIA introduced RTX Spark laptops featuring Blackwell RTX GPUs paired with Grace CPUs, delivering up to 1 petaflop of AI compute and up to 128 GB of unified memory in slim Windows PCs priced from $2,399. The launch spans six global retail events, with hands‑on demos showcasing local AI, content‑creation, and gaming…

Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
Hugging Face Blog· 5 min read· Oct 16, 2026
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline

The AI4Bharat + NVIDIA release introduces Nemotron‑pretraining‑Indic‑v1, a 2.8 trillion‑token corpus spanning all 22 Indian Constitution languages, generated with an open, GPU‑accelerated pipeline that performs document‑level translation, quality assessment, and targeted repair while preserving equations, tables, and…

Researchers improve weather forecasts looking two to six weeks out
MIT News AI· 7 min read· Oct 14, 2026
Researchers improve weather forecasts looking two to six weeks out

Researchers at MIT and collaborators introduced a machine‑learning model that learns to correct errors in existing dynamical forecasts, doubling forecasting accuracy for the two‑to‑six‑week horizon and achieving first place in a major international forecasting competition. The approach also beats climatologic averages…

Mixture-of-Experts kernel engineering on Amazon SageMaker AI
AWS ML Blog· 9 min read· Oct 13, 2026
Mixture-of-Experts kernel engineering on Amazon SageMaker AI

This article details kernel‑level optimizations for fused Mixture‑of‑Experts (MoE) models on Amazon SageMaker AI, focusing on leveraging NVIDIA Hopper’s Warp Group Matrix Multiply‑Accumulate (WGMMA) instructions. By restructuring the expert computation to satisfy Hopper’s fixed‑size M dimension (M = 64) and merging…

Run multi-node inference workloads using Ray LLM Deep Learning Containers
AWS ML Blog· 12 min read· Oct 12, 2026
Run multi-node inference workloads using Ray LLM Deep Learning Containers

The article demonstrates how to deploy a single large language model across two GPU nodes on Amazon EKS by leveraging Ray LLM Deep Learning Containers, partitioning the workload into dedicated prefill and decode nodes that are exposed through an OpenAI‑compatible endpoint. The pre‑built container bundles the entire…

Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod
AWS ML Blog· 31 min read· Oct 8, 2026
Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod
The article outlines a reference architecture that lets multiple teams share a single Amazon SageMaker HyperPod EKS cluster while maintaining strict isolation and fairness. By leveraging AWS IAM Identity Center for authentication, assigning each team its own SageMaker Domain and Kubernetes namespace, and enabling…

Willow taps CoreWeave to simplify AI model training
SiliconANGLE AI· Oct 8, 2026
Willow taps CoreWeave to simplify AI model training

Willow Care Inc., the team behind the AI dictation app Willow Voice, has partnered with CoreWeave Inc. to streamline its model‑training workflow by leveraging CoreWeave’s forward‑deployed support infrastructure. This approach shifts the burden of managing compute resources from the startup to CoreWeave, allowing…

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING