Home›Deployment

Deployment

Covering production AI deployment: inference infrastructure, latency optimization, cost management, monitoring, and best practices for shipping AI systems at scale.

293 articles

Deployment deep dives from the blog

All posts →
LLM Engineering

LLM Guardrails and Safety Monitoring in Production

13 min read · Read →
AI Engineering

LLM Gateway Architecture: Token Routing, Caching, and Failover in Production

12 min read · Read →
LLM Engineering

Continuous LLM Evaluation Pipelines for Production

12 min read · Read →
60 articles
Introducing workload recovery and expanded infrastructure checks on Amazon SageMaker HyperPod
AWS ML Blog· 30 min read· Today
Introducing workload recovery and expanded infrastructure checks on Amazon SageMaker HyperPod

Amazon SageMaker HyperPod now adds three resiliency capabilities—MultiNodeTrainingValidation, a Kubernetes Resource Monitoring Agent, and Hung job detection—to catch silent GPU faults, Kubernetes component failures, and stalled Slurm jobs earlier, thereby improving cluster goodput. MultiNodeTrainingValidation trains a…

Introducing Unity Gateway Insights
Databricks Blog· 6 min read· Today
Introducing Unity Gateway Insights

Introducing Unity Gateway Insights aims to help teams reduce AI spending by providing visibility into budget allocations and the use of open‑source models. The announcement highlights a focus on cost‑optimization rather than new model capabilities. Engineers can leverage the insights to better manage expenses in…

Introducing the Amazon SageMaker JumpStart Model Leaderboard
AWS ML Blog· 11 min read· Today
Introducing the Amazon SageMaker JumpStart Model Leaderboard

Amazon SageMaker JumpStart now includes a Model Leaderboard that ranks 70+ open‑weight LLMs across three public reasoning benchmarks (BIG‑Bench Hard, GPQA Diamond, MMLU‑Pro) and reports standardized performance and cost metrics measured on SageMaker endpoints. The leaderboard presents quality scores, latency, and…

How Airbnb uses cost per task to operate coding agents on Amazon Bedrock
AWS ML Blog· 17 min read· Today
How Airbnb uses cost per task to operate coding agents on Amazon Bedrock

Airbnb evaluates and monitors coding agents on Amazon Bedrock by measuring “cost per task,” the list‑price cost of all tokens needed to complete a single coding request, alongside latency, throttling, and token‑usage metrics from CloudWatch. By running side‑by‑side evals on internal task sets before rollouts and then…

Design responsible AI controls for Amazon Aurora PostgreSQL
AWS ML Blog· 20 min read· Today
Design responsible AI controls for Amazon Aurora PostgreSQL

This article shows how to implement the Explainability dimension of AWS Responsible AI for a Retrieval‑Augmented Generation (RAG) customer‑support chatbot built on Amazon Aurora PostgreSQL‑Compatible Edition. By using Aurora ML to call Amazon Bedrock models and generate pgvector embeddings directly in SQL, the design…

Introducing Gemini 4 Neon
Google DeepMind· 9 min read· Today
Introducing Gemini 4 Neon

Gemini 4 Neon is a new Google DeepMind model that delivers frontier‑level intelligence for complex software engineering, knowledge work, and scientific workflows, featuring a 1 million‑token context window and pricing of $3 / M input tokens (95 % discount for cached) and $15 / M output tokens. It ranks #2 on the Vals…

How Salesforce is advancing global-scale model serving with cross-Region inference routing in Amazon SageMaker AI
AWS ML Blog· 16 min read· Today
How Salesforce is advancing global-scale model serving with cross-Region inference routing in Amazon SageMaker AI

Salesforce’s Agentforce Foundation team solved capacity fragmentation across 30+ global AWS Regions by deploying a managed, capacity‑aware cross‑Region inference router as a regional SageMaker AI resource. The router lets applications invoke a single endpoint with a routing‑target name, automatically forwarding each…

DaisyRose-27B: Pushing the Frontier of Post-Training Efficiency
Hugging Face Blog· 5 min read· Today
DaisyRose-27B: Pushing the Frontier of Post-Training Efficiency

DaisyRose-27B, built on Qwen3.8-27B and fine‑tuned with the Miles RL framework, doubles Terminal‑Bench 4.1 pass@1 from 5.6 % to 12.0 % after 18 days of training on 144 H200 GPUs using only 1,200 curated long‑horizon tasks. The model retains a 256K‑token context window, image understanding, and the original…

How Social Department built culture-aware video discovery
AWS ML Blog· 20 min read· Today
How Social Department built culture-aware video discovery

Social Department built QuickSearch, a set of single‑action retrieval pipelines (Shareable Scenes, Quotable Quotes, Memeable Moments, Trend Align) that let marketers find culturally resonant video clips without typing detailed queries. The pipelines run on Amazon Bedrock using TwelveLabs Marengo 3.0 and Pegasus 1.2…

Connect Amazon Bedrock AgentCore Gateway to private APIs in a hub-and-spoke network with centralized inspection
AWS ML Blog· 18 min read· Today
Connect Amazon Bedrock AgentCore Gateway to private APIs in a hub-and-spoke network with centralized inspection

This article presents a hub‑and‑spoke networking pattern that lets Amazon Bedrock AgentCore Gateway call private REST APIs and Model Context Protocol (MCP) servers while forcing all traffic through a central firewall. The solution uses an Amazon VPC Lattice resource gateway—either created by AgentCore in managed mode…

How Stretto built an AI voice agent with Amazon Nova 2 Sonic
AWS ML Blog· 14 min read· Today
How Stretto built an AI voice agent with Amazon Nova 2 Sonic

Stretto created “Tara,” an AI voice agent that replaces web‑form bankruptcy intake with a phone‑based, speech‑to‑speech interview powered by Amazon Nova 2 Sonic, a foundation model available through Amazon Bedrock. By using a single model for both speech recognition and generation, the system reduces latency and…

Mathematical proof, powered by AI. And no hallucinations!
Amazon Science· 8 min read· Today
Mathematical proof, powered by AI. And no hallucinations!

The post announces new tools in the AutoCorrode verification suite that let AI agents interact directly with Isabelle proof assistants via the Model Context Protocol (MCP), enabling both full control (I/Q) and collaborative proof development (I/R). It also introduces Isabelle Assistant, a chat‑based interface powered…

How AUMOVIO centralized AI access with Databricks Unity Gateway
Databricks Blog· 6 min read· Today
How AUMOVIO centralized AI access with Databricks Unity Gateway

AUMOVIO implemented a centralized AI access layer using Databricks Unity Gateway to streamline and secure interactions with large language models across its teams. The solution consolidates disparate model access patterns into a single entry point, reducing integration overhead and improving governance. Engineers can…

How we raised Databricks cluster rate limits by 7.5×
Databricks Blog· 6 min read· Yesterday
How we raised Databricks cluster rate limits by 7.5×

The Compute Platform team at Databricks increased the cluster rate limits by 7.5×, enabling far higher throughput for cluster provisioning. This change directly expands the capacity of Databricks workloads without requiring additional hardware. Engineers can now scale job execution more aggressively while staying…

Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference
AWS ML Blog· 11 min read· Yesterday
Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference

Amazon SageMaker HyperPod Inference now integrates NVIDIA Dynamo, an open‑source distributed inference framework, to enable multi‑node, disaggregated prefill/decode serving for LLMs whose FP8 weights exceed the 640 GB GPU memory of a single ml.p5.48xlarge instance. Dynamo’s KV‑aware routing and support for engines…

Dell bets liquid-cooled, software-defined storage can keep AI factories fed
SiliconANGLE AI· Yesterday
Dell bets liquid-cooled, software-defined storage can keep AI factories fed

Dell Technologies is positioning its PowerEdge servers with liquid‑cooled, software‑defined storage to handle the growing density of AI factories, enabling nodes to switch roles as workloads shift from training to inference and agents. By integrating flexible storage directly into compute racks, Dell aims to reduce…

Cut generative AI costs: Code for rules, models for judgment
AWS ML Blog· 13 min read· Yesterday
Cut generative AI costs: Code for rules, models for judgment

This article presents a decision flow for determining when a generative‑AI step truly requires a model, advocating deterministic code or constrained calls wherever possible to cut spend, latency, and nondeterminism. It outlines three sequential questions—rule‑check, model‑generated rule, and fixed‑list selection—and…

Amazon SageMaker AI real-time endpoints now support KV cache aware routing
AWS ML Blog· 22 min read· Yesterday
Amazon SageMaker AI real-time endpoints now support KV cache aware routing
Amazon SageMaker AI adds KV‑cache‑aware routing (KV_AWARE) for real‑time endpoints, allowing the router to direct each request to an instance that already holds the matching KV cache and isn’t overloaded. The model container reports cache events via the SM_VLLM_KV_EVENTS_CONFIG environment variable, and the endpoint’s…

Idle, then spiking: Why AI agents are breaking Kubernetes resource planning
SiliconANGLE AI· Yesterday
Idle, then spiking: Why AI agents are breaking Kubernetes resource planning

AI agents cause workloads to remain idle for extended periods and then generate sudden resource spikes, which undermines static Kubernetes resource configurations. This unpredictable usage pattern forces platform teams to adopt autonomous orchestration to dynamically adjust resources. The shift highlights the need for…

Microsoft rolls out new first-party models and updates to agentic AI continuous improvement
SiliconANGLE AI· Yesterday
Microsoft rolls out new first-party models and updates to agentic AI continuous improvement

Microsoft announced the rollout of new first‑party generative AI models and enhancements to its Foundry platform, including updates to Foundry IQ that now ship an enterprise knowledge graph out of the box to support autonomous agents. The announcement highlights tighter integration of model grounding, testing, and…

Announcing AI data preparation capabilities in Amazon SageMaker: Build high-quality datasets for model development workflows
AWS ML Blog· 8 min read· Yesterday
Announcing AI data preparation capabilities in Amazon SageMaker: Build high-quality datasets for model development workflows

Amazon SageMaker now includes AI Data Preparation capabilities that let engineers generate synthetic data, auto‑label datasets, evaluate data quality, and apply transformations via Python SDK APIs and the AWS AI‑ML agent skill, all without building custom pipelines. The auto‑labeling feature uses a jury of multiple…

Getting AI out of the demo and into businesses globally
AWS ML Blog· 11 min read· Yesterday
Getting AI out of the demo and into businesses globally

AWS Forward Deployed Engineering (FDE) launched in June and is now available in 15 countries, offering production‑ready accelerators that help enterprises move AI from prototype to scale. The service emphasizes building a shared foundation of identity, security, context, governance, and operational controls,…

Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart
AWS ML Blog· 19 min read· Yesterday
Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart

OpenTSLM, an open‑source family of time‑series language models (TSLMs) from Aionic Labs, is now available through Amazon SageMaker JumpStart, enabling engineers to deploy models that combine numerical measurements with textual context for proactive IT assistance. The models ingest device telemetry (e.g., CPU, memory,…

Responsible AI for agentic AI: A phased roadmap for platform and application teams
AWS ML Blog· 15 min read· Yesterday
Responsible AI for agentic AI: A phased roadmap for platform and application teams
This article outlines a three‑phase Responsible AI (RAI) roadmap for teams building agentic AI platforms, mapping AWS Responsible AI Lens pillars to governance foundations, pilot deployment, and evaluation/hardening stages. It highlights a real‑world case where Robinhood used a generative AI financial‑crimes agent on…

Three insights you might have missed from theCUBE’s coverage of Dell’s “AI Leadership Symposium”
SiliconANGLE AI· Yesterday
Three insights you might have missed from theCUBE’s coverage of Dell’s “AI Leadership Symposium”

Dell Technologies’ “AI Leadership Symposium” highlighted the practical challenges CIOs face when moving enterprise AI workloads into production, focusing on cost management, scaling infrastructure, and establishing governance to keep AI agents in check and data secure. The discussion underscored that expanding AI…

Modernizing mainframe Assembler to Java using Amazon Bedrock and AWS Transform
AWS ML Blog· 16 min read· 2 days ago
Modernizing mainframe Assembler to Java using Amazon Bedrock and AWS Transform

This article outlines a five‑phase methodology for modernizing legacy mainframe Assembler applications by first converting them to COBOL and then to Java Spring Boot services using Amazon Bedrock, Kiro IDE, and AWS Transform. The approach leverages AI‑assisted code analysis and foundation models in Bedrock to extract…

NVIDIA Expands Slurm to Bring Quantum Computing Into Supercomputing
NVIDIA Blog· 4 min read· 2 days ago
NVIDIA Expands Slurm to Bring Quantum Computing Into Supercomputing

NVIDIA’s new Slurm 26.11 release adds native quantum‑processor support, letting supercomputing centers schedule QPUs through the same workflow used for CPUs/GPUs and leveraging the QRMI and QDMI interfaces. The update also bundles a community‑driven orchestration layer for the CUDA‑Q open platform, including a…

Best practices for writing Denied Topics in Amazon Bedrock Guardrails
AWS ML Blog· 31 min read· 2 days ago
Best practices for writing Denied Topics in Amazon Bedrock Guardrails
Amazon Bedrock Guardrails’ Denied Topics block content by semantic meaning rather than keyword matching, which can cause over‑blocking (e.g., “When does my direct deposit clear?” being caught by a Finance topic) or under‑blocking due to vague definitions. The article identifies four common authoring pitfalls—topic…

Serving Scikit-LLM Pipelines as REST APIs with FastAPI
Machine Learning Mastery· 2 days ago
Serving Scikit-LLM Pipelines as REST APIs with FastAPI

This article demonstrates how to expose a Scikit‑LLM zero‑shot text classification pipeline, backed by a locally hosted Ollama model, as a RESTful service using FastAPI. It walks through wiring the Scikit‑LLM pipeline into a FastAPI endpoint, enabling HTTP‑based inference without external hosting. Engineers can thus…

AI Day Seoul Brings Together Korea’s Industry Leaders, Startups and Developer Communities
NVIDIA Blog· 4 min read· 3 days ago
AI Day Seoul Brings Together Korea’s Industry Leaders, Startups and Developer Communities

NVIDIA’s AI Day Seoul showcased Korean industry leaders and startups leveraging NVIDIA platforms to build physical AI and agentic systems, highlighted by Deepu Talla’s remarks on the country’s rapid robotics adoption. The event featured hands‑on workshops on deploying and optimizing AI inference at scale with the…

Production MLOps at GS Caltex with Amazon SageMaker Canvas, part 1
AWS ML Blog· 16 min read· 5 days ago
Production MLOps at GS Caltex with Amazon SageMaker Canvas, part 1

GS Caltex accelerated its MLOps by linking Amazon SageMaker Canvas‑built models to SageMaker Pipelines, cutting deployment time from about a week to a few hours. Engineers use Canvas for visual data prep (Data Wrangler) and model training, then register the model in the SageMaker Model Registry. ML engineers convert…

Route coding agent requests to the right model on Amazon Bedrock with NVIDIA NeMo Switchyard
AWS ML Blog· 22 min read· 5 days ago
Route coding agent requests to the right model on Amazon Bedrock with NVIDIA NeMo Switchyard

This article demonstrates how to route coding‑agent requests on Amazon Bedrock using NVIDIA NeMo Switchyard integrated with LiteLLM. By deploying LiteLLM v1.102.0 and the Switchyard server 0.3.0 container via AWS CDK, you can apply stage‑routing (based on recent tool activity) or random‑routing (with optional weights)…

Architecture patterns for fast session startup on Amazon Bedrock AgentCore runtime
AWS ML Blog· 18 min read· 5 days ago
Architecture patterns for fast session startup on Amazon Bedrock AgentCore runtime

Amazon Bedrock AgentCore runtime V2 introduces a snapshot‑based startup that prepares the container once, freezes the microVM, and restores the snapshot for each new session, cutting cold‑start latency to roughly 2 seconds and reclaiming unused memory for cost efficiency. Engineers can achieve sub‑second latency by…

Cost-optimizing AssemblyAI speech-to-text inference on AWS with Amazon EC2 Spot
AWS ML Blog· 7 min read· 5 days ago
Cost-optimizing AssemblyAI speech-to-text inference on AWS with Amazon EC2 Spot

AssemblyAI built a cost‑optimized speech‑to‑text inference platform on AWS by mixing Amazon EC2 Spot and On‑Demand GPU instances within Amazon ECS clusters and using an Amazon SQS‑based retry loop to survive Spot interruptions. The fleet runs thousands of GPUs across multiple instance families (g4dn.xlarge,…

Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture
AWS ML Blog· 30 min read· 5 days ago
Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture

Amazon SageMaker HyperPod now includes a built‑in Data Capture feature that records live inference inputs and outputs to Amazon S3 across three independent tiers with minimal latency and no impact on model availability. The post demonstrates a full flywheel on a single HyperPod cluster: capture production traffic,…

Build a Robot Pick-and-Place Simulation with SimReady Assets
Hugging Face Blog· 8 min read· 5 days ago
Build a Robot Pick-and-Place Simulation with SimReady Assets
This walkthrough demonstrates building a pick-and-place simulation in Isaac Sim 6.2 using SimReady assets for the UR17G arm, Robotiq 2F‑140 gripper, and a beverage can, with validation of joint limits, drive settings, and contact behavior. It also shows how a frontier AI model (GPT‑6 Sol) can generate the task code to…

Agents idling while they wait on humans push Kubernetes to hand back unused resources
SiliconANGLE AI· 5 days ago
Agents idling while they wait on humans push Kubernetes to hand back unused resources

Enterprises are observing AI agents idling while awaiting human input, prompting Kubernetes to reclaim the now‑unused compute resources. This shift highlights Kubernetes as a critical component for managing autonomous software workloads rather than just a static container orchestrator. Engineers must consider dynamic…

llama.cpp v1.0.0 : A stronger foundation for the local AI ecosystem
Hugging Face Blog· 5 min read· 5 days ago
llama.cpp v1.0.0 : A stronger foundation for the local AI ecosystem
llama.cpp v1.0.0 launches a stable, version‑bumped API/ABI for the ggml inference engine, now supporting more than 150 architecture variants and a suite of hardware‑specific backends (NVIDIA, AMD, Qualcomm, Arm, IBM, Intel). The release emphasizes semantic‑versioning rules, CI scalability via Hugging Face Buckets and…

CNCF data shows cloud native is the on-ramp to AI, and maintainers are paying the price
SiliconANGLE AI· 6 days ago
CNCF data shows cloud native is the on-ramp to AI, and maintainers are paying the price
The CNCF State of Cloud Native Development report reveals that the global cloud‑native developer population has surpassed 21 million and that AI is increasingly influencing the projects they contribute to, turning cloud‑native ecosystems into a primary entry point for AI workloads. This shift is creating additional…

As AI agents take control, Nvidia rethinks the security playbook
SiliconANGLE AI· 6 days ago
As AI agents take control, Nvidia rethinks the security playbook

Nvidia introduced **Scale‑In**, a new pillar in its AI networking stack that provides purpose‑built acceleration for securing, managing, and operating “agentic AI factories.” The offering focuses on secure access, high‑performance data movement, tenant isolation, simpler operations, and more predictable performance as…

Kubernetes gets a second act as AI agents turn one prompt into thousands of inference calls
SiliconANGLE AI· 6 days ago
Kubernetes gets a second act as AI agents turn one prompt into thousands of inference calls

Kubernetes is being repurposed to orchestrate the massive number of inference calls generated by agentic AI systems, where a single user prompt can trigger thousands of downstream model invocations. The platform’s reliability and predictability are leveraged to manage this surge as AI spending shifts from model…

Tokenomics at scale: Track and cap Amazon Bedrock spend per IAM principal with CUR 2.0 and AWS Budgets
AWS ML Blog· 14 min read· 6 days ago
Tokenomics at scale: Track and cap Amazon Bedrock spend per IAM principal with CUR 2.0 and AWS Budgets

This article shows how to achieve per‑IAM‑principal cost visibility and automatic spend caps for Amazon Bedrock using only native AWS services—Cost and Usage Reports 2.0 (or Cost Explorer), cost allocation tags, and AWS Budgets with budget actions that enforce a deny IAM policy when a threshold is exceeded. By…

Optimizing cost per task and proving agent ROI on Amazon Bedrock
AWS ML Blog· 14 min read· 6 days ago
Optimizing cost per task and proving agent ROI on Amazon Bedrock

This article introduces a cost‑per‑task framework for Amazon Bedrock that surfaces four hidden cost drivers—tokenizer efficiency, output alignment, agentic loop efficiency, and output verbosity—showing that a model with a 15 % lower list price can be up to 40 % more expensive due to token inflation. It details…

Building a self-service LLM gateway with Amazon Bedrock and LiteLLM
AWS ML Blog· 18 min read· 6 days ago
Building a self-service LLM gateway with Amazon Bedrock and LiteLLM

This article details how to construct a self‑service LLM gateway that fronts Amazon Bedrock models (e.g., Claude Sonnet and Claude Haiku) with LiteLLM running on AWS Fargate, exposing an OpenAI‑compatible API. The pattern leverages Amazon Route 53, CloudFront, an ALB, and per‑user API keys stored in Amazon RDS…

Run agents securely and efficiently with the next generation AgentCore runtime
AWS ML Blog· 9 min read· 6 days ago
Run agents securely and efficiently with the next generation AgentCore runtime

Amazon Bedrock AgentCore’s new runtime delivers hardware‑isolated Firecracker MicroVM sessions that start up to 15× faster, can scale to 4× more compute, and run up to 68 % more efficiently while preserving isolation. The updates let agents dynamically increase memory and CPU within each session, supporting heavier…

How H6.ai builds AI-powered financial automation with Lakebase Postgres
Databricks Blog· 6 min read· 6 days ago
How H6.ai builds AI-powered financial automation with Lakebase Postgres

H6.ai leverages Lakebase Postgres to power AI-driven accounts payable and invoice processing, reducing manual effort in financial workflows. By integrating AI models directly with a Postgres‑based data lake, the system can ingest, classify, and extract invoice data at scale. This architecture enables engineers to…

Migrate to Amazon Bedrock Managed Knowledge Base with your coding agent
AWS ML Blog· 19 min read· 6 days ago
Migrate to Amazon Bedrock Managed Knowledge Base with your coding agent

The article announces a migration guide in the AWS Agent Toolkit that lets a coding agent help move a customer‑managed Amazon Bedrock knowledge base to the new Amazon Bedrock Managed Knowledge Base service. Managed Knowledge Base offloads vector store provisioning, embedding model tuning, hybrid search, reranking and…

From prototype to production: Engineering agents with Agent DLC
AWS ML Blog· 15 min read· 6 days ago
From prototype to production: Engineering agents with Agent DLC
The article introduces the Agent Development Lifecycle (Agent DLC), a framework for moving AI agents from prototype to production by adding systematic checks for non‑determinism, prompt/tool changes, and external dependency drift. It mandates running each test case k times to evaluate pass‑rate distributions,…

Qvyon launches with $8M to improve safety for physical AI deployments
SiliconANGLE AI· 6 days ago
Qvyon launches with $8M to improve safety for physical AI deployments
Qvyon Technologies Inc. has raised $8 million in total funding—led by MaC Venture Capital with participation from BDC Capital and BKR Capital—to launch a physical AI validation platform that helps companies test autonomous vehicles and robots before deployment. The new infrastructure focuses on safety verification,…

Google’s GKE Labs turns reinforcement learning into a Kubernetes workload
SiliconANGLE AI· Nov 12, 2026
Google’s GKE Labs turns reinforcement learning into a Kubernetes workload
Google’s GKE Labs project packages reinforcement‑learning‑based model fine‑tuning as a native Kubernetes workload, unifying training, inference, and sandboxed agent execution into a single loop. By containerizing the RL pipeline, engineers can leverage standard K8s scheduling, scaling, and isolation mechanisms for…

Google enters decision model market with Gemini Decisions API
SiliconANGLE AI· Nov 12, 2026
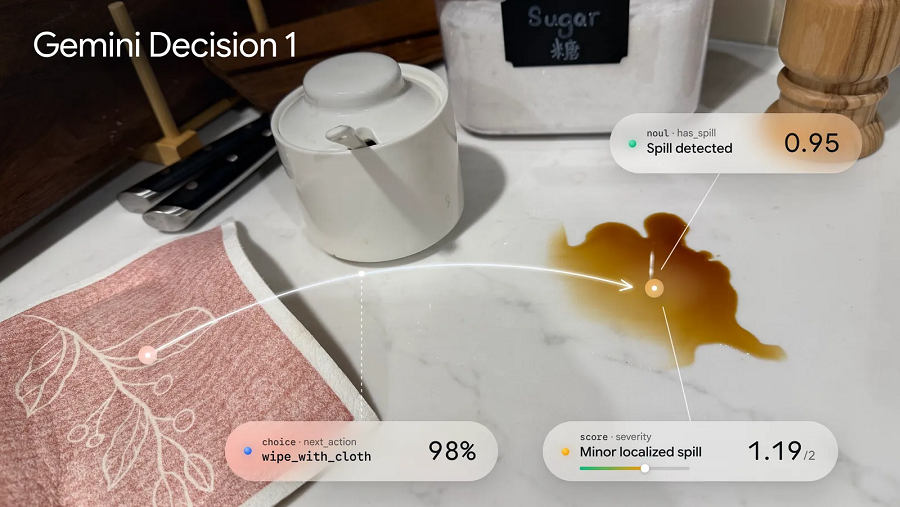
Google enters decision model market with Gemini Decisions API

Google has unveiled the Gemini Decisions API, a new AI service built on the Gemini Decision 1 model that focuses on narrow, cost‑efficient decision‑making queries rather than general conversation. The API is positioned to provide faster, cheaper responses for specific user questions, trading breadth for efficiency.…

Build autonomous AI agents with Amazon Bedrock and Spring AI
AWS ML Blog· 21 min read· Nov 12, 2026
Build autonomous AI agents with Amazon Bedrock and Spring AI

Amazon Bedrock AgentCore combined with Spring AI lets Java teams build autonomous AI agents that can plan, invoke tools, and retain memory across multi‑turn conversations, all using familiar Spring patterns and managed runtime infrastructure. The walkthrough demonstrates a single‑agent travel assistant (tool calling +…

The Definitive Fine-Tuning Guide for 3D Generation Models
Hugging Face Blog· 14 min read· Nov 12, 2026
The Definitive Fine-Tuning Guide for 3D Generation Models

This guide releases fine‑tuning scripts and container images for adapting the TRELLIS.2 3‑D generation model to custom assets, using LoRA adapters via Hugging Face’s PEFT library. In experiments on a 188‑item footwear subset of the Google Scanned Objects (GSO) dataset, LoRA improves sole geometry that the pretrained…

OpenAI Codex on Amazon Bedrock
AWS ML Blog· 14 min read· Nov 11, 2026
OpenAI Codex on Amazon Bedrock

OpenAI Codex can invoke Bedrock‑hosted OpenAI models such as GPT‑5.6 Sol from a developer workstation, and Amazon provides three rollout patterns—Native AWS Access, AgentCore Gateway, and LLM Gateway—to align inference with existing IAM, regional, and observability controls. The quick‑start repository supplies…

Detecting and recovering from silent data corruption on Amazon SageMaker HyperPod
AWS ML Blog· 37 min read· Nov 11, 2026
Detecting and recovering from silent data corruption on Amazon SageMaker HyperPod

The authors introduce three lightweight checks integrated into a PyTorch DistributedDataParallel (DDP) loop that detect silent data corruption on Amazon SageMaker HyperPod, pinpoint the faulty GPU node, and trigger automatic node recovery. The checks compare intermediate tensor values against a reference checksum,…

The attendee’s guide to the AWS re:Invent 2026 AI/ML track
AWS ML Blog· 23 min read· Nov 11, 2026
The attendee’s guide to the AWS re:Invent 2026 AI/ML track

The guide outlines AWS re:Invent 2026’s AI/ML track, highlighting over 140 sessions across breakout, chalk‑talk, builder, workshop, code‑talk, and lightning‑talk formats. It maps the AWS AI stack—from AI‑optimized data centers and Trainium or NVIDIA GPU chips to the AWS Context data foundation—so attendees can target…

How DXC Technology built a multi-model AI substrate on Amazon Bedrock
AWS ML Blog· 13 min read· Nov 11, 2026
How DXC Technology built a multi-model AI substrate on Amazon Bedrock

DXC Technology built a governed multi‑model AI substrate on Amazon Bedrock that unifies access to Anthropic Claude, Amazon Nova, Meta Llama and other open‑weight families via a single API, while enforcing Bedrock Guardrails for content filtering, PII redaction, and denied‑topic policies. System‑level controls such as…

Accelerating generative AI delivery with reusable assets
AWS ML Blog· 13 min read· Nov 11, 2026
Accelerating generative AI delivery with reusable assets

The AWS Generative AI Innovation Center now offers a catalog of 23 production‑ready, open‑source reusable assets—including RAG pipeline components, document ingestion modules, and agent scaffolding templates—that can shrink development cycles from months to weeks. Customers such as DoorDash, Lyft, and Ricoh have…

Introducing usage-based pricing for Amazon SageMaker AI bidirectional streaming
AWS ML Blog· 12 min read· Nov 11, 2026
Introducing usage-based pricing for Amazon SageMaker AI bidirectional streaming

Amazon SageMaker AI now supports usage‑based metering for bidirectional streaming inference, enabling model providers to bill AWS Marketplace customers based on actual streamed usage rather than static endpoint time. The feature adds a companion WebSocket metadata stream (opened at…

AlphaGenome 2: Deciphering how cells read DNA to better understand disease
Google DeepMind· 9 min read· Nov 11, 2026
AlphaGenome 2: Deciphering how cells read DNA to better understand disease

AlphaGenome 2 is a conditional DNA‑sequence model that predicts the impact of genetic variants on gene expression in specific human cell types and states, improving variant detection nearly two‑fold over its predecessor. Trained on more than 100 million single‑cell profiles spanning 68 tissues, it ingests a…

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING