Home›RAG

RAG

Retrieval-Augmented Generation (RAG) connects LLMs to external knowledge sources at inference time, enabling accurate, up-to-date answers without retraining. A core pattern in production AI systems.

39 articles

RAG deep dives from the blog

All posts →
AI Engineering

RAG vs. Agent Memory: When to Use Which

11 min read · Read →
LLMs

Fine-Tuning vs RAG vs Prompting: A Practical Decision Tree for Engineers

8 min read · Read →
39 articles
Design responsible AI controls for Amazon Aurora PostgreSQL
AWS ML Blog· 20 min read· Today
Design responsible AI controls for Amazon Aurora PostgreSQL

This article shows how to implement the Explainability dimension of AWS Responsible AI for a Retrieval‑Augmented Generation (RAG) customer‑support chatbot built on Amazon Aurora PostgreSQL‑Compatible Edition. By using Aurora ML to call Amazon Bedrock models and generate pgvector embeddings directly in SQL, the design…

Graph-RAG for Enterprise Documents: Building a Knowledge Graph from PDFs, Wikis, and Databases
Machine Learning Mastery· Today
Graph-RAG for Enterprise Documents: Building a Knowledge Graph from PDFs, Wikis, and Databases
The article introduces a Graph‑RAG approach for enterprise documents, aiming to construct a knowledge graph from sources such as PDFs, wikis, and databases. Not mentioned. It suggests that Python 3 is a prerequisite for implementation. Not mentioned. Engineers can consider this method when needing structured retrieval…

Local LLMs Handle Textbook RAG but Fail on New Research Papers
Towards Data Science· 2 days ago
Local LLMs Handle Textbook RAG but Fail on New Research Papers

Local large language models achieve strong Retrieval‑Augmented Generation (RAG) results on textbook material, scoring between 12 and 20 out of 20, but their performance collapses on recently published research papers, dropping to 0‑9 out of 15. The evaluation used five different setups and a blind grading pack to…

A Practitioner's Guide to 6 Agentic GraphRAG Patterns
Towards Data Science· 3 days ago
A Practitioner's Guide to 6 Agentic GraphRAG Patterns

This article explains how autonomous agents can transform static knowledge graphs into dynamic “Context Graphs” that retain decisions, user intent, and operational history. It outlines six distinct Agentic GraphRAG patterns that enable agents to continuously update and query graph‑based knowledge. By leveraging these…

The Complete Guide to LLM Evaluation
Machine Learning Mastery· 5 days ago
The Complete Guide to LLM Evaluation

The article presents a systematic approach to evaluating large language model (LLM) applications, covering the selection of scoring metrics, the construction of reliable LLM judges, and methods for assessing retrieval‑augmented generation (RAG) systems. It outlines best‑practice design patterns for evaluation…

RAG Retrieval Lost 40 Points When Distracting Passages Grew to 2.68M
Towards Data Science· 6 days ago
RAG Retrieval Lost 40 Points When Distracting Passages Grew to 2.68M

A reproducible evaluation shows that RAG retrieval performance can drop dramatically—by 40 points—when the corpus of distracting passages expands to 2.68 M documents. The study compares BM25, dense embeddings, and parent‑document strategies, revealing that author‑written evals tend to overestimate search quality and…

Accelerating generative AI delivery with reusable assets
AWS ML Blog· 13 min read· Nov 11, 2026
Accelerating generative AI delivery with reusable assets

The AWS Generative AI Innovation Center now offers a catalog of 23 production‑ready, open‑source reusable assets—including RAG pipeline components, document ingestion modules, and agent scaffolding templates—that can shrink development cycles from months to weeks. Customers such as DoorDash, Lyft, and Ricoh have…

Single-shot and agentic retrieval with Amazon Bedrock Managed Knowledge Base
AWS ML Blog· 13 min read· Nov 9, 2026
Single-shot and agentic retrieval with Amazon Bedrock Managed Knowledge Base

Amazon Bedrock Managed Knowledge Base now adds single-shot Retrieval‑Augmented Generation (RAG) and retrieval‑only requests via AgenticRetrieveStream, letting developers choose between a one‑pass search‑and‑generate flow or a pure passage return. Single-shot RAG performs a single search and uses a foundation model to…

Prepare web content for Amazon Bedrock Knowledge Bases with Crawl4AI
AWS ML Blog· 22 min read· Nov 2, 2026
Prepare web content for Amazon Bedrock Knowledge Bases with Crawl4AI

Amazon Bedrock Knowledge Bases provides a fully managed RAG pipeline that can ingest web content via the built‑in Web Crawler connector, but for sites that require content pruning, targeted extraction, or custom metadata you can prepend a preparation step using the open‑source Crawl4AI Python crawler, which writes…

When Labels Say No, But Embeddings Say Yes
Towards Data Science· Oct 29, 2026
When Labels Say No, But Embeddings Say Yes

The article argues that conventional retrieval metrics often overlook semantically meaningful similarities that can be captured by embedding-based approaches. It highlights a mismatch where label-based evaluations reject relevant results that embeddings would deem similar. This suggests engineers should complement…

Your RAG Pipeline Is Missing a 1994 Algorithm
Towards Data Science· Oct 28, 2026
Your RAG Pipeline Is Missing a 1994 Algorithm

The article highlights that typical RAG pipelines rely on embeddings that capture semantic similarity (e.g., “broken” ↔ “defective”) but may miss exact string matching nuances such as distinguishing “ZX-4821” from “ZX-4812”. It suggests incorporating a classic 1994 algorithm to improve token-level precision in…

Building live intelligence: Databricks AI Search supports Streaming Tables, Materialized Views, and Managed tables using Iceberg
Databricks Blog· 6 min read· Oct 26, 2026
Building live intelligence: Databricks AI Search supports Streaming Tables, Materialized Views, and Managed tables using Iceberg

Databricks AI Search now natively supports Streaming Tables, Materialized Views, and Managed tables built on Iceberg, extending its retrieval capabilities to real‑time and curated data sources. This integration enables AI‑driven queries over continuously updated data without requiring separate ETL pipelines. Engineers…

How IskayPet unified corporate knowledge with Amazon Bedrock Managed Knowledge Bases
AWS ML Blog· 11 min read· Oct 22, 2026
How IskayPet unified corporate knowledge with Amazon Bedrock Managed Knowledge Bases

IskayPet built a multilingual corporate knowledge assistant using Amazon Bedrock Managed Knowledge Bases and Claude Haiku 4.5, eliminating the need to operate their own vector stores, embedding pipelines, or ingestion jobs. The solution leverages Bedrock’s native SharePoint connector for direct ingestion and its…

Does Agentic RAG Actually Retrieve Better Evidence? I Tested It on 298 Questions
Towards Data Science· Oct 22, 2026
Does Agentic RAG Actually Retrieve Better Evidence? I Tested It on 298 Questions

The article evaluates an agentic Retrieval‑Augmented Generation (RAG) system by running it on 298 questions, allowing the AI agent to re‑search whenever it chose. The agent uncovered some papers missed by a plain search but also lost others, resulting in a net gain that the author deems insufficient to trust the…

How to Build a Multi-Modal RAG Pipeline for Images and Documents in Python
Machine Learning Mastery· Oct 21, 2026
How to Build a Multi-Modal RAG Pipeline for Images and Documents in Python

This article explains how to construct a multi‑modal Retrieval‑Augmented Generation (RAG) pipeline in Python that can retrieve and reason over both text and images extracted from documents. Not mentioned specific model names, benchmark results, or architectural details. Engineers can apply the described approach to…

Evaluating Graph-RAG vs. Standard RAG: A Hallucination Benchmark on Fact-Dense Queries
Machine Learning Mastery· Oct 8, 2026
Evaluating Graph-RAG vs. Standard RAG: A Hallucination Benchmark on Fact-Dense Queries

This article benchmarks a deterministic 3‑Tiered Graph‑RAG system against a standard vector RAG pipeline on fact‑dense queries, revealing differences in hallucination rates between the two approaches. While specific quantitative results are not disclosed, the comparison highlights how graph‑based retrieval can improve…

Rethinking access control for RAG with Amazon Quick and Amazon Bedrock
AWS ML Blog· 6 min read· Oct 7, 2026
Rethinking access control for RAG with Amazon Quick and Amazon Bedrock

Amazon Quick and Amazon Bedrock Knowledge Bases introduce real‑time ACL enforcement for Retrieval‑Augmented Generation, shifting permission verification from periodic syncs to authoritative checks at query time. This design eliminates reliance on stale, replicated ACL snapshots and removes the need for each connector…

How Qlik built grounded, enterprise-scale AI with Amazon Bedrock
AWS ML Blog· 10 min read· Oct 7, 2026
How Qlik built grounded, enterprise-scale AI with Amazon Bedrock

Qlik deployed its Qlik Answers platform on Amazon Bedrock, enabling 40,000+ customers to receive grounded, sourced answers from both structured and unstructured enterprise data. The solution uses a layered, multi‑agent architecture that routes inference requests across regions and leverages Bedrock Guardrails to…

Adding Temporal Reasoning to Graph-RAG: Tracking Fact Freshness and Staleness
Machine Learning Mastery· Oct 1, 2026
Adding Temporal Reasoning to Graph-RAG: Tracking Fact Freshness and Staleness

This article demonstrates how to integrate a lightweight temporal reasoning layer into a Graph‑RAG architecture, enabling the system to differentiate between fresh and stale facts. By tracking fact timestamps and applying freshness heuristics, the enhanced Graph‑RAG can prioritize up‑to‑date information during…

GraphRAG with TypeSafe Jev: A System One Approach to Scalable Knowledge Graphs
Towards Data Science· Sep 27, 2026
GraphRAG with TypeSafe Jev: A System One Approach to Scalable Knowledge Graphs

The article introduces GraphRAG with TypeSafe Jev as a System One approach that combines calibrated decision models for high‑frequency graph decisions with LLMs dedicated to reasoning, synthesis, and open‑ended generation, aiming to build scalable knowledge graphs.

RAG Isn't an Agent — I Built the Layer Between Retrieval and Action
Towards Data Science· Sep 25, 2026
RAG Isn't an Agent — I Built the Layer Between Retrieval and Action
The article argues that Retrieval-Augmented Generation (RAG) and agents serve distinct functions—RAG focuses on retrieval while agents handle action—and describes a custom integration layer that explicitly connects the two, evaluating nine tasks across three system configurations.

RAG vs. Fine-Tuning for Domain Adaptation: When to Use Which
Machine Learning Mastery· Sep 23, 2026
RAG vs. Fine-Tuning for Domain Adaptation: When to Use Which
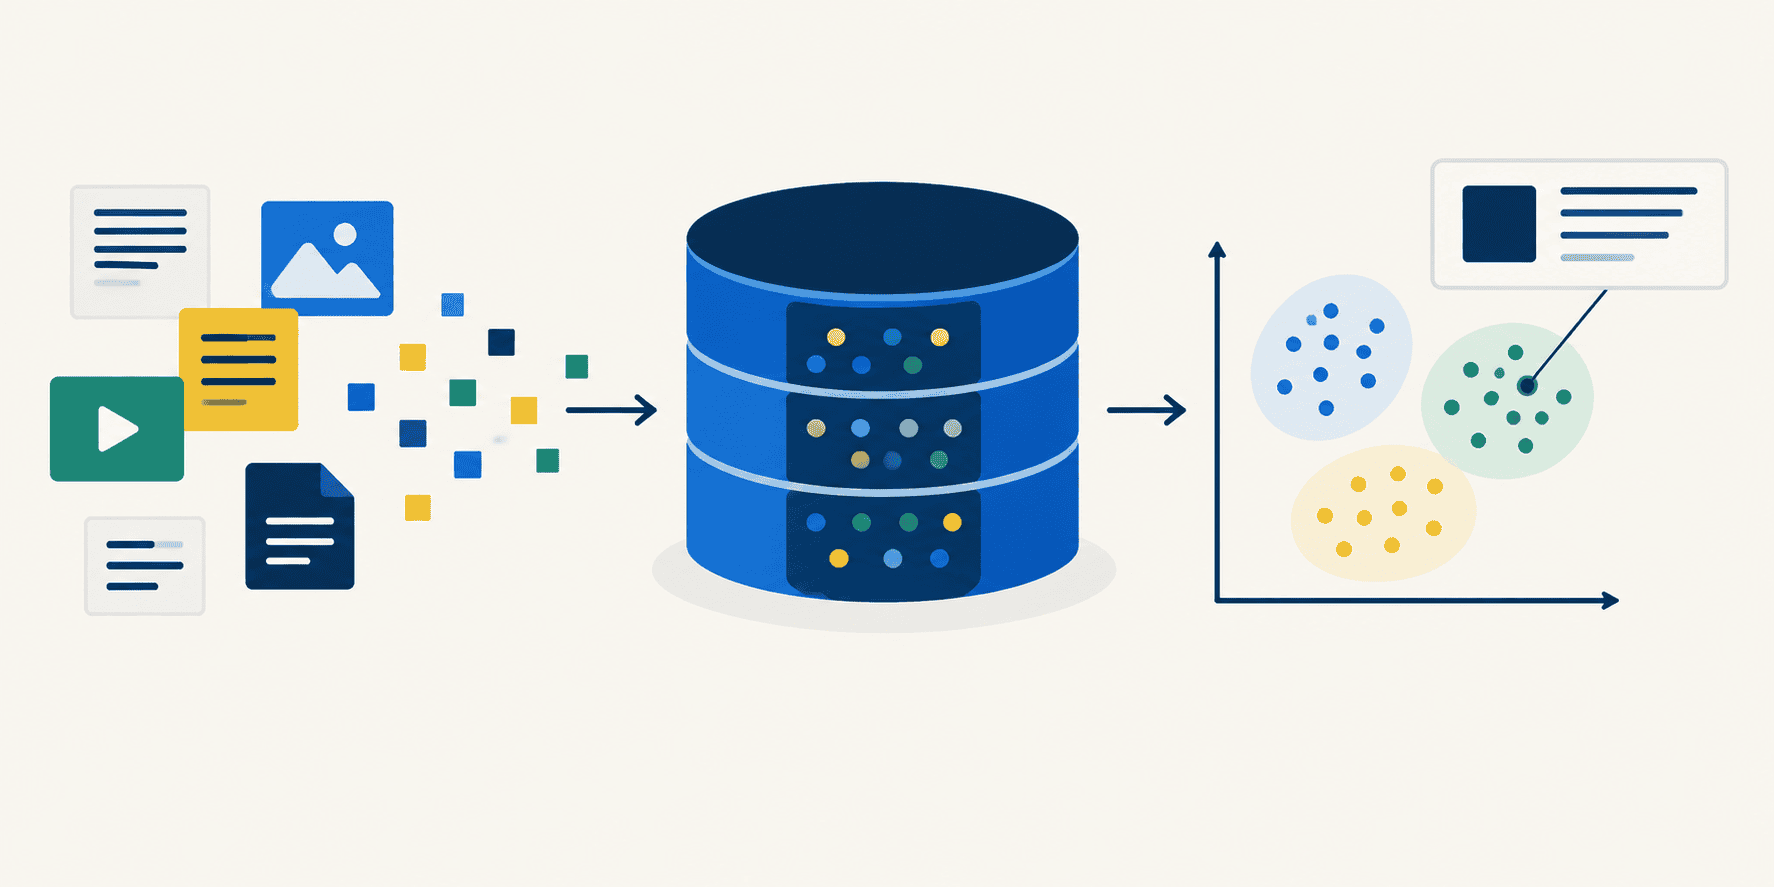
This article contrasts retrieval-augmented generation (RAG) with fine‑tuning as domain adaptation strategies, outlining the mechanical differences and guiding engineers on when each approach is appropriate. It explains that RAG leverages external knowledge sources at inference time, while fine‑tuning embeds domain…

Break Your Own RAG Pipeline Before Users Do
Towards Data Science· Sep 22, 2026
Break Your Own RAG Pipeline Before Users Do

The article presents a compact adversarial test set designed specifically for Retrieval‑Augmented Generation (RAG) pipelines, demonstrating that standard evaluation sets often miss critical retrieval failures. By injecting targeted adversarial queries, the test set exposes weaknesses in the retrieval component that…

Build And Understand a Vector Database From Scratch in 10 Easy Steps
Machine Learning Mastery· Sep 18, 2026
Build And Understand a Vector Database From Scratch in 10 Easy Steps

The article walks readers through 10 incremental steps to build a vector database from scratch in Python, covering data ingestion, indexing, query processing, and persistence. It demonstrates how to implement a simple vector similarity search engine using basic Python data structures, offering a clear, hands‑on…

Selecting a vector store for Amazon Bedrock Knowledge Bases
AWS ML Blog· 25 min read· Sep 17, 2026
Selecting a vector store for Amazon Bedrock Knowledge Bases
The article evaluates three vector store options for Amazon Bedrock Knowledge Bases—Amazon OpenSearch Service, Amazon Aurora PostgreSQL with the pgvector extension, and Amazon S3 Vectors—across three distinct Retrieval‑Augmented Generation (RAG) use cases, presenting benchmark results that highlight trade‑offs in…

Tables in PDFs for RAG: Don’t Flatten the Grid
Towards Data Science· Sep 3, 2026
Tables in PDFs for RAG: Don’t Flatten the Grid

The article advises against flattening grid structures when extracting tables from PDFs for Retrieval‑Augmented Generation (RAG), emphasizing that preserving the original table layout yields better downstream performance. It outlines a diagnostic approach and five composable operations to handle PDF tables without…

Modernizing and scaling support operations with generative AI on AWS
AWS ML Blog· 22 min read· Sep 2, 2026
Modernizing and scaling support operations with generative AI on AWS
This article outlines a generative AI solution on AWS that automates SOP creation from training videos, leverages Retrieval‑Augmented Generation (RAG) to assist ticket resolution, and employs machine‑learning models to predict SLA risk and balance workload distribution. It also describes agentic workflows that…

A RAG That Says “Not in This Document” Has to Show Four Kinds of Evidence
Towards Data Science· Sep 2, 2026
A RAG That Says “Not in This Document” Has to Show Four Kinds of Evidence
The article argues that a retrieval‑augmented generation (RAG) system that replies “Not in this document” must provide four distinct types of evidence to justify the answer, rather than offering an unsubstantiated “no answer.” It emphasizes that a confident but wrong answer is a bug, and a bare “no answer” without…

Closing an Azure OpenAI assistant's retrieval gap didn't take a new identity platform. It took one filter and a narrower assistant.
VentureBeat AI· 9 min read· Sep 1, 2026
Closing an Azure OpenAI assistant's retrieval gap didn't take a new identity platform. It took one filter and a narrower assistant.

An Azure OpenAI email assistant that auto‑resolved ~60% of inbound messages leaked privileged SharePoint content because its retrieval pipeline lacked document‑level ACL enforcement. Azure AI Search added native Entra‑based ACL trimming in a May 2025 preview and SharePoint ACL sync in a 2026‑05‑01‑preview API (spg:…

Build observable enterprise agentic retrieval using Managed Amazon Bedrock Knowledge Base with AWS CloudFormation
AWS ML Blog· 15 min read· Aug 31, 2026
Build observable enterprise agentic retrieval using Managed Amazon Bedrock Knowledge Base with AWS CloudFormation

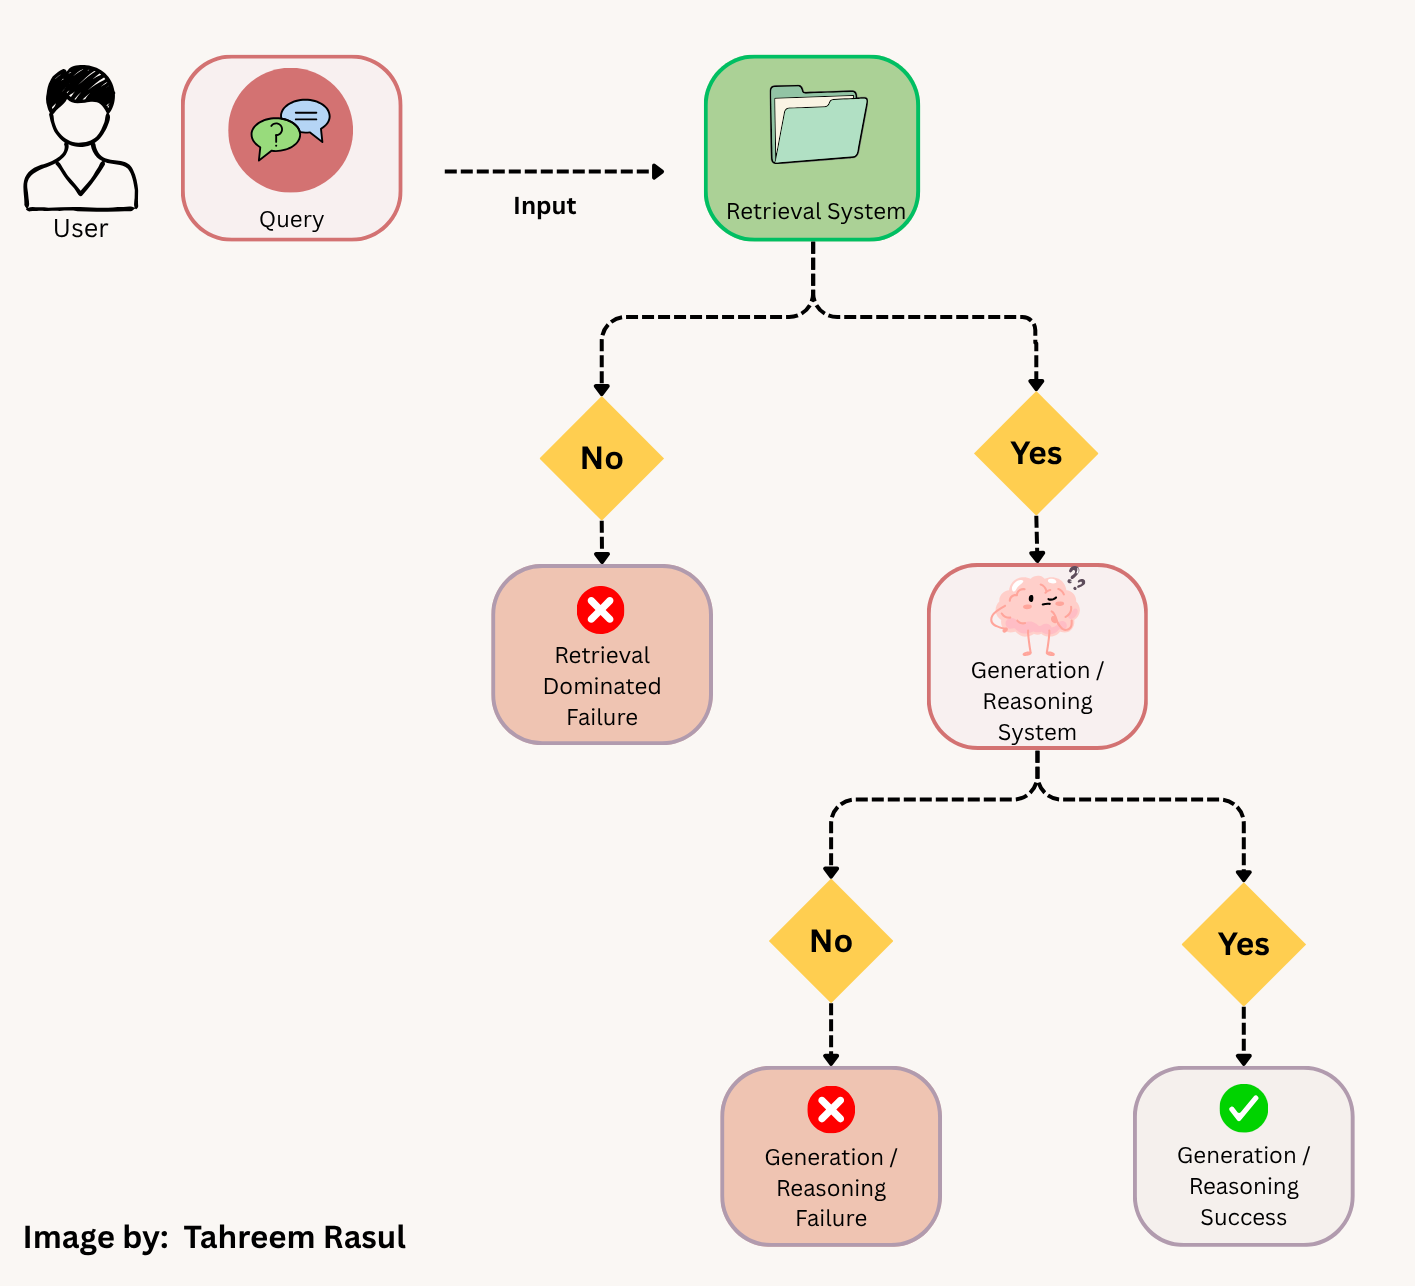
This article demonstrates how to build an enterprise‑grade, agentic retrieval system that routes queries across multiple Amazon Bedrock Managed Knowledge Bases, using Amazon Bedrock AgentCore and the Model Context Protocol (MCP) for tool orchestration. The runtime automatically instruments every…

FAQ as RAG: When You Get to Design the Corpus
Towards Data Science· Aug 31, 2026
FAQ as RAG: When You Get to Design the Corpus

The article explains how an FAQ can be leveraged as a Retrieval-Augmented Generation (RAG) corpus, effectively inverting the conventional RAG pipeline. It highlights that parsing FAQ content is straightforward, that the retrieval step can double as a cache, and that what would normally be a few‑shot prompt is instead…

Why RAG Complexity Should Be Earned
Towards Data Science· Aug 31, 2026
Why RAG Complexity Should Be Earned

The article presents a staged RAG pipeline framework that escalates system complexity only when specific failure modes surface. It begins with a simple lexical retrieval layer, then adds a hybrid search component, followed by a reranking stage, and ultimately incorporates agentic information‑seeking to resolve…

Noisy Text in RAG: Typos, OCR, and the Gap Classical Spell-Check Leaves
Towards Data Science· Aug 30, 2026
Noisy Text in RAG: Typos, OCR, and the Gap Classical Spell-Check Leaves

The article identifies three primary sources of noisy text that degrade Retrieval‑Augmented Generation (RAG) performance—user typos, fast‑typing transcription errors, and OCR character mistakes. Classical spell‑check only mitigates the typo issue, leaving transcription and OCR noise to be handled by downstream…

How Does a RAG Reranker Really Work?
Towards Data Science· Aug 26, 2026
How Does a RAG Reranker Really Work?

The article explains how a retrieval‑augmented generation (RAG) reranker operates under the hood and argues that understanding its true behavior can reshape architecture decisions in enterprise RAG deployments. It highlights that data scientists often describe rerankers differently from their actual implementation,…

Democratizing institutional knowledge: Building an AI-powered knowledge management system with AWS
AWS ML Blog· 18 min read· Aug 24, 2026
Democratizing institutional knowledge: Building an AI-powered knowledge management system with AWS

The accelerator delivers a fully customizable, voice‑first knowledge management system that captures tribal knowledge and serves it via retrieval‑augmented generation (RAG) powered by Amazon Bedrock Knowledge Bases. It incorporates a smart‑caching layer to reduce latency and can be deployed in under an hour using AWS…

Parse the Folder, Not Just the PDFs: The Relational Tables RAG Needs on a Case File
Towards Data Science· Aug 23, 2026
Parse the Folder, Not Just the PDFs: The Relational Tables RAG Needs on a Case File
The article argues that effective case file processing requires parsing entire folder structures and extracting relational tables rather than focusing solely on individual PDFs, emphasizing that the most valuable RAG queries are not simple retrieval questions. It highlights the need for an index that reflects case…

Multi-Document RAG: A Folder of Unrelated PDFs Is One Long Document with a Nested Outline
Towards Data Science· Aug 22, 2026
Multi-Document RAG: A Folder of Unrelated PDFs Is One Long Document with a Nested Outline

The authors propose treating a folder of unrelated PDFs as a single long document with a nested outline for Retrieval-Augmented Generation. They generate one summary line per file and preserve each file’s own table of contents, creating retrieval routes that descend two levels into the document hierarchy. Because the…

Reduce RAG costs on Amazon Bedrock with query-aware compression
AWS ML Blog· 15 min read· Aug 21, 2026
Reduce RAG costs on Amazon Bedrock with query-aware compression

This article presents a query‑aware compression pattern for Retrieval‑Augmented Generation on Amazon Bedrock that filters retrieved chunks with a low‑cost model (Anthropic Claude Haiku) before passing only the relevant spans to a higher‑capacity model (Anthropic Claude Sonnet). By inserting this post‑retrieval step in…

Retrieve One Row from a Table, Not the Whole Table: Row-Level Chunks for RAG
Towards Data Science· Aug 21, 2026
Retrieve One Row from a Table, Not the Whole Table: Row-Level Chunks for RAG

The article introduces a row‑level chunking strategy for Retrieval‑Augmented Generation (RAG) that treats each table body row, together with its column headers, as an independent chunk. By indexing these fine‑grained units, retrieval systems can return the exact row a user queries, reducing the amount of data returned…

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING