Home›LLM

LLM

Large Language Models (LLMs) are the foundation of modern AI applications. Coverage includes model releases, fine-tuning techniques, inference optimization, and production deployment patterns.

307 articles

LLM deep dives from the blog

All posts →
LLMs

Fine-Tuning vs RAG vs Prompting: A Practical Decision Tree for Engineers

8 min read · Read →
AI Engineering

How to Cut LLM API Costs by 70%+ Using Prompt Caching and Model Routing

7 min read · Read →
AI Engineering

Context Engineering for AI Agents: The Production Guide

14 min read · Read →
60 articles
Introducing the Amazon SageMaker JumpStart Model Leaderboard
AWS ML Blog· 11 min read· Today
Introducing the Amazon SageMaker JumpStart Model Leaderboard

Amazon SageMaker JumpStart now includes a Model Leaderboard that ranks 70+ open‑weight LLMs across three public reasoning benchmarks (BIG‑Bench Hard, GPQA Diamond, MMLU‑Pro) and reports standardized performance and cost metrics measured on SageMaker endpoints. The leaderboard presents quality scores, latency, and…

How Airbnb uses cost per task to operate coding agents on Amazon Bedrock
AWS ML Blog· 17 min read· Today
How Airbnb uses cost per task to operate coding agents on Amazon Bedrock
Airbnb evaluates and monitors coding agents on Amazon Bedrock by measuring “cost per task,” the list‑price cost of all tokens needed to complete a single coding request, alongside latency, throttling, and token‑usage metrics from CloudWatch. By running side‑by‑side evals on internal task sets before rollouts and then…

Design responsible AI controls for Amazon Aurora PostgreSQL
AWS ML Blog· 20 min read· Today
Design responsible AI controls for Amazon Aurora PostgreSQL

This article shows how to implement the Explainability dimension of AWS Responsible AI for a Retrieval‑Augmented Generation (RAG) customer‑support chatbot built on Amazon Aurora PostgreSQL‑Compatible Edition. By using Aurora ML to call Amazon Bedrock models and generate pgvector embeddings directly in SQL, the design…

Introducing Gemini 4 Neon
Google DeepMind· 9 min read· Today
Introducing Gemini 4 Neon

Gemini 4 Neon is a new Google DeepMind model that delivers frontier‑level intelligence for complex software engineering, knowledge work, and scientific workflows, featuring a 1 million‑token context window and pricing of $3 / M input tokens (95 % discount for cached) and $15 / M output tokens. It ranks #2 on the Vals…

DaisyRose-27B: Pushing the Frontier of Post-Training Efficiency
Hugging Face Blog· 5 min read· Today
DaisyRose-27B: Pushing the Frontier of Post-Training Efficiency

DaisyRose-27B, built on Qwen3.8-27B and fine‑tuned with the Miles RL framework, doubles Terminal‑Bench 4.1 pass@1 from 5.6 % to 12.0 % after 18 days of training on 144 H200 GPUs using only 1,200 curated long‑horizon tasks. The model retains a 256K‑token context window, image understanding, and the original…

How Social Department built culture-aware video discovery
AWS ML Blog· 20 min read· Today
How Social Department built culture-aware video discovery

Social Department built QuickSearch, a set of single‑action retrieval pipelines (Shareable Scenes, Quotable Quotes, Memeable Moments, Trend Align) that let marketers find culturally resonant video clips without typing detailed queries. The pipelines run on Amazon Bedrock using TwelveLabs Marengo 3.0 and Pegasus 1.2…

How Stretto built an AI voice agent with Amazon Nova 2 Sonic
AWS ML Blog· 14 min read· Today
How Stretto built an AI voice agent with Amazon Nova 2 Sonic

Stretto created “Tara,” an AI voice agent that replaces web‑form bankruptcy intake with a phone‑based, speech‑to‑speech interview powered by Amazon Nova 2 Sonic, a foundation model available through Amazon Bedrock. By using a single model for both speech recognition and generation, the system reduces latency and…

How AUMOVIO centralized AI access with Databricks Unity Gateway
Databricks Blog· 6 min read· Today
How AUMOVIO centralized AI access with Databricks Unity Gateway
AUMOVIO implemented a centralized AI access layer using Databricks Unity Gateway to streamline and secure interactions with large language models across its teams. The solution consolidates disparate model access patterns into a single entry point, reducing integration overhead and improving governance. Engineers can…

NVIDIA RTX Spark Compact Desktops Out Now
NVIDIA Blog· 7 min read· Today
NVIDIA RTX Spark Compact Desktops Out Now

NVIDIA’s RTX Spark compact desktops, now shipping from ASUS, Dell and MSI, pack a 20‑core NVIDIA Grace CPU, a Blackwell RTX GPU with 6,144 CUDA cores and up to 128 GB of unified memory, delivering up to 1 PFLOP of AI performance and enabling on‑device execution of 120‑billion‑parameter LLMs, real‑time 90 GB+ 3D…

At Ignite 2026, Microsoft reinvents Copilot as the autonomous engine of enterprise work
SiliconANGLE AI· Yesterday
At Ignite 2026, Microsoft reinvents Copilot as the autonomous engine of enterprise work

Microsoft announced at Ignite 2026 that Copilot will transition from a generative AI assistant to an autonomous engine that orchestrates enterprise workflows across emails, spreadsheets, messaging, meetings, and productivity apps. The shift emphasizes end‑to‑end task automation rather than point‑in‑time suggestions.…

Helping AI text detectors keep up with changing conditions
MIT News AI· 5 min read· Yesterday
Helping AI text detectors keep up with changing conditions

Researchers from MIT and Cornell introduced test‑time adaptation for AI‑generated text detectors, boosting detection accuracy from about 27 % to 93 % on disguised AI output. The technique lets a deployed detector continuously adjust its internal parameters using new, unlabeled data, mitigating distribution shift…

Reducing token costs and latency in Amazon Bedrock AgentCore JSON workloads
AWS ML Blog· 14 min read· Yesterday
Reducing token costs and latency in Amazon Bedrock AgentCore JSON workloads
The team reduced token consumption by up to 71 % and cut average latency by up to 80 % when processing 20 MB+ JSON payloads in an Amazon Bedrock AgentCore production agent. By applying three composable strategies—state‑based payload partitioning, selective context injection, and caching of tool results—they kept the…

OpenAI rolls out GPT-6.2 Astra for professional work and GPT-6.2 Sol for everyday work
SiliconANGLE AI· Yesterday
OpenAI rolls out GPT-6.2 Astra for professional work and GPT-6.2 Sol for everyday work

OpenAI announced GPT‑6.2 Astra, a new model for complex professional tasks that “outperforms its predecessor at less than a third of the cost,” alongside GPT‑6.2 Sol, an updated everyday‑work model. Both models are positioned for businesses and developers, extending OpenAI’s tiered offering for varied workloads.…

Amazon SageMaker AI real-time endpoints now support KV cache aware routing
AWS ML Blog· 22 min read· Yesterday
Amazon SageMaker AI real-time endpoints now support KV cache aware routing

Amazon SageMaker AI adds KV‑cache‑aware routing (KV_AWARE) for real‑time endpoints, allowing the router to direct each request to an instance that already holds the matching KV cache and isn’t overloaded. The model container reports cache events via the SM_VLLM_KV_EVENTS_CONFIG environment variable, and the endpoint’s…

Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart
AWS ML Blog· 19 min read· Yesterday
Reason over time-series data with OpenTSLM on Amazon SageMaker JumpStart

OpenTSLM, an open‑source family of time‑series language models (TSLMs) from Aionic Labs, is now available through Amazon SageMaker JumpStart, enabling engineers to deploy models that combine numerical measurements with textual context for proactive IT assistance. The models ingest device telemetry (e.g., CPU, memory,…

How ArisGlobal scaled generative AI inference on Amazon Bedrock
AWS ML Blog· 11 min read· Yesterday
How ArisGlobal scaled generative AI inference on Amazon Bedrock
ArisGlobal scaled its Nava X generative‑AI inference on Amazon Bedrock by reversing its prompt‑caching strategy—caching the shared prompt prefix instead of the source document—cutting effective input costs despite a 150% growth in shared prompt size and a >200% rise in per‑case inference spend. The system runs…

Alibaba launches Qwen4-Max with training, attention optimizations
SiliconANGLE AI· 2 days ago
Alibaba launches Qwen4-Max with training, attention optimizations

Alibaba unveiled Qwen4‑Max, the latest large language model in the Qwen series, claiming higher‑quality generation and lower inference cost than its predecessor. The improvements stem from a new Qwen4 architecture that makes training more efficient and includes attention optimizations. Engineers can expect a more…

How MoEngage built agentic customer engagement on Amazon Bedrock AgentCore
AWS ML Blog· 12 min read· 2 days ago
How MoEngage built agentic customer engagement on Amazon Bedrock AgentCore

MoEngage built Merlin AI, an agentic customer‑engagement platform on Amazon Bedrock AgentCore that lets marketers draft, analyze and adjust campaigns via a single conversational interface. The system uses Anthropic Claude Sonnet 4.6, 5 and 5.5 models for reasoning, tool‑call planning and content generation, and…

After 10 Heads in a Row, Small LLMs Bet Up to 82% on an 11th
Towards Data Science· 2 days ago
After 10 Heads in a Row, Small LLMs Bet Up to 82% on an 11th

Small language models exhibit a strong streak bias, betting up to 82% on an 11th coin flip after observing ten consecutive heads, even when explicitly told the coin is fair and flips are independent. This reveals that simple prompting only trims the bias by a few points, indicating persistent probabilistic…

NVIDIA Sweeps MLPerf Training and Endpoints as Vera Rubin Debuts With Leading Performance
NVIDIA Blog· 5 min read· 2 days ago
NVIDIA Sweeps MLPerf Training and Endpoints as Vera Rubin Debuts With Leading Performance

NVIDIA’s Vera Rubin platform swept every MLPerf Training v6.1 benchmark and, in its first MLPerf Endpoints submission, achieved more than 10× generational throughput‑per‑watt gains for agentic inference. The NVL72 system delivered up to 2× higher performance per GPU than the prior GB300 NVL72 and scaled DeepSeek‑V3…

Customize answers per tenant in Amazon Bedrock Managed Knowledge Base
AWS ML Blog· 22 min read· 2 days ago
Customize answers per tenant in Amazon Bedrock Managed Knowledge Base

Amazon Bedrock Managed Knowledge Base now supports tenant‑specific retrieval instructions, letting you define persona, answerFormat, retrievalGuidance, and answerPolicy per tenant and have those settings applied automatically to every request. The feature works across up to five knowledge bases in a single call and…

Use prompt caching with open-weight models on Amazon Bedrock
AWS ML Blog· 16 min read· 2 days ago
Use prompt caching with open-weight models on Amazon Bedrock

Amazon Bedrock now lets you reuse long prompt prefixes with open‑weight models via implicit and explicit prompt‑caching modes, cutting input‑token costs and latency. Implicit caching automatically reuses any stable prefix, while explicit caching requires you to mark reusable sections with `prompt_cache_options` set to…

Local LLMs Handle Textbook RAG but Fail on New Research Papers
Towards Data Science· 2 days ago
Local LLMs Handle Textbook RAG but Fail on New Research Papers

Local large language models achieve strong Retrieval‑Augmented Generation (RAG) results on textbook material, scoring between 12 and 20 out of 20, but their performance collapses on recently published research papers, dropping to 0‑9 out of 15. The evaluation used five different setups and a blind grading pack to…

Serving Scikit-LLM Pipelines as REST APIs with FastAPI
Machine Learning Mastery· 2 days ago
Serving Scikit-LLM Pipelines as REST APIs with FastAPI

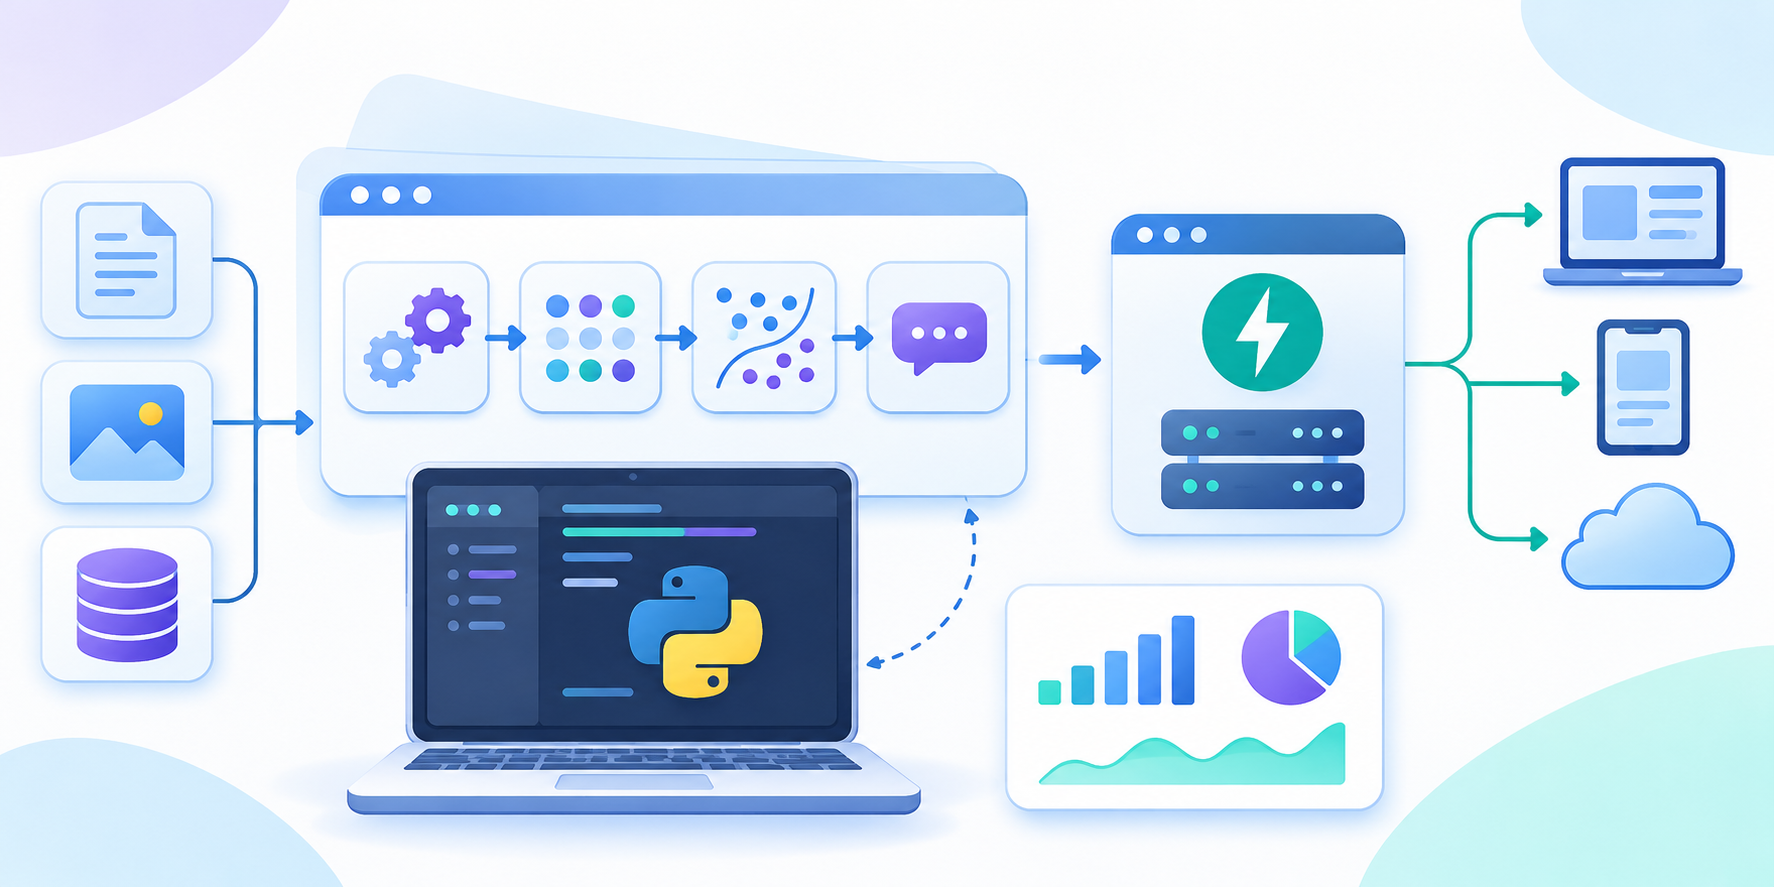
This article demonstrates how to expose a Scikit‑LLM zero‑shot text classification pipeline, backed by a locally hosted Ollama model, as a RESTful service using FastAPI. It walks through wiring the Scikit‑LLM pipeline into a FastAPI endpoint, enabling HTTP‑based inference without external hosting. Engineers can thus…

AI Day Seoul Brings Together Korea’s Industry Leaders, Startups and Developer Communities
NVIDIA Blog· 4 min read· 3 days ago
AI Day Seoul Brings Together Korea’s Industry Leaders, Startups and Developer Communities

NVIDIA’s AI Day Seoul showcased Korean industry leaders and startups leveraging NVIDIA platforms to build physical AI and agentic systems, highlighted by Deepu Talla’s remarks on the country’s rapid robotics adoption. The event featured hands‑on workshops on deploying and optimizing AI inference at scale with the…

Hugging Face and OpenRouter join forces to make open-weight models easy to run
Hugging Face Blog· 5 min read· 3 days ago
Hugging Face and OpenRouter join forces to make open-weight models easy to run
Hugging Face and OpenRouter have integrated to let developers call any open‑weight model on the Hugging Face Hub through a single API that automatically routes each request to the optimal provider among 80+ based on live price, speed, and reliability. OpenRouter’s new routing logic reduces capacity errors by 46 % and…

Understanding Positional Embeddings in Modern LLMs
Ahead of AI· 46 min read· 3 days ago
Understanding Positional Embeddings in Modern LLMs

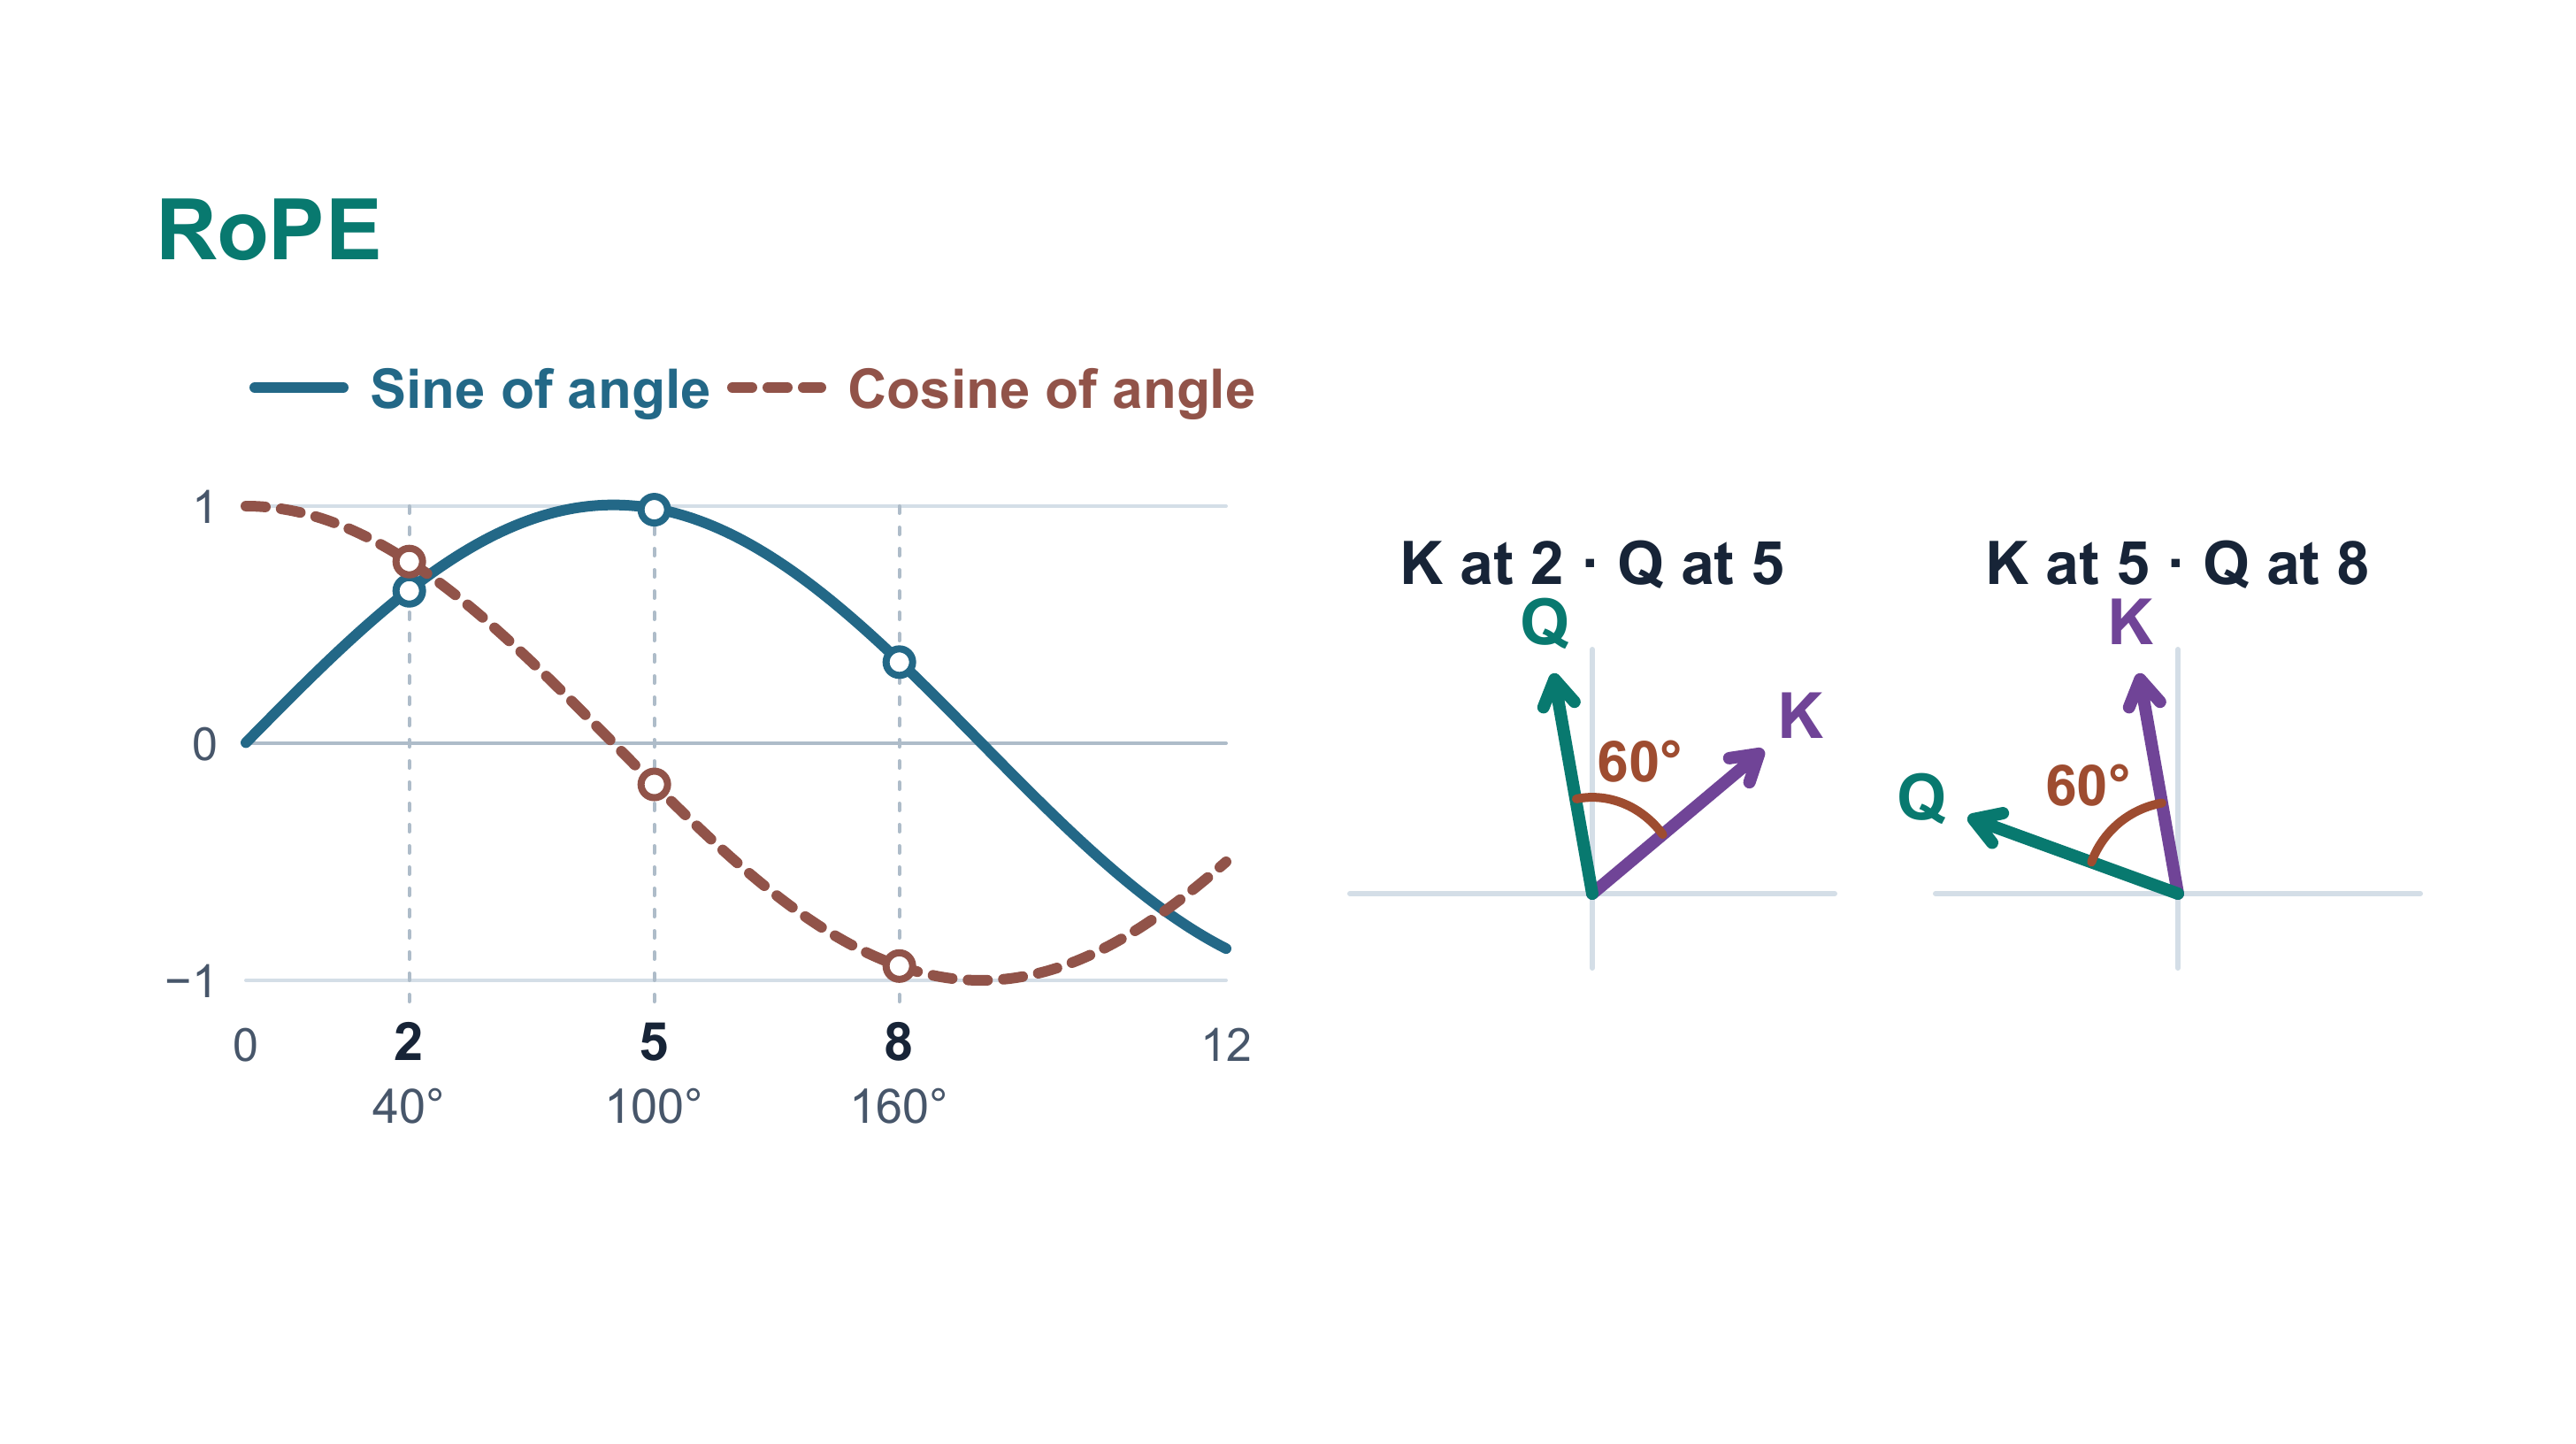
This article provides a deep dive into how modern large language models encode token position information, covering classic absolute embeddings, relative methods such as Rotary Positional Embedding (RoPE), and the ways recent 2026 open‑weight models adopt or drop explicit positional encodings. It includes visual…

Production MLOps at GS Caltex with Amazon SageMaker Canvas, part 1
AWS ML Blog· 16 min read· 5 days ago
Production MLOps at GS Caltex with Amazon SageMaker Canvas, part 1

GS Caltex accelerated its MLOps by linking Amazon SageMaker Canvas‑built models to SageMaker Pipelines, cutting deployment time from about a week to a few hours. Engineers use Canvas for visual data prep (Data Wrangler) and model training, then register the model in the SageMaker Model Registry. ML engineers convert…

Route coding agent requests to the right model on Amazon Bedrock with NVIDIA NeMo Switchyard
AWS ML Blog· 22 min read· 5 days ago
Route coding agent requests to the right model on Amazon Bedrock with NVIDIA NeMo Switchyard
This article demonstrates how to route coding‑agent requests on Amazon Bedrock using NVIDIA NeMo Switchyard integrated with LiteLLM. By deploying LiteLLM v1.102.0 and the Switchyard server 0.3.0 container via AWS CDK, you can apply stage‑routing (based on recent tool activity) or random‑routing (with optional weights)…

Mirendil raises $1B in funding to speed up AI model development
SiliconANGLE AI· 5 days ago
Mirendil raises $1B in funding to speed up AI model development

Mirendil Inc. announced a $1 billion early‑stage Series A round to accelerate its AI model development platform, with Kleiner Perkins and Clearlake Capital leading the investment and participation from Google LLC among others. The funding signals strong investor confidence in tooling that can shorten the AI…

Advancing science & engineering with Antigravity’s /teamwork
Google Research· 16 min read· 5 days ago
Advancing science & engineering with Antigravity’s /teamwork

Antigravity’s /teamwork framework leverages Gemini 4 Argon, Carbon, and Hydrogen models in parallel multi‑agent workflows that pair exploratory solvers with dedicated falsifiers such as the Lean 4 proof checker and unmodified software test suites. By partitioning context per specialized agent and routing prompts…

Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture
AWS ML Blog· 30 min read· 5 days ago
Build a model improvement flywheel with Amazon SageMaker HyperPod Data Capture

Amazon SageMaker HyperPod now includes a built‑in Data Capture feature that records live inference inputs and outputs to Amazon S3 across three independent tiers with minimal latency and no impact on model availability. The post demonstrates a full flywheel on a single HyperPod cluster: capture production traffic,…

XYBench: Helping with the problem behind the question
Hugging Face Blog· 6 min read· 5 days ago
XYBench: Helping with the problem behind the question

XYBench is a new benchmark of 8,115 real‑world questions that evaluates how well large language models detect and correct XY‑problem misconceptions, such as mistaking warm cupcakes for a frosting‑adhesion issue. Evaluations of Claude Sonnet 4.6, GPT‑5, Gemini 3.1 Pro, Qwen3.5‑9B, and DeepSeek‑V4 Pro show these models…

OpenAI and Databricks: Enterprise AI on your governed data
Databricks Blog· 6 min read· 5 days ago
OpenAI and Databricks: Enterprise AI on your governed data

OpenAI and Databricks are partnering to bring enterprise‑grade AI capabilities to organizations that need to operate on governed data. The announcement highlights a joint effort to integrate OpenAI models with Databricks’ data platform, enabling secure, compliant AI workloads. Engineers can expect tighter coupling…

llama.cpp v1.0.0 : A stronger foundation for the local AI ecosystem
Hugging Face Blog· 5 min read· 5 days ago
llama.cpp v1.0.0 : A stronger foundation for the local AI ecosystem

llama.cpp v1.0.0 launches a stable, version‑bumped API/ABI for the ggml inference engine, now supporting more than 150 architecture variants and a suite of hardware‑specific backends (NVIDIA, AMD, Qualcomm, Arm, IBM, Intel). The release emphasizes semantic‑versioning rules, CI scalability via Hugging Face Buckets and…

AI Is Helping Care Teams Get Patients the Right Care, Sooner
NVIDIA Blog· 10 min read· 5 days ago
AI Is Helping Care Teams Get Patients the Right Care, Sooner

Dyania Health’s Synapsis AI is a clinical reasoning engine that ingests decades‑long free‑text patient records to surface evidence‑based clinical signals, running entirely on NVIDIA‑accelerated compute within a hospital firewall. The system was used at Cleveland Clinic to process over 7,800 aortic valve replacement…

How to Check Local LLM Output with Ollama, Gemma 4, and Nimble
Towards Data Science· 5 days ago
How to Check Local LLM Output with Ollama, Gemma 4, and Nimble

The article outlines a pipeline that uses Ollama to run the Gemma 4 E2B model locally for draft generation, then employs Bespoke Labs' Nimble 9B to automatically accept, revise, or flag responses for human review, with only flagged queries receiving a focused retry. This approach combines local inference with a…

The Complete Guide to LLM Evaluation
Machine Learning Mastery· 5 days ago
The Complete Guide to LLM Evaluation

The article presents a systematic approach to evaluating large language model (LLM) applications, covering the selection of scoring metrics, the construction of reliable LLM judges, and methods for assessing retrieval‑augmented generation (RAG) systems. It outlines best‑practice design patterns for evaluation…

Google releases Gemini 4 Hydrogen, a lower-cost model said to outscore Argon
SiliconANGLE AI· 6 days ago
Google releases Gemini 4 Hydrogen, a lower-cost model said to outscore Argon

Google announced Gemini 4 Hydrogen, a lower‑cost member of the Gemini 4 family that reportedly outperforms its higher‑tier sibling Gemini 4 Argon on the Artificial Analysis Intelligence Index, scoring 51 versus 50 at the default high‑thinking level. This modest edge suggests engineers can achieve comparable or better…

LLMON: An LLM-Native Markup Language, now in Granite 4.1 3B and 8B
Hugging Face Blog· 9 min read· 6 days ago
LLMON: An LLM-Native Markup Language, now in Granite 4.1 3B and 8B
The announcement introduces LLMON, an LLM‑native markup language that uses reserved special‑token delimiters to make context structure explicit, and ships two experimental preview models—granite-4.1-3b-LLMON-preview and granite-4.1-8b-LLMON-preview—trained to consume and generate LLMON‑marked text. Benchmarks show…

The Pulse: Details of incident.io’s AI spend
Pragmatic Engineer· 9 min read· 6 days ago
The Pulse: Details of incident.io’s AI spend

incident.io reports that AI agents now generate code for nearly 80% of production pull requests, driving a 6× rise in “effort points” and a 60% drop in incidents per 1,000 PRs. The company’s AI spend has climbed to roughly $1.6 M this year (~$2,700 per engineer per month), while release velocity rose 47% to 2.8…

Building a self-service LLM gateway with Amazon Bedrock and LiteLLM
AWS ML Blog· 18 min read· 6 days ago
Building a self-service LLM gateway with Amazon Bedrock and LiteLLM

This article details how to construct a self‑service LLM gateway that fronts Amazon Bedrock models (e.g., Claude Sonnet and Claude Haiku) with LiteLLM running on AWS Fargate, exposing an OpenAI‑compatible API. The pattern leverages Amazon Route 53, CloudFront, an ALB, and per‑user API keys stored in Amazon RDS…

Introducing Gemini 4 Hydrogen
Google DeepMind· 9 min read· 6 days ago
Introducing Gemini 4 Hydrogen

Gemini 4 Hydrogen is a new 1 M‑token context LLM priced at $1.50 / M input and $7.50 / M output tokens, achieving an Artificial Analysis Intelligence Index score of 51 (up to 54 at xhigh) and delivering 2.5× faster execution than Gemini 3.8 Flash while tripling Terminal‑Bench 4.1 scores to 57%. The Orchestrator…

How H6.ai builds AI-powered financial automation with Lakebase Postgres
Databricks Blog· 6 min read· 6 days ago
How H6.ai builds AI-powered financial automation with Lakebase Postgres

H6.ai leverages Lakebase Postgres to power AI-driven accounts payable and invoice processing, reducing manual effort in financial workflows. By integrating AI models directly with a Postgres‑based data lake, the system can ingest, classify, and extract invoice data at scale. This architecture enables engineers to…

Fine-grained access control for Amazon Bedrock Managed Knowledge Base tools
AWS ML Blog· 24 min read· 6 days ago
Fine-grained access control for Amazon Bedrock Managed Knowledge Base tools

This article presents a pattern for enforcing fine‑grained access control in Amazon Bedrock agents by injecting verified user attributes into Model Context Protocol (MCP) tool calls via the AgentCore Gateway, then leveraging Managed Knowledge Base’s ACL‑aware search that filters results based on the userContext…

Getting Reliable Structured Outputs from LLMs: Validation, Retries and Constrained Decoding
Machine Learning Mastery· 6 days ago
Getting Reliable Structured Outputs from LLMs: Validation, Retries and Constrained Decoding
The article presents a fixture suite that converts example sentences into fourteen test cases to evaluate LLMs’ ability to produce reliable structured outputs, covering scenarios such as missing required keys, JSON wrapped in code fences, fabricated quotes, refusals, and exhaustion after three attempts. By…

Google enters decision model market with Gemini Decisions API
SiliconANGLE AI· Nov 12, 2026
Google enters decision model market with Gemini Decisions API

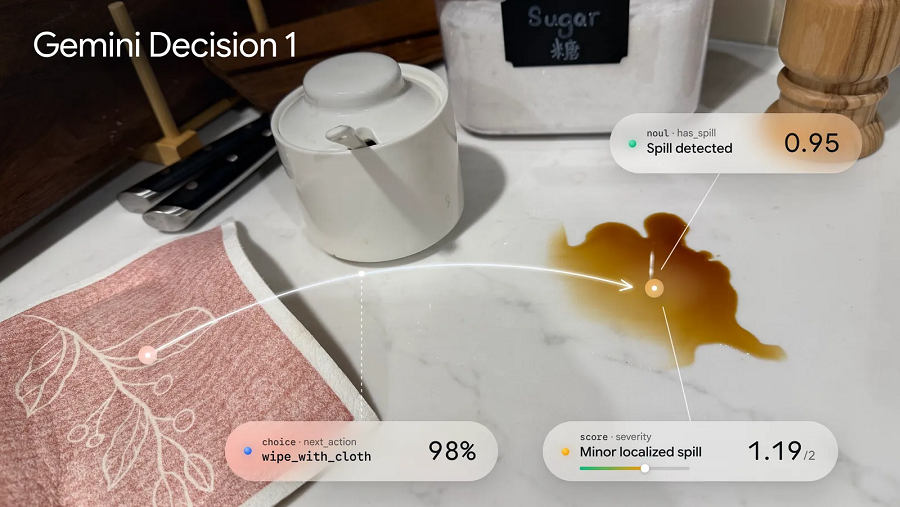
Google has unveiled the Gemini Decisions API, a new AI service built on the Gemini Decision 1 model that focuses on narrow, cost‑efficient decision‑making queries rather than general conversation. The API is positioned to provide faster, cheaper responses for specific user questions, trading breadth for efficiency.…

OpenAI Codex on Amazon Bedrock
AWS ML Blog· 14 min read· Nov 11, 2026
OpenAI Codex on Amazon Bedrock

OpenAI Codex can invoke Bedrock‑hosted OpenAI models such as GPT‑5.6 Sol from a developer workstation, and Amazon provides three rollout patterns—Native AWS Access, AgentCore Gateway, and LLM Gateway—to align inference with existing IAM, regional, and observability controls. The quick‑start repository supplies…

ICYMI: What landed for AI builders in October 2026
AWS ML Blog· 8 min read· Nov 11, 2026
ICYMI: What landed for AI builders in October 2026

AWS announced October 2026 updates that add new high‑throughput, low‑cost models to Amazon Bedrock and extend the AgentCore platform, letting builders match tasks to the optimal model, keep agents running when primary models are throttled, and gain finer cost predictability. Claude Haiku 5.5 offers up to 75 % lower…

How DXC Technology built a multi-model AI substrate on Amazon Bedrock
AWS ML Blog· 13 min read· Nov 11, 2026
How DXC Technology built a multi-model AI substrate on Amazon Bedrock

DXC Technology built a governed multi‑model AI substrate on Amazon Bedrock that unifies access to Anthropic Claude, Amazon Nova, Meta Llama and other open‑weight families via a single API, while enforcing Bedrock Guardrails for content filtering, PII redaction, and denied‑topic policies. System‑level controls such as…

Using wearables to enable cardiovascular-kidney-metabolic (CKM) risk profiling for personalized coaching
Google Research· 9 min read· Nov 11, 2026
Using wearables to enable cardiovascular-kidney-metabolic (CKM) risk profiling for personalized coaching

The paper presents an investigational machine learning framework that converts passive wearable data into a modifiable “coachable health age” and uses a sensor‑world model (SensorWM) trained on over 2.2 million person‑weeks to simulate personalized 12‑week “what‑if” habit trajectories, which are then turned into…

Bring your business context to ChatGPT, Claude, Microsoft Copilot Cowork and Grok Bot
Databricks Blog· 6 min read· Nov 11, 2026
Bring your business context to ChatGPT, Claude, Microsoft Copilot Cowork and Grok Bot

The article announces that businesses can now inject their own contextual data into leading large language models such as ChatGPT, Claude, Microsoft Copilot Cowork, and Grok Bot, enabling more tailored AI‑powered workflows. By linking proprietary data sources directly to these models, enterprises can improve relevance…

BotPsy: On-Device Personal Assistant with a Sub-Billion-Parameter Agentic Language Model
Hugging Face Blog· 15 min read· Nov 11, 2026
BotPsy: On-Device Personal Assistant with a Sub-Billion-Parameter Agentic Language Model

BotPsy is a 0.8 B‑parameter agentic language model built on Qwen3.5‑0.8B‑Think that doubles the base model’s tool‑use capability, achieving state‑of‑the‑art performance for sub‑billion models on six agentic benchmarks. It outperforms every model up to 1.2 B parameters and even beats its larger 2 B sibling on five of…

Introducing Kimi K3.1 Pro on Amazon Bedrock
AWS ML Blog· 9 min read· Nov 11, 2026
Introducing Kimi K3.1 Pro on Amazon Bedrock

Moonshot AI’s Kimi K3.1 Pro Highspeed, a post‑trained 3‑trillion‑parameter model with a 1‑million‑token context window, is now available on Amazon Bedrock and delivers 2–3× faster token generation than Kimi K3.1 Pro. It supports tool calling, structured output, configurable reasoning, image input, and streaming via…

Token Pooling-Aware Training for Multi-Vector Embedding Models
Hugging Face Blog· 11 min read· Nov 11, 2026
Token Pooling-Aware Training for Multi-Vector Embedding Models
Token pooling‑aware training lets multi‑vector embedding models keep higher retrieval quality while cutting document vector storage. Using a pool_factor = 4, a normally trained model keeps 94.6 % of its unpooled NanoBEIR nDCG@10, whereas pooling‑aware training raises retention to 97.8 % at the same 4× storage…

Financial institutions confront the complexities of scaling AI
SiliconANGLE AI· Nov 10, 2026
Financial institutions confront the complexities of scaling AI

AI adoption in financial services is transitioning from pilot projects to broader deployments across banks, capital markets firms, and mortgage lenders. The focus is now on responsibly scaling AI while satisfying stringent security, compliance, and customer‑trust requirements. This shift was highlighted at the AWS…

Gemini 4 Carbon is now available
Google DeepMind· 11 min read· Nov 10, 2026
Gemini 4 Carbon is now available

Gemini 4 Carbon, Google’s newest frontier LLM, delivers top‑tier performance on real‑world benchmarks while costing less than half of competing models. It ranks #1 on CursorBench 4.0, Perplexity’s WANDR, and Zapier’s AutomationBench with >2× lower cost per task, and #2 on the new Multimodal Knowledge Agent benchmark…

Mitra-v2: Scaling synthetic pretraining for tabular foundation models
Amazon Science· 5 min read· Nov 10, 2026
Mitra-v2: Scaling synthetic pretraining for tabular foundation models

Mitra‑v2 is the second‑generation tabular foundation model that scales synthetic pretraining to tables ten times larger in rows and three times wider in columns than its predecessor, while retaining the same Transformer architecture. On the TabArena benchmark of 51 real‑world datasets, Mitra‑v2 outperforms Mitra‑v1 on…

How to Validate LLM Output in a DuckDB and dbt Pipeline
Towards Data Science· Nov 10, 2026
How to Validate LLM Output in a DuckDB and dbt Pipeline

The article demonstrates how to validate the output of a Gemini Flash‑Lite LLM by extracting structured fields—skills, seniority, and Nigeria eligibility—from 18 RemoteOK job postings. It shows a pipeline that stores the raw LLM response in DuckDB, then runs Python‑based checks and a suite of dbt tests to ensure each…

Opening the datasets behind our AI weather models
Google DeepMind· 5 min read· Nov 10, 2026
Opening the datasets behind our AI weather models

The article announces the release of foundational precipitation and geostationary satellite datasets intended to support AI weather modeling. It highlights that these datasets enable clearer planetary observation for training and evaluating weather prediction models. Engineers can leverage the data to improve model…

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING