NVIDIA RTX Spark Compact Desktops Out Now
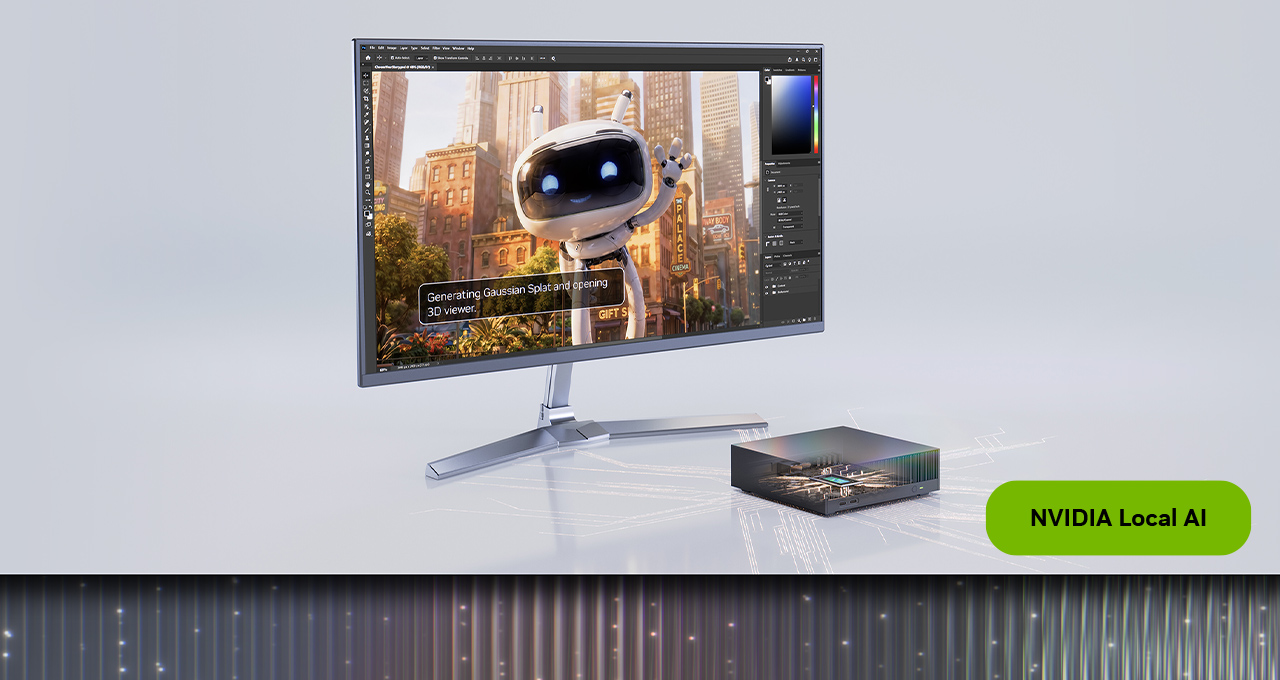
NVIDIA’s RTX Spark compact desktops, now shipping from ASUS, Dell and MSI, pack a 20‑core NVIDIA Grace CPU, a Blackwell RTX GPU with 6,144 CUDA cores and up to 128 GB of unified memory, delivering up to 1 PFLOP of AI performance and enabling on‑device execution of 120‑billion‑parameter LLMs, real‑time 90 GB+ 3D rendering, and 4:2:2 video editing. The machines integrate the full NVIDIA AI software stack—including Hermes Agent, NemoClaw blueprints, Unsloth fine‑tuning, and Switchyard routing—so developers can run local agents 24/7 while offloading heavy reasoning to the cloud. This hardware‑software bundle gives engineers a single Windows PC that eliminates per‑token API costs and supports continuous AI‑driven creative pipelines such as Photoshop‑to‑ComfyUI workflows.
⚡ Key Takeaways
- Up to 128 GB unified memory and 1 PFLOP AI performance (20‑core Grace CPU, Blackwell RTX GPU, 6,144 CUDA cores).
- Supports running 120‑billion‑parameter LLMs locally.
- Real‑time rendering of 90 GB+ 3D scenes and 4:2:2 video editing on‑device.
- Local AI agents can be built with Hermes Agent or NVIDIA NemoClaw blueprints; fine‑tuning via Unsloth.
- NVIDIA Switchyard (in Hermes) automatically routes tasks between local and cloud models to manage cost.
Engineers can now host massive models and always‑on agents on a single workstation, cutting cloud API fees and latency while keeping creative assets local, which accelerates end‑to‑end AI‑augmented production pipelines.
✅ Practical Steps
- Deploy a RTX Spark desktop and install the NVIDIA AI software stack (Hermes Agent, NemoClaw, Unsloth, Switchyard) as provided by NVIDIA.
- Use Hermes Agent or NemoClaw blueprints to configure and launch a 24/7 local AI agent on the machine.
- Fine‑tune a supported model locally with Unsloth, then enable Switchyard to route heavy inference calls to cloud models as needed.
Want the full story? Read the original article.
Read on NVIDIA Blog ↗