NVIDIA Unveils Minerva to Bring End-to-End Observability for AI Factories
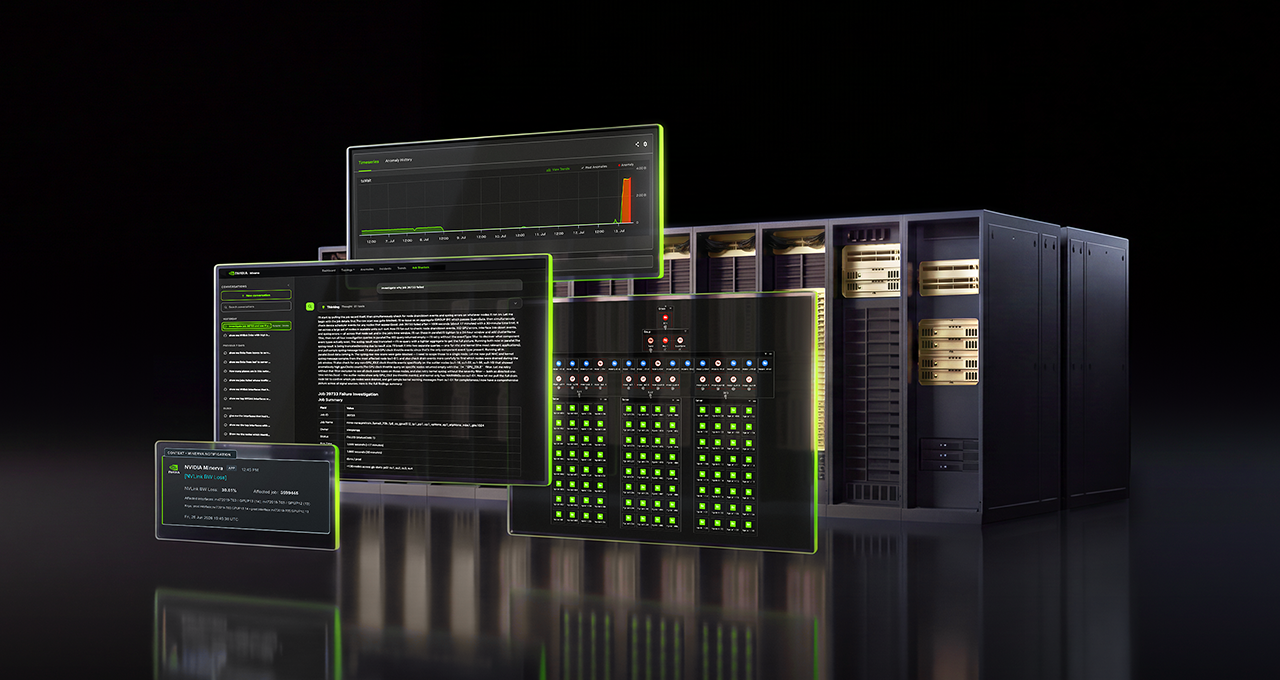
NVIDIA Minerva is an AIOps platform that aggregates telemetry from GPUs, networking, storage, schedulers, and workloads into a dynamic knowledge graph, applying supervised and unsupervised machine‑learning models to detect anomalies and predict failures across AI factories. It processes billions of data points per hour to surface actionable incidents and includes a native AI assistant for natural‑language interaction and integration with external automation APIs. The system aims to increase GPU uptime, reduce mean‑time‑to‑repair, and improve overall AI‑factory yield for large‑scale training and inference operations.
⚡ Key Takeaways
- Minerva analyzes billions of data points per hour using supervised and unsupervised machine learning.
- It builds a dynamic knowledge graph that maps GPUs, SuperNICs, switches, cables, and running jobs.
- The platform groups related alerts into single incidents, reducing alert noise and enabling proactive maintenance.
- Operators interact via a native AI assistant that can query live telemetry and suggest remediation steps.
- Integration is possible through infrastructure application programming interfaces (APIs) and external agentic AI tools.
By turning massive telemetry streams into concise, actionable insights, Minerva lets engineers keep thousands of GPUs productive, cutting downtime and operational overhead in large‑scale AI deployments.
✅ Practical Steps
- Deploy Minerva in your AI factory to ingest telemetry from GPUs, networking, storage, and schedulers.
- Use the native AI assistant to query cluster health and receive remediation recommendations in natural language.
- Connect Minerva’s automation hooks to your existing infrastructure APIs to enable programmatic remediation of detected issues.
Want the full story? Read the original article.
Read on NVIDIA Blog ↗