Leading European Financial Services Organizations Embrace Open Models to Build Proprietary Intelligence
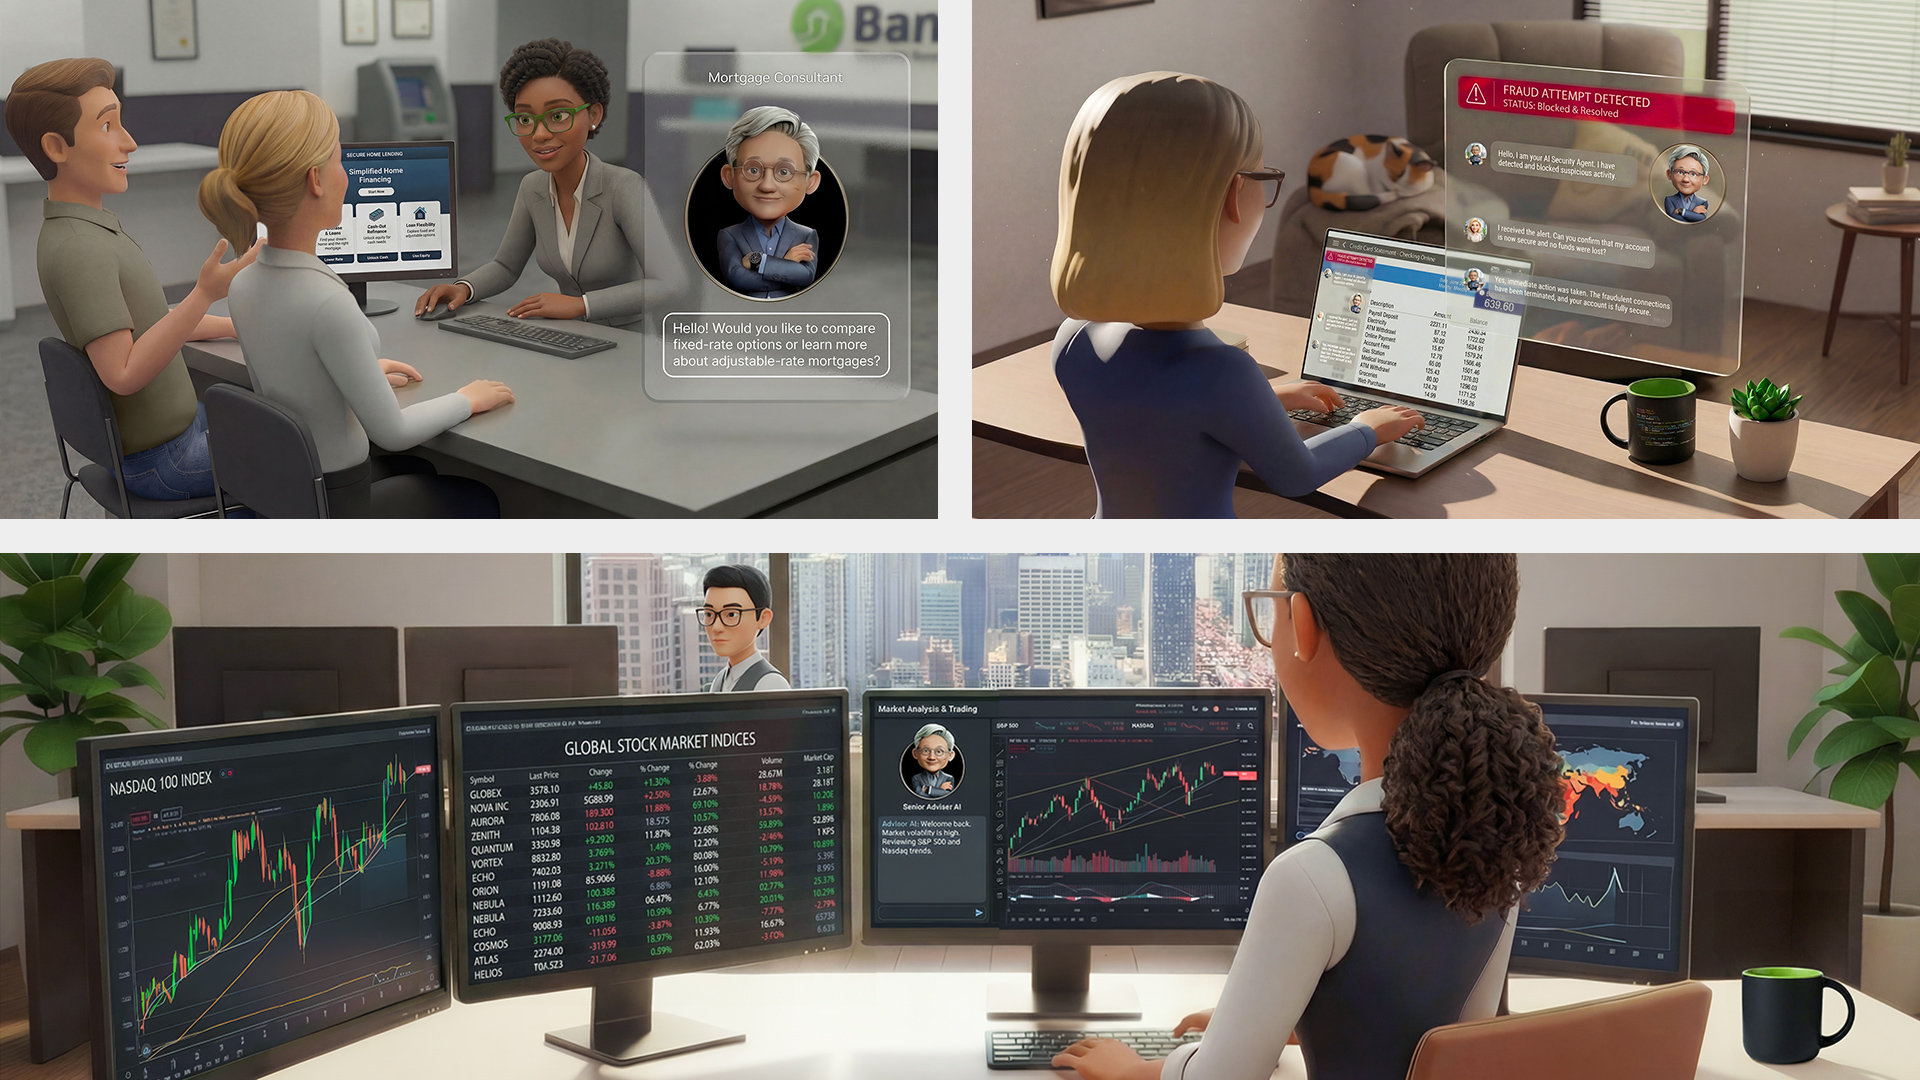
European financial firms are deploying open‑weight foundation models at production scale using NVIDIA‑accelerated hardware such as Blackwell Ultra and RTX PRO 6000 GPUs, with toolchains like cuDF, Dynamo‑Triton, and the Polars GPU engine. Revolut’s PRAGMA model serves 80 million customers and is engineered to scale three‑fold, while Lloyds’ ATUM and Santander’s Kumo models illustrate domain‑specific intelligence built on the same stack. These deployments demonstrate that open models can match closed‑model quality at roughly 60 % of the per‑answer cost, enabling cost‑controlled, proprietary AI across banking, payments, and market‑research workloads. Engineers can now leverage NVIDIA’s ecosystem to bring large‑scale, low‑latency generative AI in‑house without data leaving their premises.
⚡ Key Takeaways
- Revolut’s PRAGMA model runs on NVIDIA Blackwell Ultra GPUs, serving an initial 80 million customers and engineered for 3× scalability.
- The stack relies on NVIDIA cuDF and Dynamo‑Triton software for data processing and model serving.
- bunq’s Finn assistant achieves comparable quality to closed models at 60 % of the cost per answer when deployed on Nebius.
- Lloyds Banking Group’s ATUM model is accelerated with NVIDIA RTX PRO 6000 Blackwell GPUs to process billions of transactions.
- LSEG uses the Polars GPU engine, accelerated by cuDF on RTX PRO 6000 Blackwell GPUs, to analyze historical tick data up to 10× faster.
By adopting open‑weight models on NVIDIA’s accelerated platform, financial institutions can build proprietary, high‑throughput AI services in‑house at substantially lower cost, preserving data sovereignty while meeting the latency demands of real‑time banking and fraud detection.
✅ Practical Steps
- Deploy NVIDIA cuDF and Dynamo‑Triton on Blackwell Ultra or RTX PRO 6000 GPUs to serve open‑weight models such as PRAGMA or Nemotron‑3‑Ultra‑550B.
- Use the Polars GPU engine (accelerated by cuDF) for high‑speed analysis of large tick‑data sets, as demonstrated by LSEG.
- Integrate open‑weight models into existing banking pipelines (e.g., transaction processing, speech recognition) to replace closed‑model APIs and achieve up to 60 % cost reduction per inference.
Want the full story? Read the original article.
Read on NVIDIA Blog ↗