Home›Nvidia

Nvidia

61 curated articles on Nvidia for AI engineers

60 articles
Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference
AWS ML Blog· 11 min read· Yesterday
Managed NVIDIA Dynamo on Amazon SageMaker HyperPod Inference

Amazon SageMaker HyperPod Inference now integrates NVIDIA Dynamo, an open‑source distributed inference framework, to enable multi‑node, disaggregated prefill/decode serving for LLMs whose FP8 weights exceed the 640 GB GPU memory of a single ml.p5.48xlarge instance. Dynamo’s KV‑aware routing and support for engines…

How the World’s Most Advanced AI Infrastructure Supply Chain Invents the Future
NVIDIA Blog· 8 min read· 2 days ago
How the World’s Most Advanced AI Infrastructure Supply Chain Invents the Future
NVIDIA’s AI hardware pipeline is powered by a tightly‑woven global supply chain orchestrated by Deb Shoquist, who leverages decades‑long partnerships with manufacturers such as TSMC (since 1998) and SPIL/KYEC (over two decades). Shoquist maintains the ecosystem through quarterly supplier meetings and six weeks of…

Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics
NVIDIA Blog· 4 min read· 2 days ago
Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics

Lambda is deploying NVIDIA Photonics co‑packaged optics (CPO) switches to interconnect over 10,000 GPUs across NVIDIA GB300 NVL72 racks, achieving up to a 10% latency reduction at pod scale and up to 5× better power efficiency with 15× higher reliability versus conventional pluggable optics. Each switch provides 144 ×…

AI Is Helping Care Teams Get Patients the Right Care, Sooner
NVIDIA Blog· 10 min read· 5 days ago
AI Is Helping Care Teams Get Patients the Right Care, Sooner
Dyania Health’s Synapsis AI is a clinical reasoning engine that ingests decades‑long free‑text patient records to surface evidence‑based clinical signals, running entirely on NVIDIA‑accelerated compute within a hospital firewall. The system was used at Cleveland Clinic to process over 7,800 aortic valve replacement…

As AI agents take control, Nvidia rethinks the security playbook
SiliconANGLE AI· 6 days ago
As AI agents take control, Nvidia rethinks the security playbook

Nvidia introduced **Scale‑In**, a new pillar in its AI networking stack that provides purpose‑built acceleration for securing, managing, and operating “agentic AI factories.” The offering focuses on secure access, high‑performance data movement, tenant isolation, simpler operations, and more predictable performance as…

NVIDIA Expands Open Source Commitment With OpenShell Contribution and New AI Infrastructure
NVIDIA Blog· 4 min read· Nov 10, 2026
NVIDIA Expands Open Source Commitment With OpenShell Contribution and New AI Infrastructure

NVIDIA announced the open‑source donation of OpenShell, a runtime for securing and governing autonomous agents, to the CNCF Sandbox, and contributed to the Agent Substrate framework for scaling long‑running agent workloads on Kubernetes. New components of the NVIDIA DSX AI Factory Platform—including NVIDIA Kubernetes…

NVIDIA Nemotron 3.5 Super VL is now available in Amazon SageMaker JumpStart
AWS ML Blog· 13 min read· Nov 9, 2026
NVIDIA Nemotron 3.5 Super VL is now available in Amazon SageMaker JumpStart

NVIDIA Nemotron 3.5 Super VL, a 120 B‑parameter vision‑language model with a 12 B‑active‑parameter MoE language backbone and C‑RADIO vision encoder, is now available through Amazon SageMaker JumpStart. The model supports up to 1 M token context, includes a built‑in Multi‑Token Prediction head for speculative decoding,…

NVIDIA Announces New Planned Investments in Korean Startups at the MSIT-NVIDIA AI Startup Partnership Forum
NVIDIA Blog· 4 min read· Nov 9, 2026
NVIDIA Announces New Planned Investments in Korean Startups at the MSIT-NVIDIA AI Startup Partnership Forum

NVIDIA announced a new round of investments in Korean AI startups, including a confirmed investment in Point2 and planned investments in Motif Technologies, RLWRLD, and Upstage. The targeted companies span the AI stack—from Point2’s RF‑based interconnects for AI clusters to Motif’s open‑weight large language model,…

Korea’s AI Ecosystem Advances and Secures Agentic AI With NVIDIA
NVIDIA Blog· 4 min read· Nov 9, 2026
Korea’s AI Ecosystem Advances and Secures Agentic AI With NVIDIA

NVIDIA’s OpenShell runtime and Open Agent Safety Platform are being adopted to secure AI agents, with Hyundai Motor Group exploring NemoClaw blueprints and AIM Intelligence integrating its Starfort platform for policy‑based sandboxing and malicious‑instruction detection. LG AI Research released API access to the…

NVIDIA Dynamo Recipes Bring Korea’s Leading Open Models to Production
NVIDIA Blog· 4 min read· Nov 9, 2026
NVIDIA Dynamo Recipes Bring Korea’s Leading Open Models to Production

NVIDIA announced Dynamo‑optimized deployment recipes for Korea’s leading open models—including A.X K2, K‑EXAONE 2.0, Solar Open 2, and Motif‑3—delivering up to 2× performance on NVIDIA B200 GPUs. Dynamo is an open‑source, distributed inference‑serving framework that coordinates request routing and inter‑GPU…

How NVIDIA Open Source Tools Are Helping Researchers Build Next-Generation 6G Networks
NVIDIA Blog· 5 min read· Nov 6, 2026
How NVIDIA Open Source Tools Are Helping Researchers Build Next-Generation 6G Networks

NVIDIA’s open‑source Aerial and Sionna wireless software suites have seen a 10× surge in developer adoption and over 1 million downloads, enabling researchers to prototype AI‑native 6G networks. Using these tools, a King’s College London team cut robot task completion time by up to 52.6% with goal‑oriented semantic…

New NVIDIA Cosmos 3 Open Models for Interactive World Simulation
Hugging Face Blog· 7 min read· Nov 5, 2026
New NVIDIA Cosmos 3 Open Models for Interactive World Simulation

NVIDIA introduced four new open‑weight checkpoints in the Cosmos 3 Nano family, each with 16 B trainable parameters and licensed under OpenMDW 1.1. The models—Cosmos3‑Nano‑Transfer‑Auto, Cosmos3‑Nano‑Sim‑Auto, Cosmos3‑Nano‑Sim‑Transfer, and Cosmos3‑Nano‑Sim‑Bimanual—support multi‑view, multi‑sensor driving data…

‘Hogwarts Legacy’ Gets a Magical NVIDIA DLSS 5 Upgrade on GeForce NOW
NVIDIA Blog· 6 min read· Nov 5, 2026
‘Hogwarts Legacy’ Gets a Magical NVIDIA DLSS 5 Upgrade on GeForce NOW

Hogwarts Legacy now supports NVIDIA DLSS 5 with 3D‑Guided Neural Rendering on GeForce NOW, adding lifelike lighting, material detail, and ray‑traced enhancements while preserving original geometry and textures. The update also exposes DLSS 5 developer controls, Multi‑Frame Generation, and Ray Reconstruction, letting…

Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI
NVIDIA Blog· 4 min read· Nov 3, 2026
Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI

NVIDIA is extending physical and agentic AI services to cities worldwide, leveraging Nemotron LLMs, Cosmos world models, and Metropolis video analytics on RTX PRO GPUs to enable resident‑service bots, vision agents, and digital twins. Deployments such as 1MillionBot in Spain and ITMAX’s SamurAI V2 in Malaysia…

nemotron-halloween
Hugging Face Blog· 12 min read· Oct 30, 2026
nemotron-halloween

MonsterHouse is an interactive Halloween projection built on NVIDIA’s Nemotron Voice Agent stack, using Nemotron 3 ASR (nemotron‑speech‑streaming‑en‑0.6b.q8_0.gguf) for speech‑to‑text, Nemotron 3.5 Bolt E4B 4GB with a LoRA adapter for dialogue generation, Magpie TTS Zeroshot for voice synthesis, and Audio2Face‑3D for…

Things That Go Beep in the Night: Agentic AI Joins the Search for Extraterrestrial Signals
NVIDIA Blog· 4 min read· Oct 30, 2026
Things That Go Beep in the Night: Agentic AI Joins the Search for Extraterrestrial Signals

Breakthrough Listen and the SETI Institute have integrated agentic AI into the Allen Telescope Array, using NVIDIA’s Holoscan platform to ingest and process 2.4 terabits per second of raw sensor data on RTX PRO 6000 Blackwell GPUs, enabling real‑time steering, calibration, and signal‑processing via natural‑language…

Accelerate agentic AI with NVIDIA Nemotron models on Amazon EKS and SageMaker HyperPod EKS
AWS ML Blog· 8 min read· Oct 29, 2026
Accelerate agentic AI with NVIDIA Nemotron models on Amazon EKS and SageMaker HyperPod EKS
NVIDIA’s Nemotron 3.5 Super VL, a 120‑B parameter mixture‑of‑experts model, merges multimodal perception, reasoning, and tool‑use capabilities into a single architecture. The post details how the model’s expert routing and dynamic sparsity enable efficient scaling on GPU‑rich clusters, and demonstrates end‑to‑end…

Thin, Light and Built for Everything: NVIDIA RTX Spark Windows Laptops Gain New Models, Agent Tools and Games
NVIDIA Blog· 8 min read· Oct 28, 2026
Thin, Light and Built for Everything: NVIDIA RTX Spark Windows Laptops Gain New Models, Agent Tools and Games

NVIDIA RTX Spark laptops now ship with a Blackwell RTX GPU and Grace CPU unified in a single super‑chip offering up to 128 GB of memory and 1 PFLOP of FP4 AI performance, bringing personal‑AI supercomputer capabilities to thin‑and‑light Windows devices. The launch adds the open‑weight Nemotron 3.5 Transcribe speech…

NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Hugging Face Blog· 5 min read· Oct 28, 2026
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt

NVIDIA Nemotron 3.5 Transcribe is an open‑weight, promptable multilingual speech model that jointly performs transcription, speaker diarization, translation, and audio Q&A across 40 languages (31 for translation) and supports up to eight speakers per hour‑long recording. It leads the Hugging Face Open ASR leaderboard…

Kazakhstan Expands Compute for Its AI Future
NVIDIA Blog· 6 min read· Oct 23, 2026
Kazakhstan Expands Compute for Its AI Future

Kazakhstan is accelerating its AI ecosystem by expanding accelerated compute infrastructure and launching initiatives like Kazakh‑language models, while NVIDIA announced an investment in local startup Higgsfield AI and highlighted its OpenShell tool for securely containing AI agents. The push ties the nation’s…

NVIDIA Cosmos Opens New Tools to Train, Evaluate and Deploy World Models
NVIDIA Blog· 4 min read· Oct 22, 2026
NVIDIA Cosmos Opens New Tools to Train, Evaluate and Deploy World Models
NVIDIA’s Cosmos platform now includes dedicated training tools, simulation checkpoints, and Cosmos Data Factory blueprints that streamline the creation, evaluation, and deployment of world models. The updated suite has already placed the platform in the top five across six open-model leaderboards, demonstrating its…

NVIDIA Transforms European Retail, From Digital Discovery to Physical Operations
NVIDIA Blog· 5 min read· Oct 22, 2026
NVIDIA Transforms European Retail, From Digital Discovery to Physical Operations
NVIDIA‑accelerated open models are delivering frontier‑level accuracy for European retailers while slashing inference costs up to 90% and boosting response speed up to 7×. Shopify’s post‑trained Nemotron 3.5 Lightning, fine‑tuned with the Megatron Bridge library and reinforced with NeMo RL, outperforms a leading…

NVIDIA Open Models Power a New Wave of European Public Sector Projects
NVIDIA Blog· 5 min read· Oct 22, 2026
NVIDIA Open Models Power a New Wave of European Public Sector Projects

NVIDIA’s open‑source Nemotron‑Personas collection and related tools are being adopted across European public‑sector projects to enable locally‑adapted, controllable AI services. Governments are deploying NVIDIA Triton Inference Server, DGX BasePOD hardware, and the MONAI framework to run models such as PLLuM, GPT OSS,…

Bringing the Spark to Europe: Local Intelligence Powers Next Wave of Agents
NVIDIA Blog· 9 min read· Oct 21, 2026
Bringing the Spark to Europe: Local Intelligence Powers Next Wave of Agents

NVIDIA unveiled its RTX Spark and DGX Spark hardware line‑up at GTC Berlin, enabling fully local personal agents on Windows PCs and scalable multi‑GPU clusters for developers on Linux. The RTX Spark platform delivers up to 128 GB unified memory, 1 peta‑FLOP AI compute, and supports the Underdog Desktop Agent powered…

Google Cloud and NVIDIA Announce General Availability of NVIDIA Vera Rubin Infrastructure
NVIDIA Blog· 4 min read· Oct 21, 2026
Google Cloud and NVIDIA Announce General Availability of NVIDIA Vera Rubin Infrastructure
Google Cloud and NVIDIA announced the general availability of A5X instances built on NVIDIA Vera Rubin NVL72 GPUs, combining high‑bandwidth ConnectX‑9 SuperNICs, Virgo networking, and advanced liquid‑cooling for demanding agentic inference and reinforcement‑learning workloads. The platform will scale to as many as…

Europe’s Industrial Leaders Reinvent Engineering and Manufacturing With NVIDIA
NVIDIA Blog· 5 min read· Oct 21, 2026
Europe’s Industrial Leaders Reinvent Engineering and Manufacturing With NVIDIA

NVIDIA’s Factory Operations Blueprint (FOX) enables developers to build always‑on factory manager agents that leverage CUDA‑X, Omniverse, Cosmos and Nemotron models for real‑time monitoring, visual inspection, root‑cause analysis, and fleet management. Early‑access FOX on GitHub lets Siemens integrate agents into its…

NVIDIA cuDSS Now Generally Available to Accelerate Engineering and Scientific Simulations
NVIDIA Blog· 4 min read· Oct 21, 2026
NVIDIA cuDSS Now Generally Available to Accelerate Engineering and Scientific Simulations
NVIDIA cuDSS, now generally available, is a CUDA‑X library that offloads large sparse linear system solves to GPUs, delivering order‑of‑magnitude speedups for engineering and scientific simulations. Reported accelerations include up to 10× on Applied Materials’ Ginestra platform, 4× on a ZEISS EUV lithography plasma…

NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure
NVIDIA Blog· 4 min read· Oct 21, 2026
NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure

NVIDIA announced the Confidential Bare Metal deployment option for its Confidential Computing stack, allowing frontier model builders to run sensitive workloads on dedicated third‑party bare‑metal infrastructure while retaining full control of models and data. The expanded security architecture now includes three…

NVIDIA Agent Toolkit Expands, Grounding Enterprise Agents in Company Data
NVIDIA Blog· 4 min read· Oct 21, 2026
NVIDIA Agent Toolkit Expands, Grounding Enterprise Agents in Company Data

NVIDIA expands its open‑source Agent Toolkit with the Agent Knowledge Foundation, adding CUDA‑X libraries, Auto‑Ontology, Nemotron Retriever and the Kumo family of structured models to let enterprises ground agents in proprietary data without moving it. The foundation includes secure runtime (OpenShell) and blueprints…

GTC Berlin 2026: Live Updates From NVIDIA CEO Jensen Huang’s Keynote
NVIDIA Blog· 10 min read· Oct 21, 2026
GTC Berlin 2026: Live Updates From NVIDIA CEO Jensen Huang’s Keynote
NVIDIA CEO Jensen Huang announced the DSX POD reference design, a modular containerized AI factory that can be deployed in 14 days versus six months, delivering up to 30 % lower power consumption and up to 100 % water‑cooling reduction. He positioned agents as the new computing platform, highlighting the Vera Rubin…

Deploy RFD4-Proteina on Databricks
Databricks Blog· 6 min read· Oct 21, 2026
Deploy RFD4-Proteina on Databricks

The announcement describes how to bring the RFD4-Proteina model to research data using AI‑assisted development on Databricks with serverless NVIDIA GPU compute. It highlights a serverless GPU offering for model deployment, enabling researchers to run the model without managing infrastructure. This simplifies scaling…

Spain-Based Startups Advance Regional Innovation With Barcelona Supercomputing Center
NVIDIA Blog· 4 min read· Oct 20, 2026
Spain-Based Startups Advance Regional Innovation With Barcelona Supercomputing Center
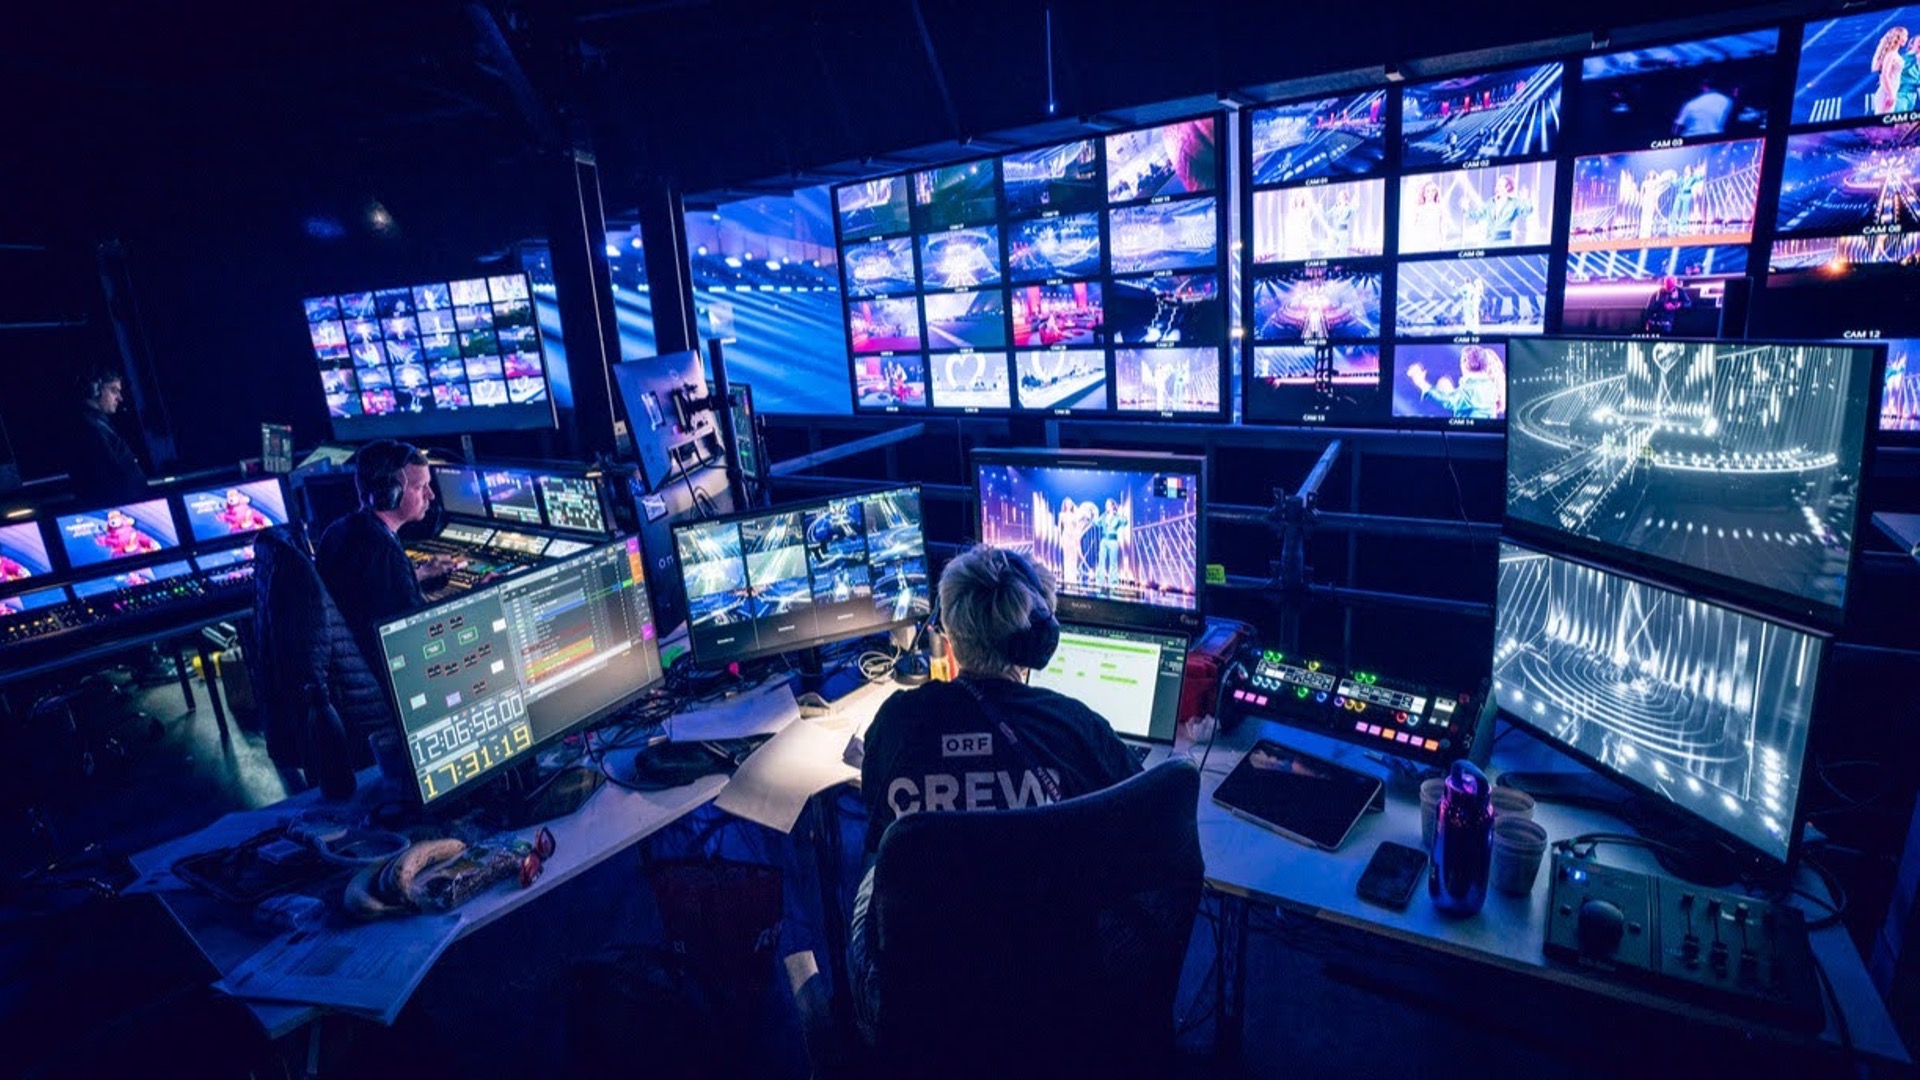
The Barcelona Supercomputing Center (BSC) AI Factory Accelerator Programme, launched in April 2025, has delivered over 800 AI services and now offers sovereign compute, training, and NVIDIA Inception resources to startups across Europe. Member startups are leveraging NVIDIA‑accelerated stacks—including cuGraph,…

NVIDIA Advances Agentic Security for Media, From European Public Service Broadcasting to Global Content Production
NVIDIA Blog· 4 min read· Oct 19, 2026
NVIDIA Advances Agentic Security for Media, From European Public Service Broadcasting to Global Content Production

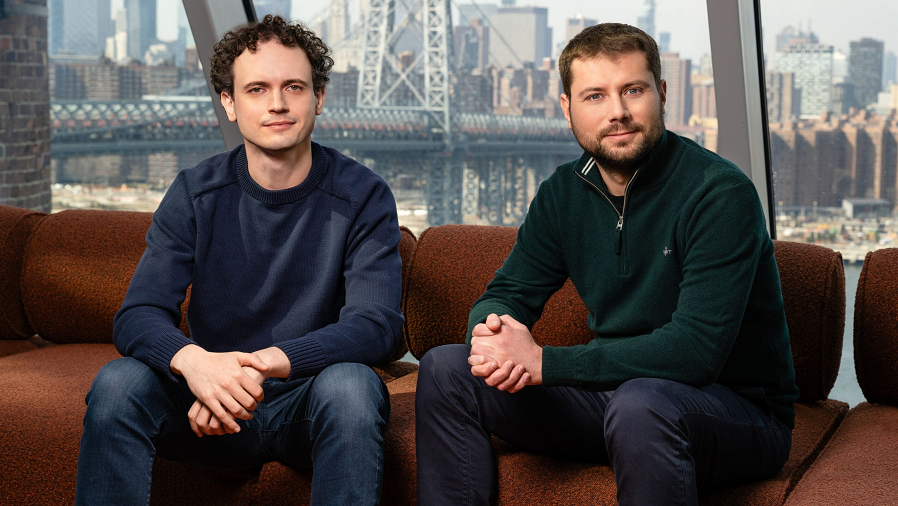
NVIDIA is extending its agentic security framework for European broadcasters by defining sovereign cloud standards, open‑model reference architectures, and integration partners, while also accelerating Adobe Frame.io’s video search pipeline with GPU‑based decoding and inference. The initiative incorporates Microsoft…

Nvidia reportedly in early talks to buy, acquihire or invest more in Reflection AI
SiliconANGLE AI· Oct 11, 2026
Nvidia reportedly in early talks to buy, acquihire or invest more in Reflection AI

Nvidia is reportedly in early discussions to either acquire, acquihire, or increase its investment in Reflection AI, the developer of open-weight models. Sources say an agreement could be reached within weeks, though the talks remain tentative and could fall apart. This potential deal signals Nvidia’s continued…

AI Agents Beat PyTorch: Writing Faster CUDA Kernels
Towards Data Science· Oct 8, 2026
AI Agents Beat PyTorch: Writing Faster CUDA Kernels

AI agents can generate CUDA kernels that outperform PyTorch implementations, as demonstrated on an NVIDIA DGX Spark. The authors benchmarked the agent‑written kernels against PyTorch, revealing that careful benchmark design is as critical as the code itself for validating speedups. While the agent achieves higher…

From Scan to Treatment Plan, AI Helps Close Breast Cancer’s Deadliest Gaps
NVIDIA Blog· 6 min read· Oct 5, 2026
From Scan to Treatment Plan, AI Helps Close Breast Cancer’s Deadliest Gaps
NVIDIA‑backed startup iSono Health’s FDA‑cleared ATUSA platform uses GPU‑accelerated AI to acquire a standardized 3‑D breast ultrasound in roughly two minutes per breast—dramatically faster than the up‑to‑45‑minute handheld approach. Trained on over 1.5 million ultrasound frames, the system claims a 28 % sensitivity…

NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI
NVIDIA Blog· 5 min read· Oct 2, 2026
NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI
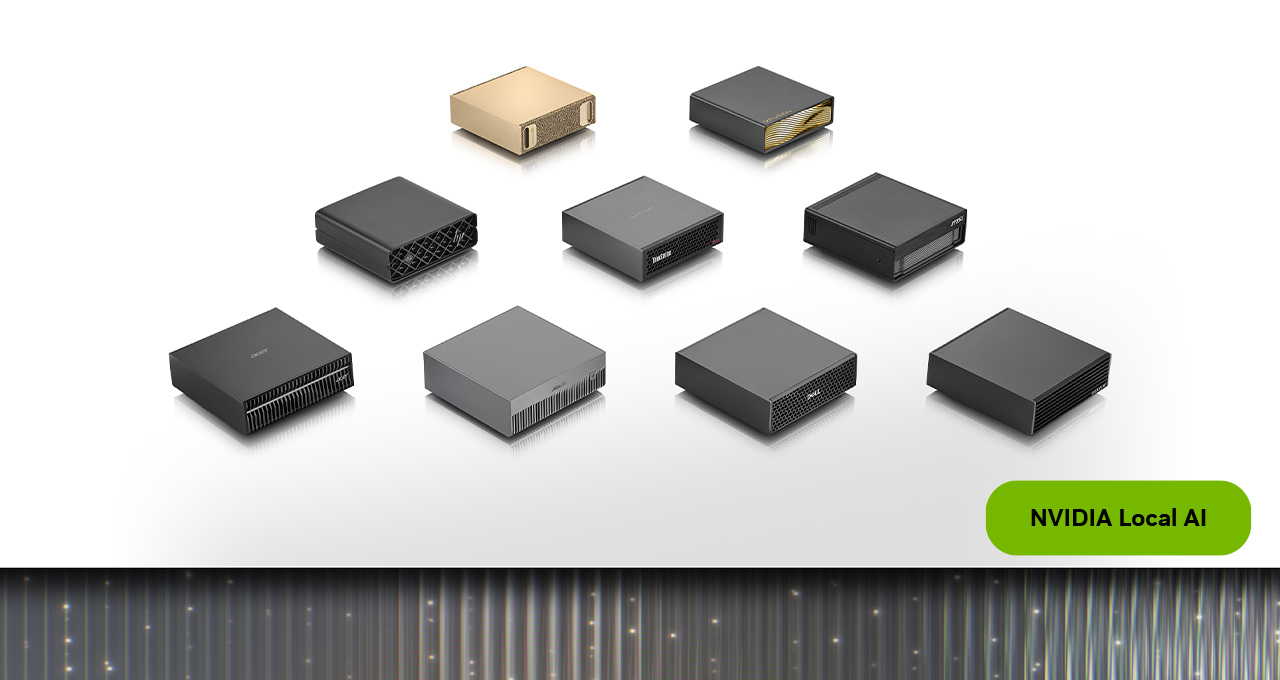
NVIDIA’s DGX Spark 64 GB workstation brings a full AI software stack—including DGX OS, CUDA‑X AI libraries, Nemotron models, and runtimes like Ollama, vLLM, and PyTorch—together with 64 GB of unified memory and Grace Blackwell compute, enabling on‑device execution of up to 100‑billion‑parameter models. When two units…

How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast
NVIDIA Blog· 4 min read· Oct 1, 2026
How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast

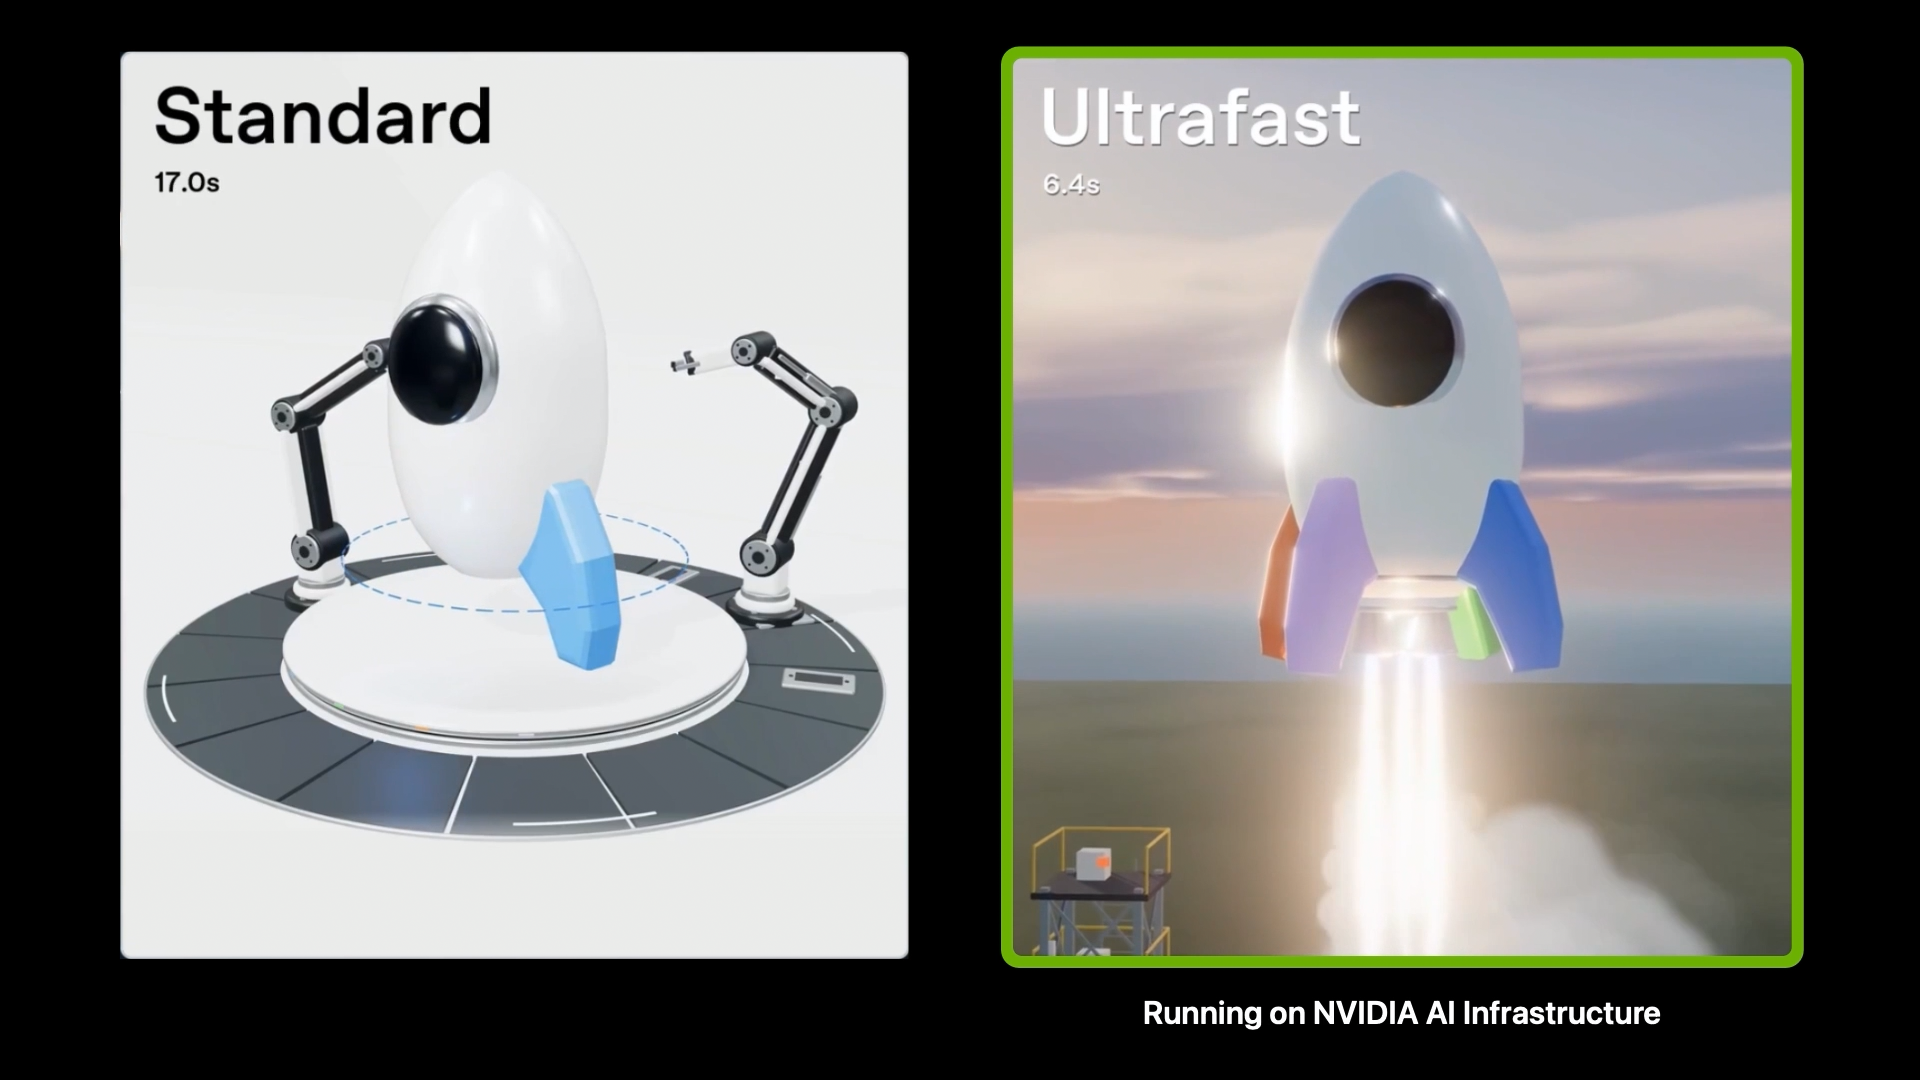
OpenAI’s new GPT‑6 “Astra Ultrafast” model is now available in the OpenAI API and for eligible ChatGPT Work and Codex users, running exclusively on NVIDIA’s Blackwell GPUs. Leveraging inference optimizations that tap into Blackwell’s architecture, the model delivers up to 8× faster inference latency compared to prior…

Build agent memory with NVIDIA NeMo Agent Toolkit and Amazon S3 Vectors
AWS ML Blog· 14 min read· Oct 1, 2026
Build agent memory with NVIDIA NeMo Agent Toolkit and Amazon S3 Vectors
NVIDIA’s NeMo Agent Toolkit (NAT) now supports Amazon S3 Vectors as a persistent memory provider, enabling agents to retain contextual knowledge across sessions. By deploying NAT on Amazon EKS, the memory subsystem can be configured to use S3 Vectors for low‑latency vector retrieval, while still leveraging Kubernetes’…

Productive, Durable, Fungible: How NVIDIA AI Factories Maximize Return on Investment
NVIDIA Blog· 7 min read· Oct 1, 2026
Productive, Durable, Fungible: How NVIDIA AI Factories Maximize Return on Investment

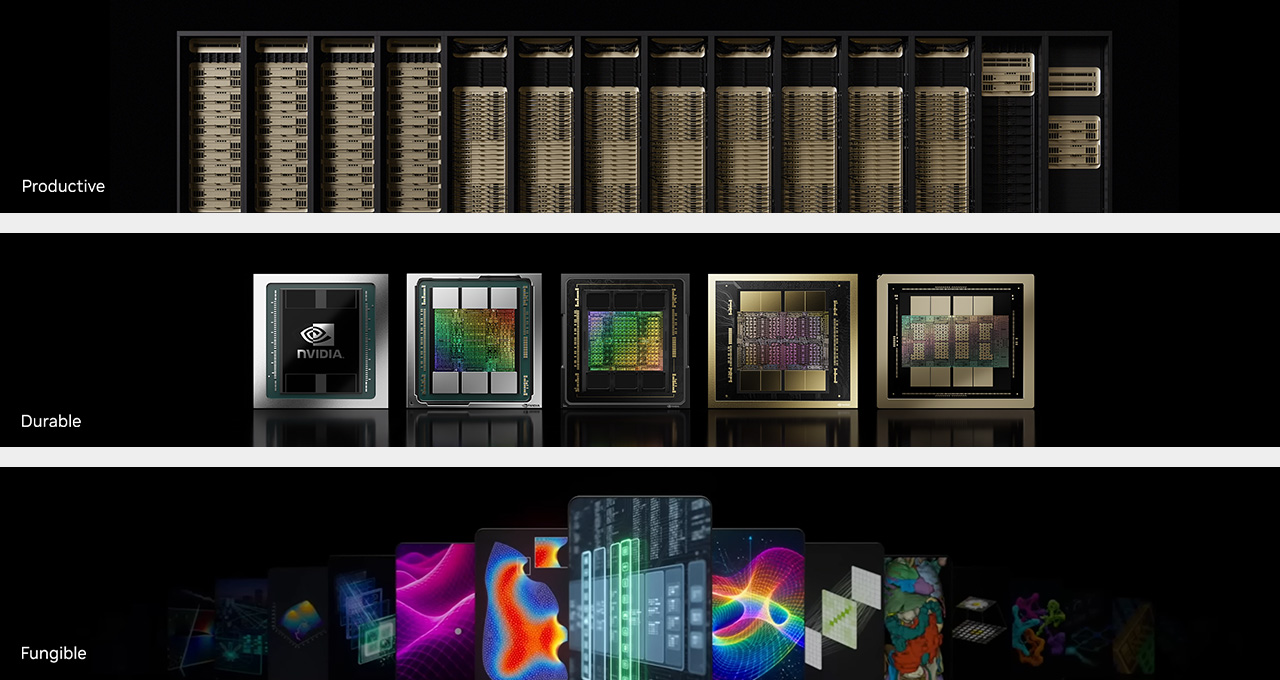
NVIDIA AI factories are engineered to be productive, durable, and fungible, delivering up to 30× higher throughput per megawatt and up to 45× lower cost per million tokens compared to prior generations, while extending hardware useful life for years after shipment. By co‑designing across the full stack—from models and…

NVIDIA Opens Applications for 2027–2028 Graduate Fellowships With Awards Up to $60,000
NVIDIA Blog· 4 min read· Sep 30, 2026
NVIDIA Opens Applications for 2027–2028 Graduate Fellowships With Awards Up to $60,000

NVIDIA’s 26‑year Graduate Fellowship Program is now open for 2027‑2028 applications, offering awards of up to $60,000 per doctoral student and mandating a summer 2027 in‑person internship at an NVIDIA research office. Since its 2002 inception the program has granted over 220 fellowships totaling roughly $8 million,…

From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI
NVIDIA Blog· 6 min read· Sep 30, 2026
From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI

NVIDIA’s Vera Rubin NVL72 systems, now available on CoreWeave Cloud, deliver up to 4.8× higher token throughput for agentic coding workloads compared with the prior‑generation GB200 NVL72. Cognition, the AI lab behind the Devin software‑engineer agent, benchmarked this gain on real‑world software‑engineering tasks,…

NVIDIA Launches DSX Ready to Qualify Power and Cooling Products for AI Factories
NVIDIA Blog· 4 min read· Sep 21, 2026
NVIDIA Launches DSX Ready to Qualify Power and Cooling Products for AI Factories

NVIDIA has announced the DSX platform, a qualification framework for power and cooling solutions tailored to AI factories. The initiative emphasizes aligning cooling, water, and grid infrastructure with the specific compute architecture of AI workloads, addressing constraints that arise as AI infrastructure scales. By…

Fault tolerant distributed training on Amazon EKS using NVRx
AWS ML Blog· 15 min read· Sep 16, 2026
Fault tolerant distributed training on Amazon EKS using NVRx

The article demonstrates how NVIDIA Resiliency Extension (NVRx) can be integrated into PyTorch Fully Sharded Data Parallel (FSDP) training on Amazon EKS, enabling asynchronous checkpoint I/O that overlaps with training and allowing in‑process GPU fault recovery within seconds. Benchmarks on H100 GPUs across 2 to 8…

NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut
NVIDIA Blog· 5 min read· Sep 16, 2026
NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut

NVIDIA’s new Vera Rubin NVL72 system debuted in MLPerf Inference v6.1, delivering up to 3.7× higher throughput than the prior‑generation GB300 NVL72 on the Qwen3‑VL benchmark and up to 2.5× higher on DeepSeek‑R1. The gains stem from enhanced Tensor Cores, the Transformer Engine, NVFP4 precision, and software stacks…

University of Manchester Uses NVIDIA Earth-2 to Forecast Air Pollution Across the UK
NVIDIA Blog· 5 min read· Sep 16, 2026
University of Manchester Uses NVIDIA Earth-2 to Forecast Air Pollution Across the UK
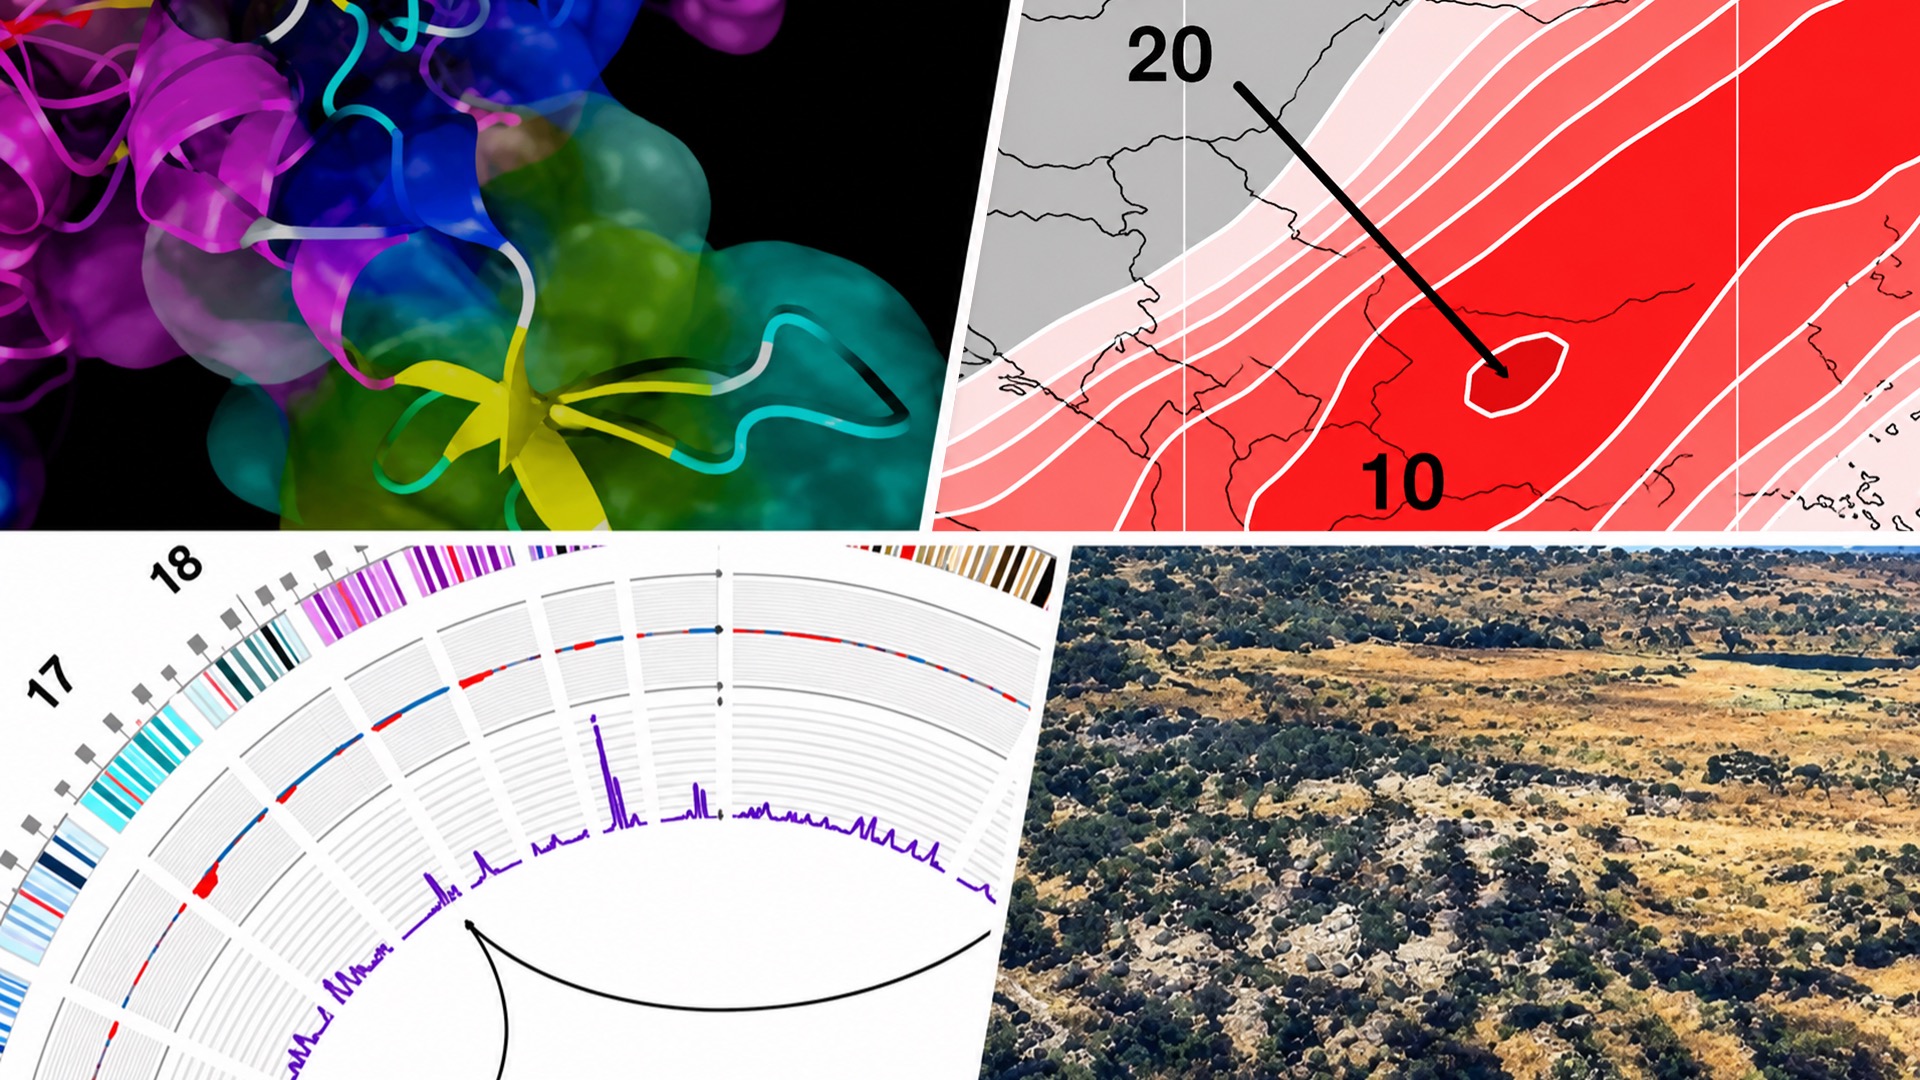
The University of Manchester leveraged NVIDIA’s Earth‑2 family to build a UK‑wide air‑pollution forecast, training the CorrDiff generative downscaling model on the Isambard‑AI supercomputer in just two days and deploying inference on a single‑GPU‑desk‑top DGX Spark. The workflow used a year of hourly simulated…

AI Infra Summit: NVIDIA Vera Rubin and DSX Platform Advancements Showcase Energy Efficiencies of Optimizing Tokens Per Watt for AI Factories
NVIDIA Blog· 10 min read· Sep 15, 2026
AI Infra Summit: NVIDIA Vera Rubin and DSX Platform Advancements Showcase Energy Efficiencies of Optimizing Tokens Per Watt for AI Factories

NVIDIA showcased its Vera Rubin and DSX platforms at the AI Infra Summit, highlighting a 1.4× boost in tokens per megawatt with DSX MaxLPS and a 3.7× higher throughput for the Vera Rubin NVL72 system over the prior GB300 NVL72. The announcements emphasized new collaborations (e.g., Amazon Annapurna Labs on NVHBM,…

Salesforce debuts Koa, a specialized model built to reason about CRM data
SiliconANGLE AI· Sep 15, 2026
Salesforce debuts Koa, a specialized model built to reason about CRM data

Salesforce announced Koa, a domain‑specific AI model designed to reason over CRM data, built on Nvidia’s Nemotron architecture. The partnership leverages Nvidia’s GPU‑optimized transformer stack to deliver specialized inference tailored to customer‑relationship workflows. Koa is released as part of Salesforce’s AI…

Perplexity Portable Computer Is Now Available on Windows, Powered by NVIDIA RTX
NVIDIA Blog· 4 min read· Sep 14, 2026
Perplexity Portable Computer Is Now Available on Windows, Powered by NVIDIA RTX

Perplexity Portable Computer, a local version of the AI agent Perplexity Computer, has been released for Windows and is accelerated by NVIDIA RTX GPUs. The new portable tool enables multi‑step task planning and execution entirely on a PC, keeping sensitive data on the device rather than in the cloud. Engineers can now…

Physical AI Takes the Wheel: How the World’s Robotaxi Leaders Are Building With NVIDIA Technologies
NVIDIA Blog· 7 min read· Sep 10, 2026
Physical AI Takes the Wheel: How the World’s Robotaxi Leaders Are Building With NVIDIA Technologies

NVIDIA’s DRIVE platform is now powering the first large‑scale robotaxi fleets, with the global market projected to hit $400 billion by 2035 and more than 6 million commercial vehicles already on the road. The architecture couples NVIDIA’s high‑performance GPUs with a unified perception‑planning‑control stack that can…

d-Matrix Adopts NVIDIA NVLink Fusion for Rack-Scale XPU Deployment
NVIDIA Blog· 4 min read· Sep 10, 2026
d-Matrix Adopts NVIDIA NVLink Fusion for Rack-Scale XPU Deployment

d‑Matrix announced that its next‑generation Raptor XPUs will be connected via NVIDIA NVLink Fusion to NVIDIA’s MGX rack architecture and AI platform, enabling a unified, liquid‑cooled rack that supports GPUs, CPUs and XPUs with high‑bandwidth, low‑latency links. By leveraging NVLink Fusion, d‑Matrix can tap into…

Build a Physical AI model factory with NVIDIA Cosmos 3 on SageMaker HyperPod
AWS ML Blog· 38 min read· Sep 4, 2026
Build a Physical AI model factory with NVIDIA Cosmos 3 on SageMaker HyperPod
This post details how to construct a continuous Physical AI model factory on Amazon SageMaker HyperPod using NVIDIA Cosmos 3, a Mixture‑of‑Transformers (MoT) foundation model with per‑layer joint attention and a train‑versus‑inference asymmetry. Cosmos 3’s single‑token‑stream design supports video, image, action, and…

Nvidia PAIR makes it easy to create a household data center for running agentic AI tasks
SiliconANGLE AI· Sep 4, 2026
Nvidia PAIR makes it easy to create a household data center for running agentic AI tasks
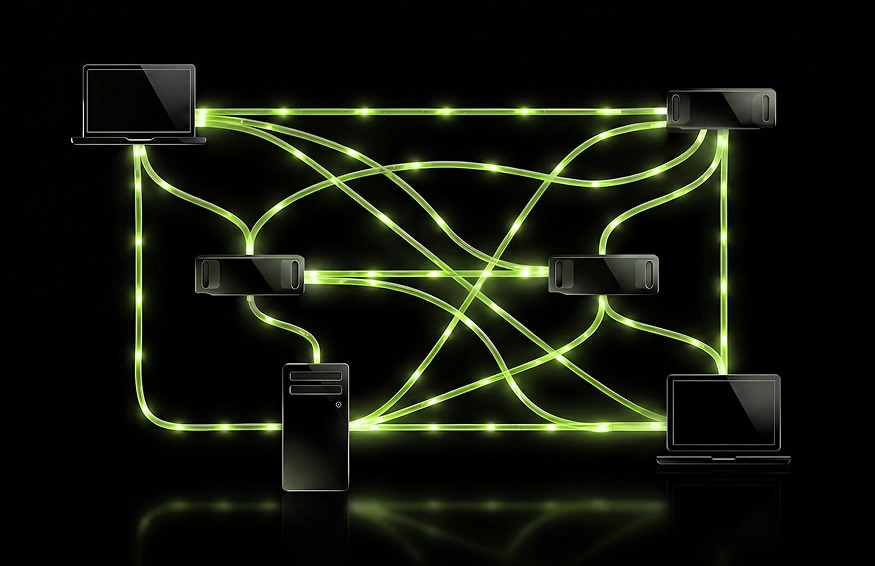
Nvidia Corp. has unveiled the Personal AI Router (PAIR), a local distributed clustering tool that lets users harness idle Macs or PCs to run small language models on demand. PAIR orchestrates these heterogeneous devices into a household data center, enabling rapid acceleration of agentic workloads without relying on…

Nvidia’s Hugging Face deal is a bet on open models — and proof it’s no longer just a chip company
SiliconANGLE AI· Sep 4, 2026
Nvidia’s Hugging Face deal is a bet on open models — and proof it’s no longer just a chip company

Nvidia announced its $12.93 billion acquisition of Hugging Face, pledging to keep the platform’s brand and leadership intact while integrating it into Nvidia’s broader AI ecosystem. The deal underscores Nvidia’s pivot from pure hardware to an open‑model platform, positioning Hugging Face’s extensive model hub as a…

Sparks Fly: NVIDIA Accelerates Local AI at IFA 2026
NVIDIA Blog· 10 min read· Sep 3, 2026
Sparks Fly: NVIDIA Accelerates Local AI at IFA 2026

NVIDIA unveiled the RTX Spark line of compact Windows PCs at IFA 2026, positioning them as turnkey platforms for local AI inference. The collaboration with Microsoft and partners promises accelerated inference on NVIDIA GPUs and a new suite of agent‑oriented tooling that simplifies deployment on these machines. While…

‘NBA 2K27’ With NVIDIA DLSS 5 Leads 28 New Games Coming to GeForce NOW
NVIDIA Blog· 5 min read· Sep 3, 2026
‘NBA 2K27’ With NVIDIA DLSS 5 Leads 28 New Games Coming to GeForce NOW

NVIDIA adds NBA 2K27 with DLSS 5 3D‑Guided Neural Rendering to GeForce NOW, showcasing AI‑enhanced lighting and material detail for cloud‑streamed gameplay. The rollout includes 28 new titles this month, all accessible to Ultimate members on RTX 5080‑class cloud rigs. DLSS 5 is only available when streaming from these…

NVIDIA to Acquire Hugging Face
NVIDIA Blog· 4 min read· Sep 3, 2026
NVIDIA to Acquire Hugging Face

NVIDIA announced a $12,930,300,000 acquisition of Hugging Face, aiming to scale the platform’s infrastructure and broaden open‑weight model access for over 18 million developers. The deal leverages NVIDIA’s compute and engineering resources to improve reliability, safety, model evaluation, inference, and deployment…

Reduce ASR inference costs by 75% with NVIDIA MPS on Amazon EC2
AWS ML Blog· 16 min read· Aug 27, 2026
Reduce ASR inference costs by 75% with NVIDIA MPS on Amazon EC2
This post shows that using NVIDIA CUDA Multi‑Process Service (MPS) together with the Triton Inference Server on Amazon EC2 cuts the number of required GPUs for Nemotron Parakeet TDT 0.6B V2 ASR serving by 75 % (from 16 L40S GPUs to 4) while keeping sub‑second latency and achieving 92.1 requests per second per GPU. The…

Perplexity partners with Nvidia to launch Portable Computer, a fully local AI agent with zero token costs
VentureBeat AI· 11 min read· Aug 25, 2026
Perplexity partners with Nvidia to launch Portable Computer, a fully local AI agent with zero token costs

Perplexity’s new Portable Computer lets its “Computer” agent run entirely on‑premise using Nvidia hardware—specifically Nvidia DGX Spark desktops or Linux machines equipped with Nvidia RTX GPUs—by loading a 27‑billion‑parameter Qwen model locally. The full agent stack (model, harness, inference engine, tools, and…

With Groq 3 LPX in Full Production, NVIDIA Extends Vera Rubin Inference for Agents
NVIDIA Blog· 10 min read· Aug 24, 2026
With Groq 3 LPX in Full Production, NVIDIA Extends Vera Rubin Inference for Agents

NVIDIA announced that its Vera Rubin NVL72 system, now paired with the Groq 3 LPX accelerator, can generate 3,400 output tokens per second on a 100,000‑token long‑context run of the open‑source agentic model Gemma 4 31B—four times faster than the closest competing platform. The full‑stack, “extreme codesign” approach…

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING