How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast
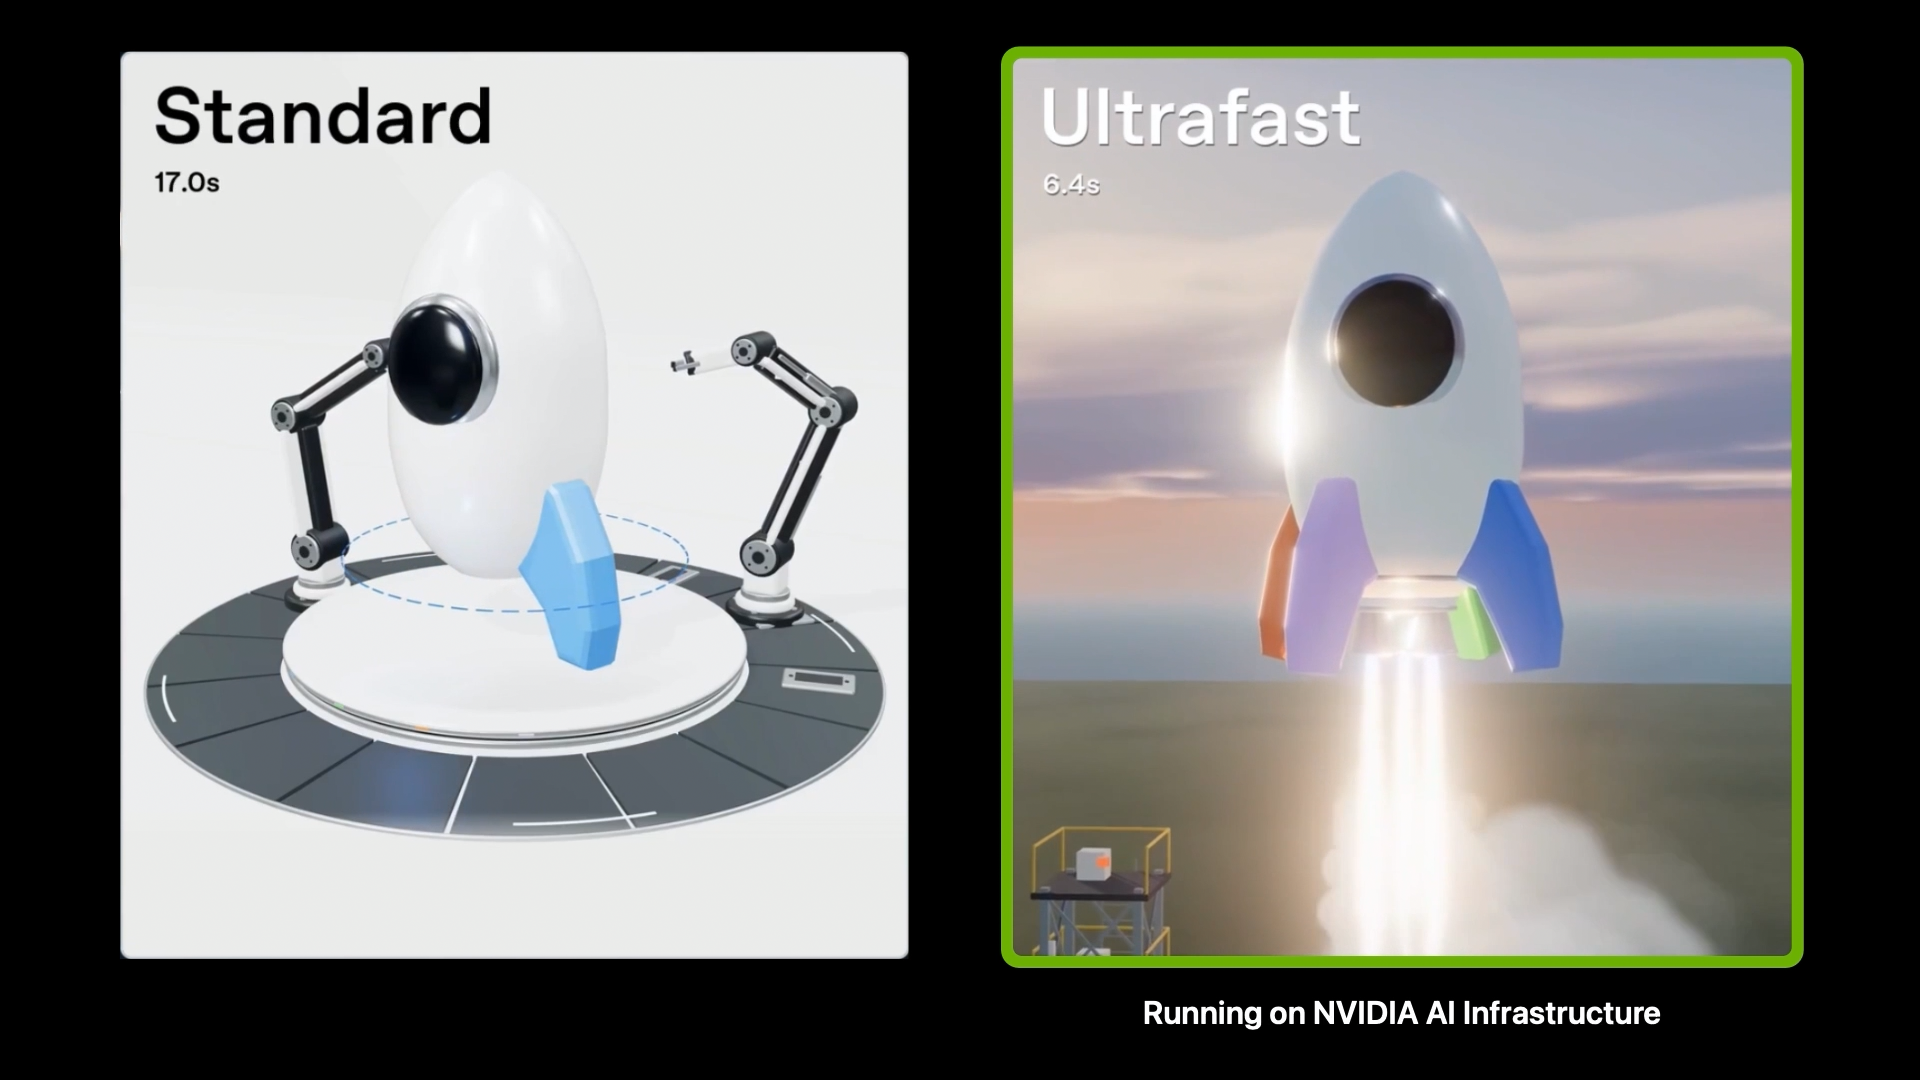
OpenAI’s new GPT‑6 “Astra Ultrafast” model is now available in the OpenAI API and for eligible ChatGPT Work and Codex users, running exclusively on NVIDIA’s Blackwell GPUs. Leveraging inference optimizations that tap into Blackwell’s architecture, the model delivers up to 8× faster inference latency compared to prior GPT‑6 variants. This performance boost comes at the cost of requiring Blackwell‑compatible hardware, limiting access to users with the necessary GPU infrastructure. Engineers can immediately start using the model by specifying the model name in their API calls, but must ensure their deployment environment supports Blackwell GPUs to realize the speed gains.
⚡ Key Takeaways
- GPT‑6 Astra Ultrafast delivers up to 8× faster inference latency on NVIDIA Blackwell GPUs.
- The model is accessible via the OpenAI API under the “gpt‑6‑ultrafast” endpoint.
- Deployment requires Blackwell‑compatible GPUs, restricting usage to environments that can provision that hardware.
- Eligible users can enable the model by passing the model identifier in their OpenAI API requests.
- WhyItMatters: For production workloads that demand low‑latency generation, the 8× speedup can dramatically reduce compute costs and improve user experience, but only if the deployment stack can provision Blackwell GPUs.
- TechnicalLevel: Intermediate
- TargetAudience: ML Engineers, Deployment Engineers
- PracticalSteps:
- Invoke the OpenAI API with `model="gpt-6-ultrafast"` in your request payload.
- Verify that your GPU cluster is provisioned with NVIDIA Blackwell GPUs before scaling.
- Monitor inference latency and cost metrics to confirm the expected performance gains.
- ToolsMentioned: OpenAI API, NVIDIA Blackwell GPUs
- Tags: LLM, COMPUTE, DEPLOYMENT, NVIDIA
🔧 Tools & Libraries
For production workloads that demand low‑latency generation, the 8× speedup can dramatically reduce compute costs and improve user experience, but only if the deployment stack can provision Blackwell GPUs.
✅ Practical Steps
- Invoke the OpenAI API with `model="gpt-6-ultrafast"` in your request payload.
- Verify that your GPU cluster is provisioned with NVIDIA Blackwell GPUs before scaling.
- Monitor inference latency and cost metrics to confirm the expected performance gains.
Want the full story? Read the original article.
Read on NVIDIA Blog ↗