Home›Inference

Inference

5 curated articles on Inference for AI engineers

5 articles
Local Agentic AI Workflows with Hermes + Ollama
Machine Learning Mastery· 5 days ago
Local Agentic AI Workflows with Hermes + Ollama

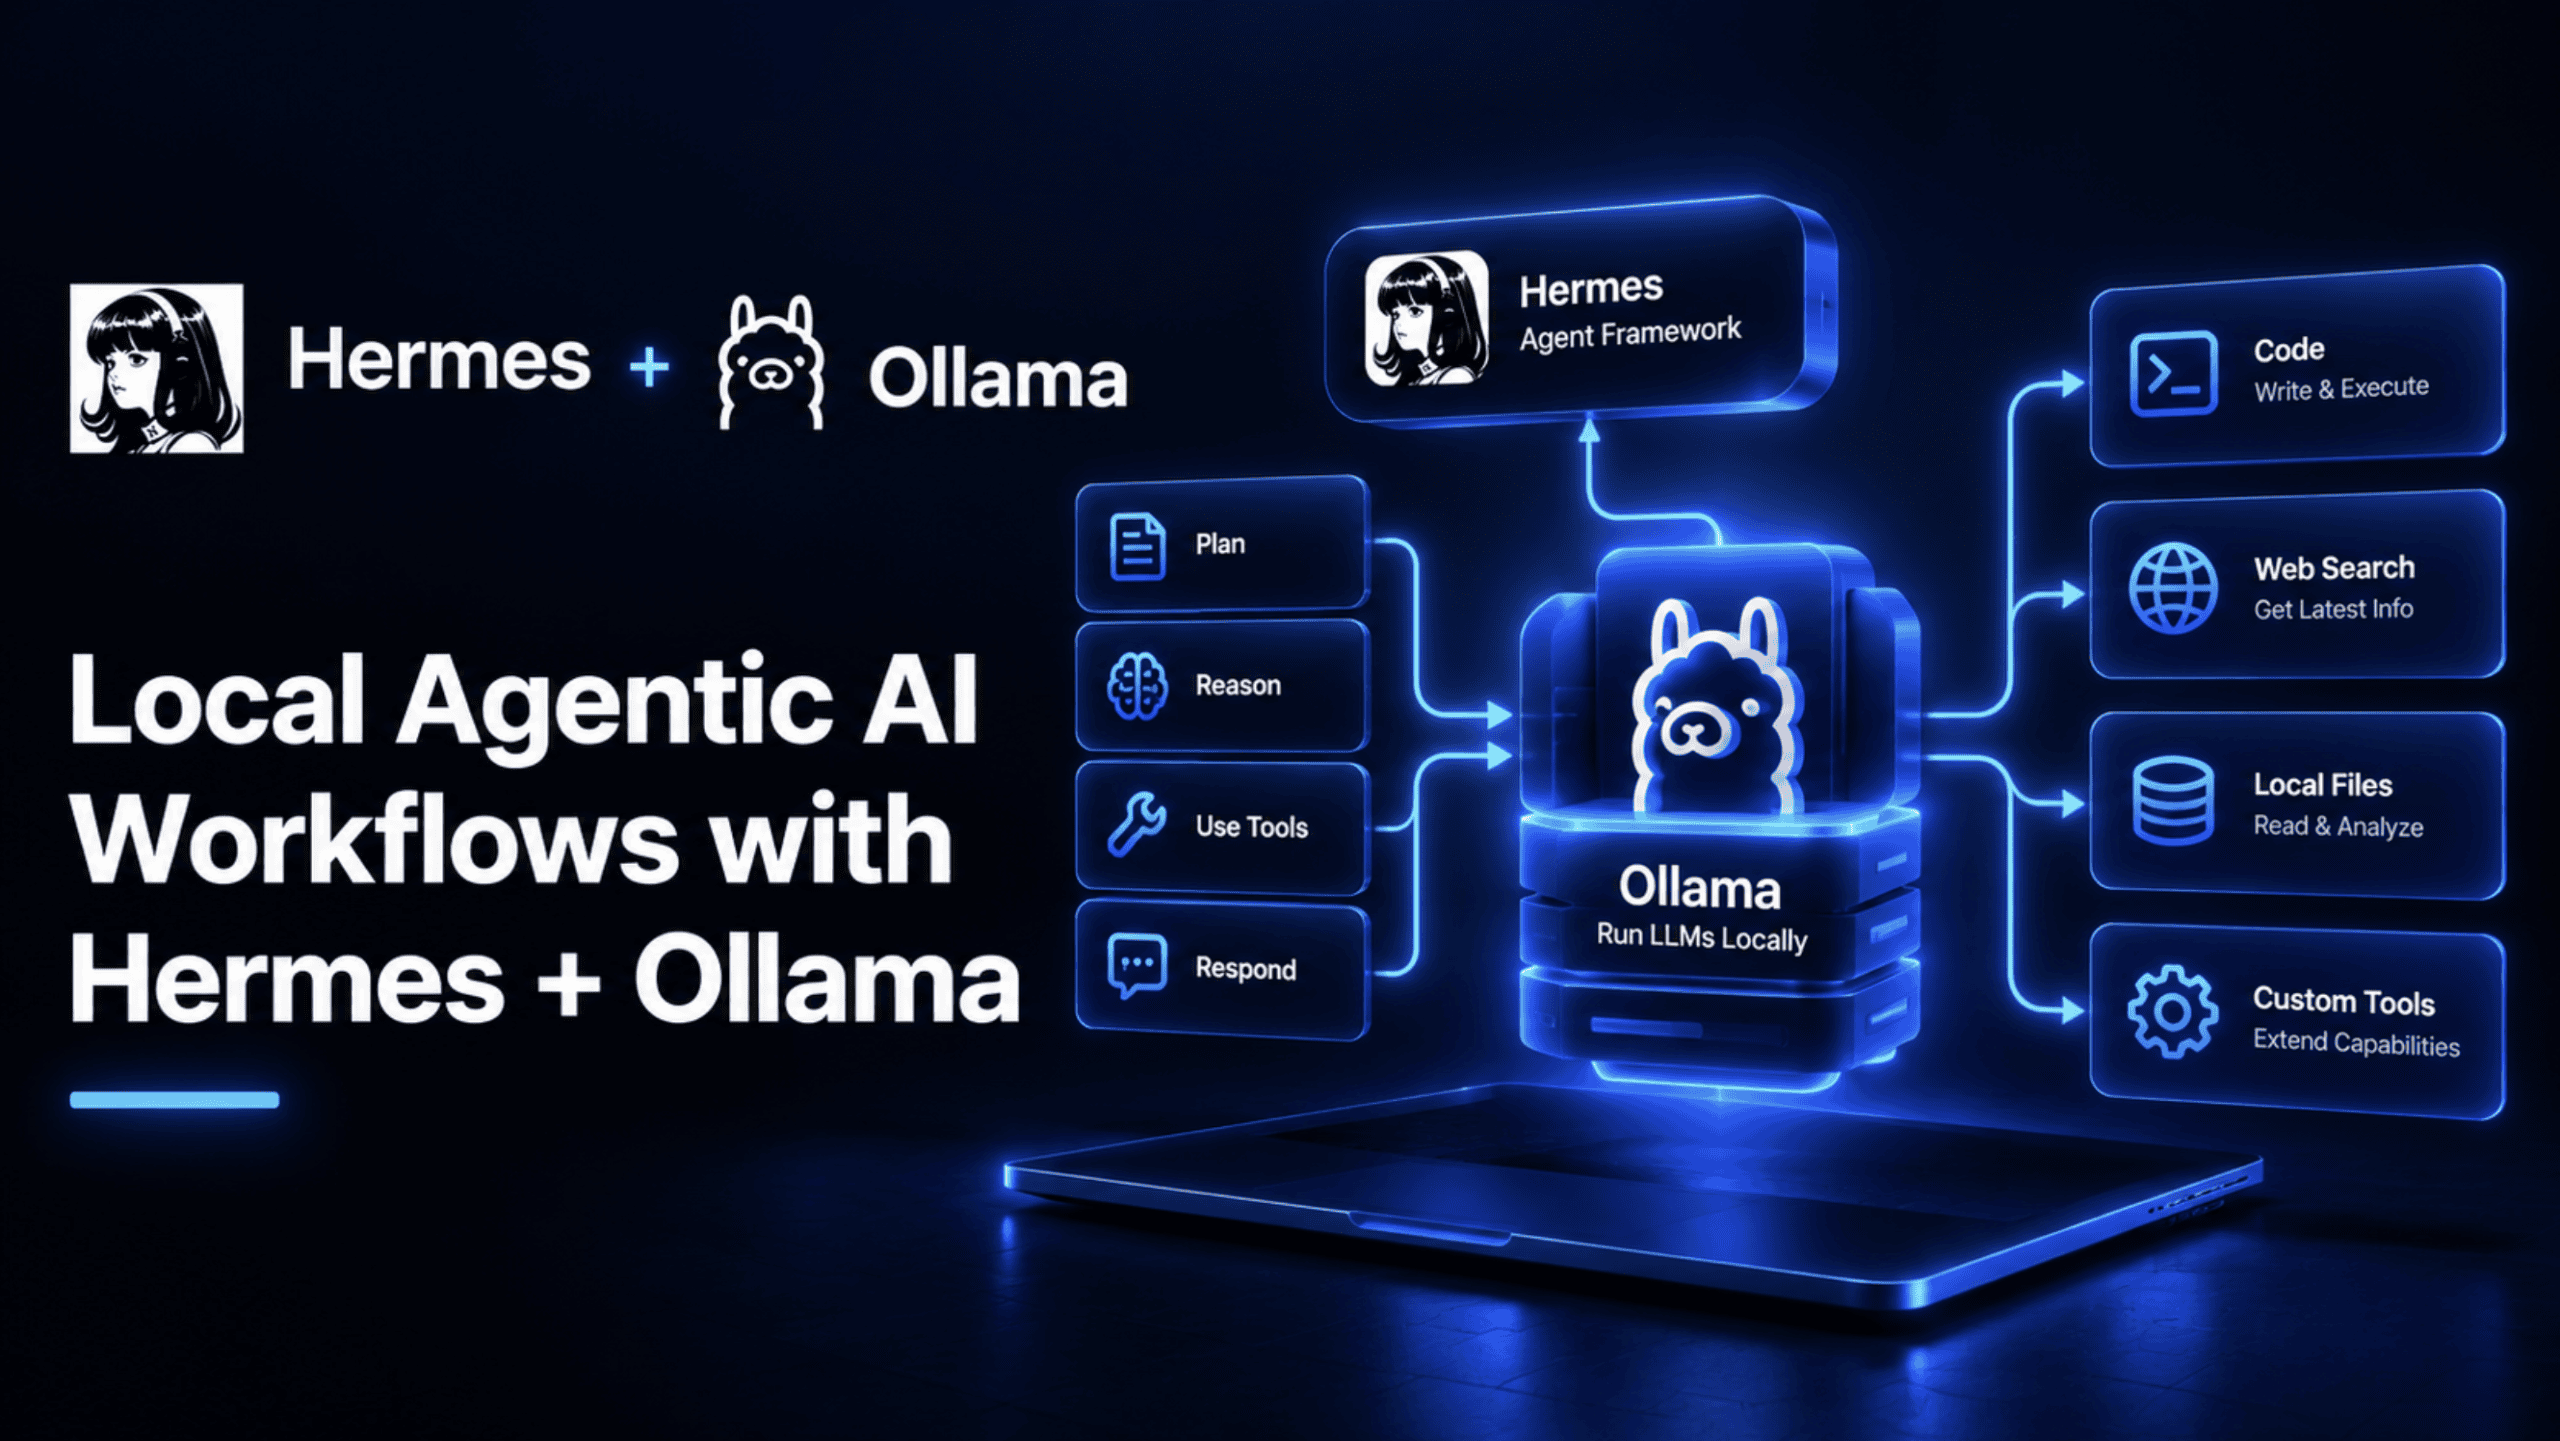
The article demonstrates how to construct a fully local, zero‑cost agentic AI workflow by combining Hermes Agent’s task orchestration with Ollama’s local LLM inference engine. It shows that by pulling a model such as Llama‑3.1 via Ollama and configuring Hermes to use that local endpoint, developers can process private files and run multi‑step reasoning without any cloud API calls, keeping costs at zero and data residency intact. The approach trades off higher local compute usage for complete privacy and eliminates network latency associated with remote inference.

A decade of mathematical certainty: Reflections on the Automated Reasoning Group
Amazon Science· 8 min read· Aug 11, 2026
A decade of mathematical certainty: Reflections on the Automated Reasoning Group
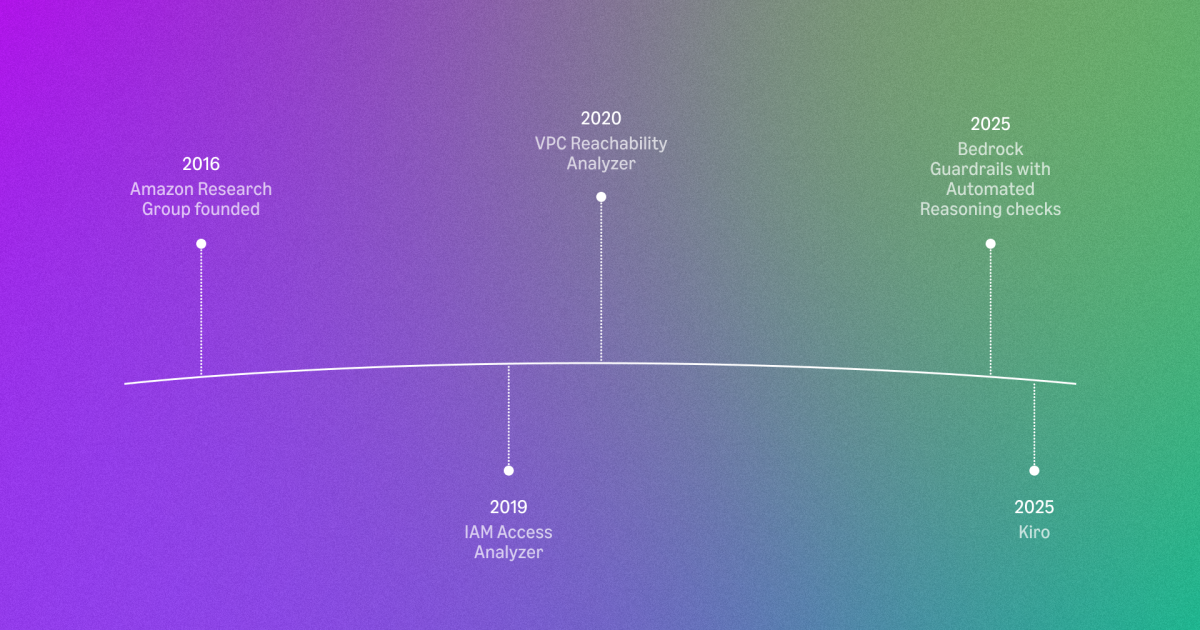
The Automated Reasoning Group (ARG) at Amazon has made significant progress over the past decade in applying mathematical logic and formal verification techniques to prove the correctness and security of AWS systems. The group's production services now process billions of queries daily, and their work has led to the development of tools such as Tiros, Zelkova, and Lean, which are used to analyze network security, policies, and cryptographic protocols. The use of automated reasoning and proof assistants has enabled the group to prove the correctness of complex systems, including the Nitro Confidentiality Engine and the AWS policy interpreter. This work has had a significant impact on the security and reliability of AWS systems, and its practical implications for engineers building AI systems include the potential to apply similar techniques to ensure the correctness and security of AI mod

Always-on AI agents turn infrastructure into a continuous learning loop
SiliconANGLE AI· 2 days ago
Always-on AI agents turn infrastructure into a continuous learning loop
Cognition AI Inc.’s Devin is an always‑on AI agent that continuously cycles through inference, feedback, and training, creating a continuous learning loop that spans the entire software development lifecycle—from planning and code generation to code review and production issue resolution. By embedding Devin into the development pipeline, teams can receive real‑time guidance and automated fixes while simultaneously feeding new data back into the model for incremental retraining. The approach trades off higher inference costs for faster iteration cycles and more resilient production systems.

NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut
NVIDIA Blog· 5 min read· Sep 16, 2026
NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut

NVIDIA’s Vera Rubin NVL72 has topped the MLPerf Inference v6.1 benchmark, setting a new performance benchmark for inference workloads. The system’s architecture emphasizes continuous software optimization and efficient scaling, so that throughput scales linearly as additional NVL72 nodes are added. This translates directly into higher token generation rates and, consequently, higher revenue potential for production inference pipelines. The result is a turnkey, high‑throughput inference platform that can be deployed at scale with minimal performance loss.

Introducing Anthropic models on Amazon Bedrock for in-region inference in Seoul and Singapore
AWS ML Blog· 6 min read· 4 days ago
Introducing Anthropic models on Amazon Bedrock for in-region inference in Seoul and Singapore

Amazon Bedrock has expanded its regional inference offering by adding Anthropic’s Claude Opus 5 and Claude Sonnet 5 to the Seoul region, and Claude Sonnet 5 to Singapore. This enables customers in South Korea and Singapore to run large‑language‑model workloads locally, reducing cross‑border data transfer and meeting stricter data residency requirements. The addition keeps Bedrock’s unified API surface while leveraging Anthropic’s latest model releases, though the new models are currently limited to these two regions. Engineers can now deploy Claude‑based pipelines directly from Bedrock with minimal changes to existing code.

EXPLORE AI NEWS

Daily hand-picked stories on LLMs, RAG, agents and production AI — curated for engineers who ship.

BROWSE NEWS

GET THE WEEKLY DIGEST

Join engineers getting the Monday signal-over-noise AI breakdown. No spam, unsubscribe anytime.

LEARN AI ENGINEERING

Curated courses, research papers, repos and tutorials built for engineers leveling up in AI.

START LEARNING