Speculative Decoding Explained: How to Get 3× Faster Inference from Any LLM
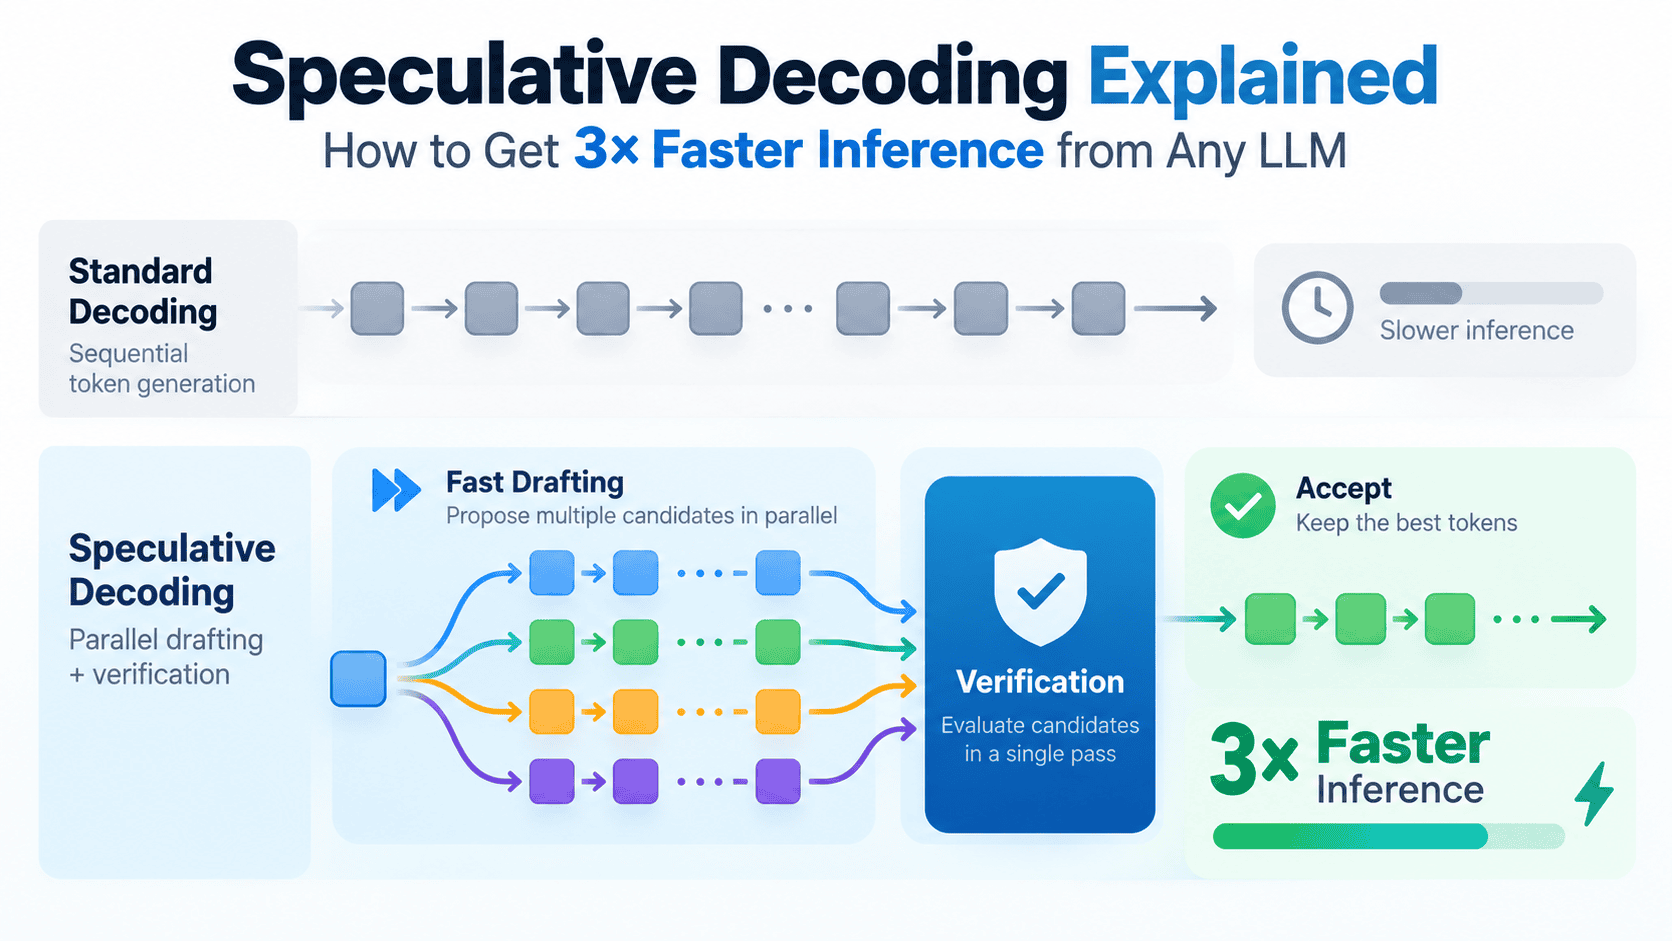
Speculative decoding can accelerate inference by up to 3× across any large language model by leveraging a fast draft model to predict tokens that are then verified by the target model, reducing the number of expensive forward passes. The technique works at the hardware level by decreasing memory bandwidth and compute utilization for the heavyweight model while preserving output quality. Engineers can adopt this approach to cut inference latency and cost without modifying the underlying model architecture.
⚡ Key Takeaways
- 3× faster inference reported when applying speculative decoding to LLMs.
- Uses a two‑model pipeline: a lightweight draft model generates candidate tokens, and the primary LLM validates them.
- Trade‑off: additional compute for the draft model is offset by fewer full passes through the large model, yielding net latency reduction.
- Integration typically involves hooking the draft‑and‑verify loop into the model’s generation API (e.g., via a custom sampler).
- Requires access to both a fast draft model and the target LLM; performance gains depend on the draft model’s speed relative to the primary model.
By cutting inference time by a factor of three, speculative decoding lets production systems serve more requests per GPU, lowering hardware costs and enabling real‑time applications that were previously latency‑bound.
✅ Practical Steps
- Implement the draft‑and‑verify loop as described, using a lightweight draft model to generate candidate tokens before invoking the main LLM for verification.
- Replace your standard generation calls with the speculative decoding pipeline to achieve the reported speedup.
Want the full story? Read the original article.
Read on Machine Learning Mastery ↗