Machine Learning Mastery
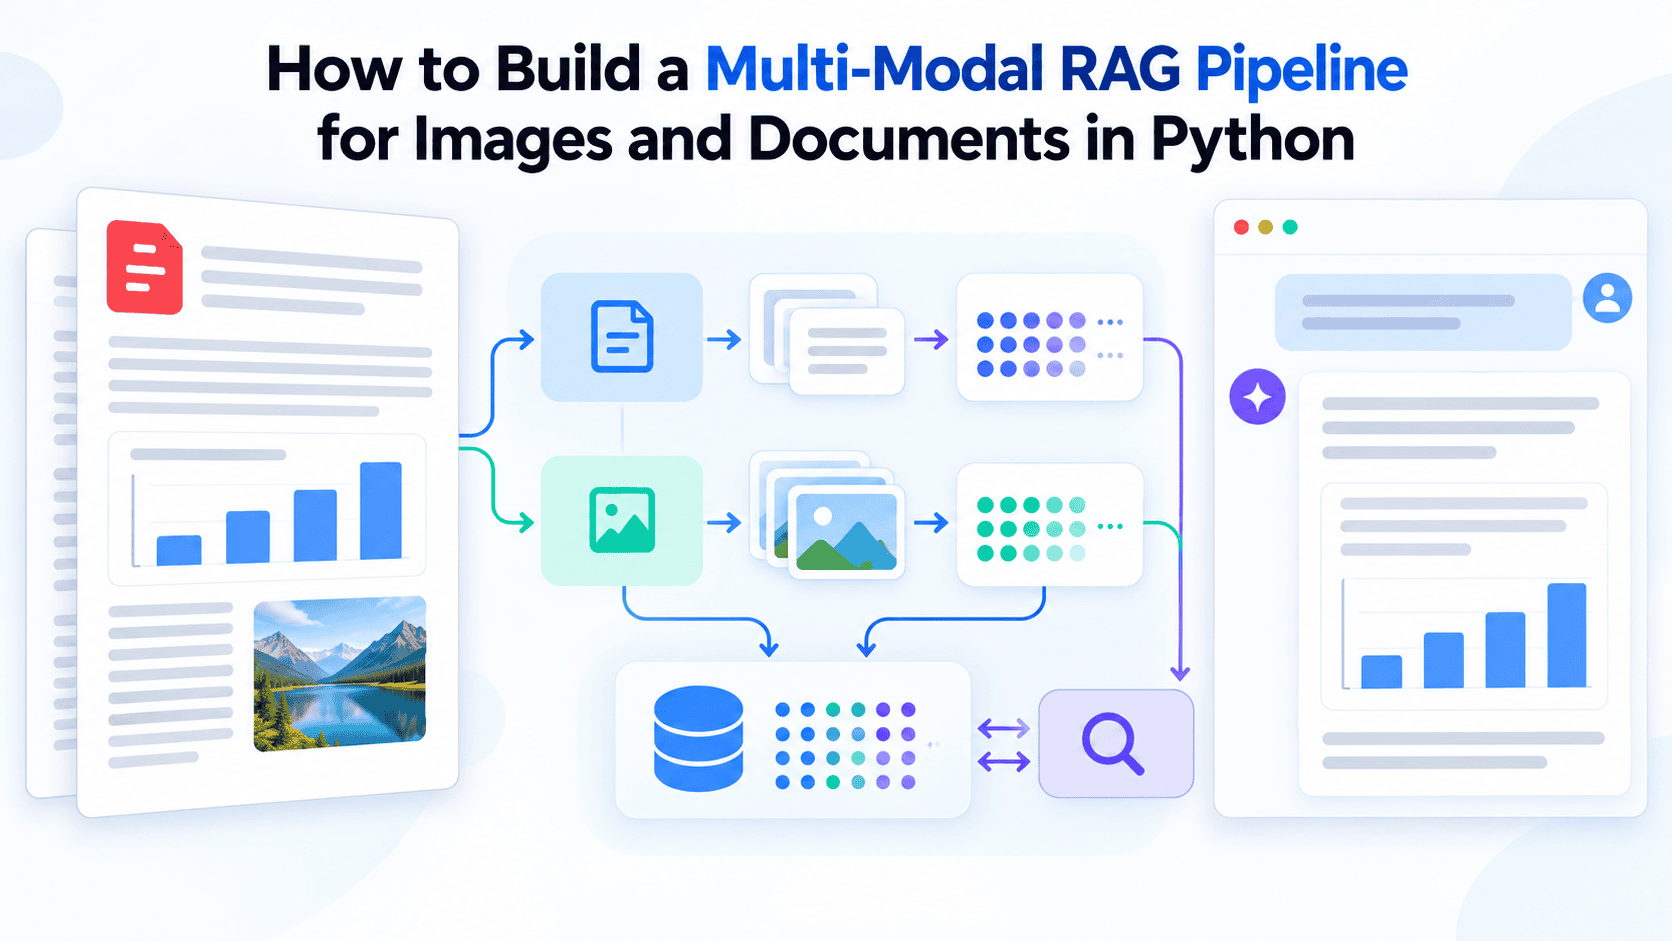
How to Build a Multi-Modal RAG Pipeline for Images and Documents in Python
Level:Intermediate
For:ML Engineers
✦TL;DR
This article explains how to construct a multi‑modal Retrieval‑Augmented Generation (RAG) pipeline in Python that can retrieve and reason over both text and images extracted from documents. Not mentioned specific model names, benchmark results, or architectural details. Engineers can apply the described approach to integrate visual and textual context into their AI applications.
⚡ Key Takeaways
- Multi‑modal RAG pipeline that handles text and images in Python.
- Combines retrieval and reasoning steps for heterogeneous data.
- Enables richer context for downstream LLM inference.
- Practical integration using Python code as demonstrated.
- Requires ability to extract images and text from source documents.
💡 Why It Matters
Adding image understanding to RAG pipelines lets engineers build more capable assistants that can answer questions using visual information alongside text, expanding the scope of AI‑driven products.
✅ Practical Steps
- Apply the concepts from this article to your own system design.
Want the full story? Read the original article.
Read on Machine Learning Mastery ↗More like this
Does Agentic RAG Actually Retrieve Better Evidence? I Tested It on 298 Questions
Towards Data Science•#rag
Write your own training loop — without managing GPUs — with Amazon SageMaker training session APIs
AWS ML Blog•#llm
Building a Custom LLM Evaluation Harness in Python from Scratch
Machine Learning Mastery•#llm
How to Fine-Tune Llama 3 for Custom Tool Calling with Unsloth in Python
Machine Learning Mastery•#python