Machine Learning Mastery
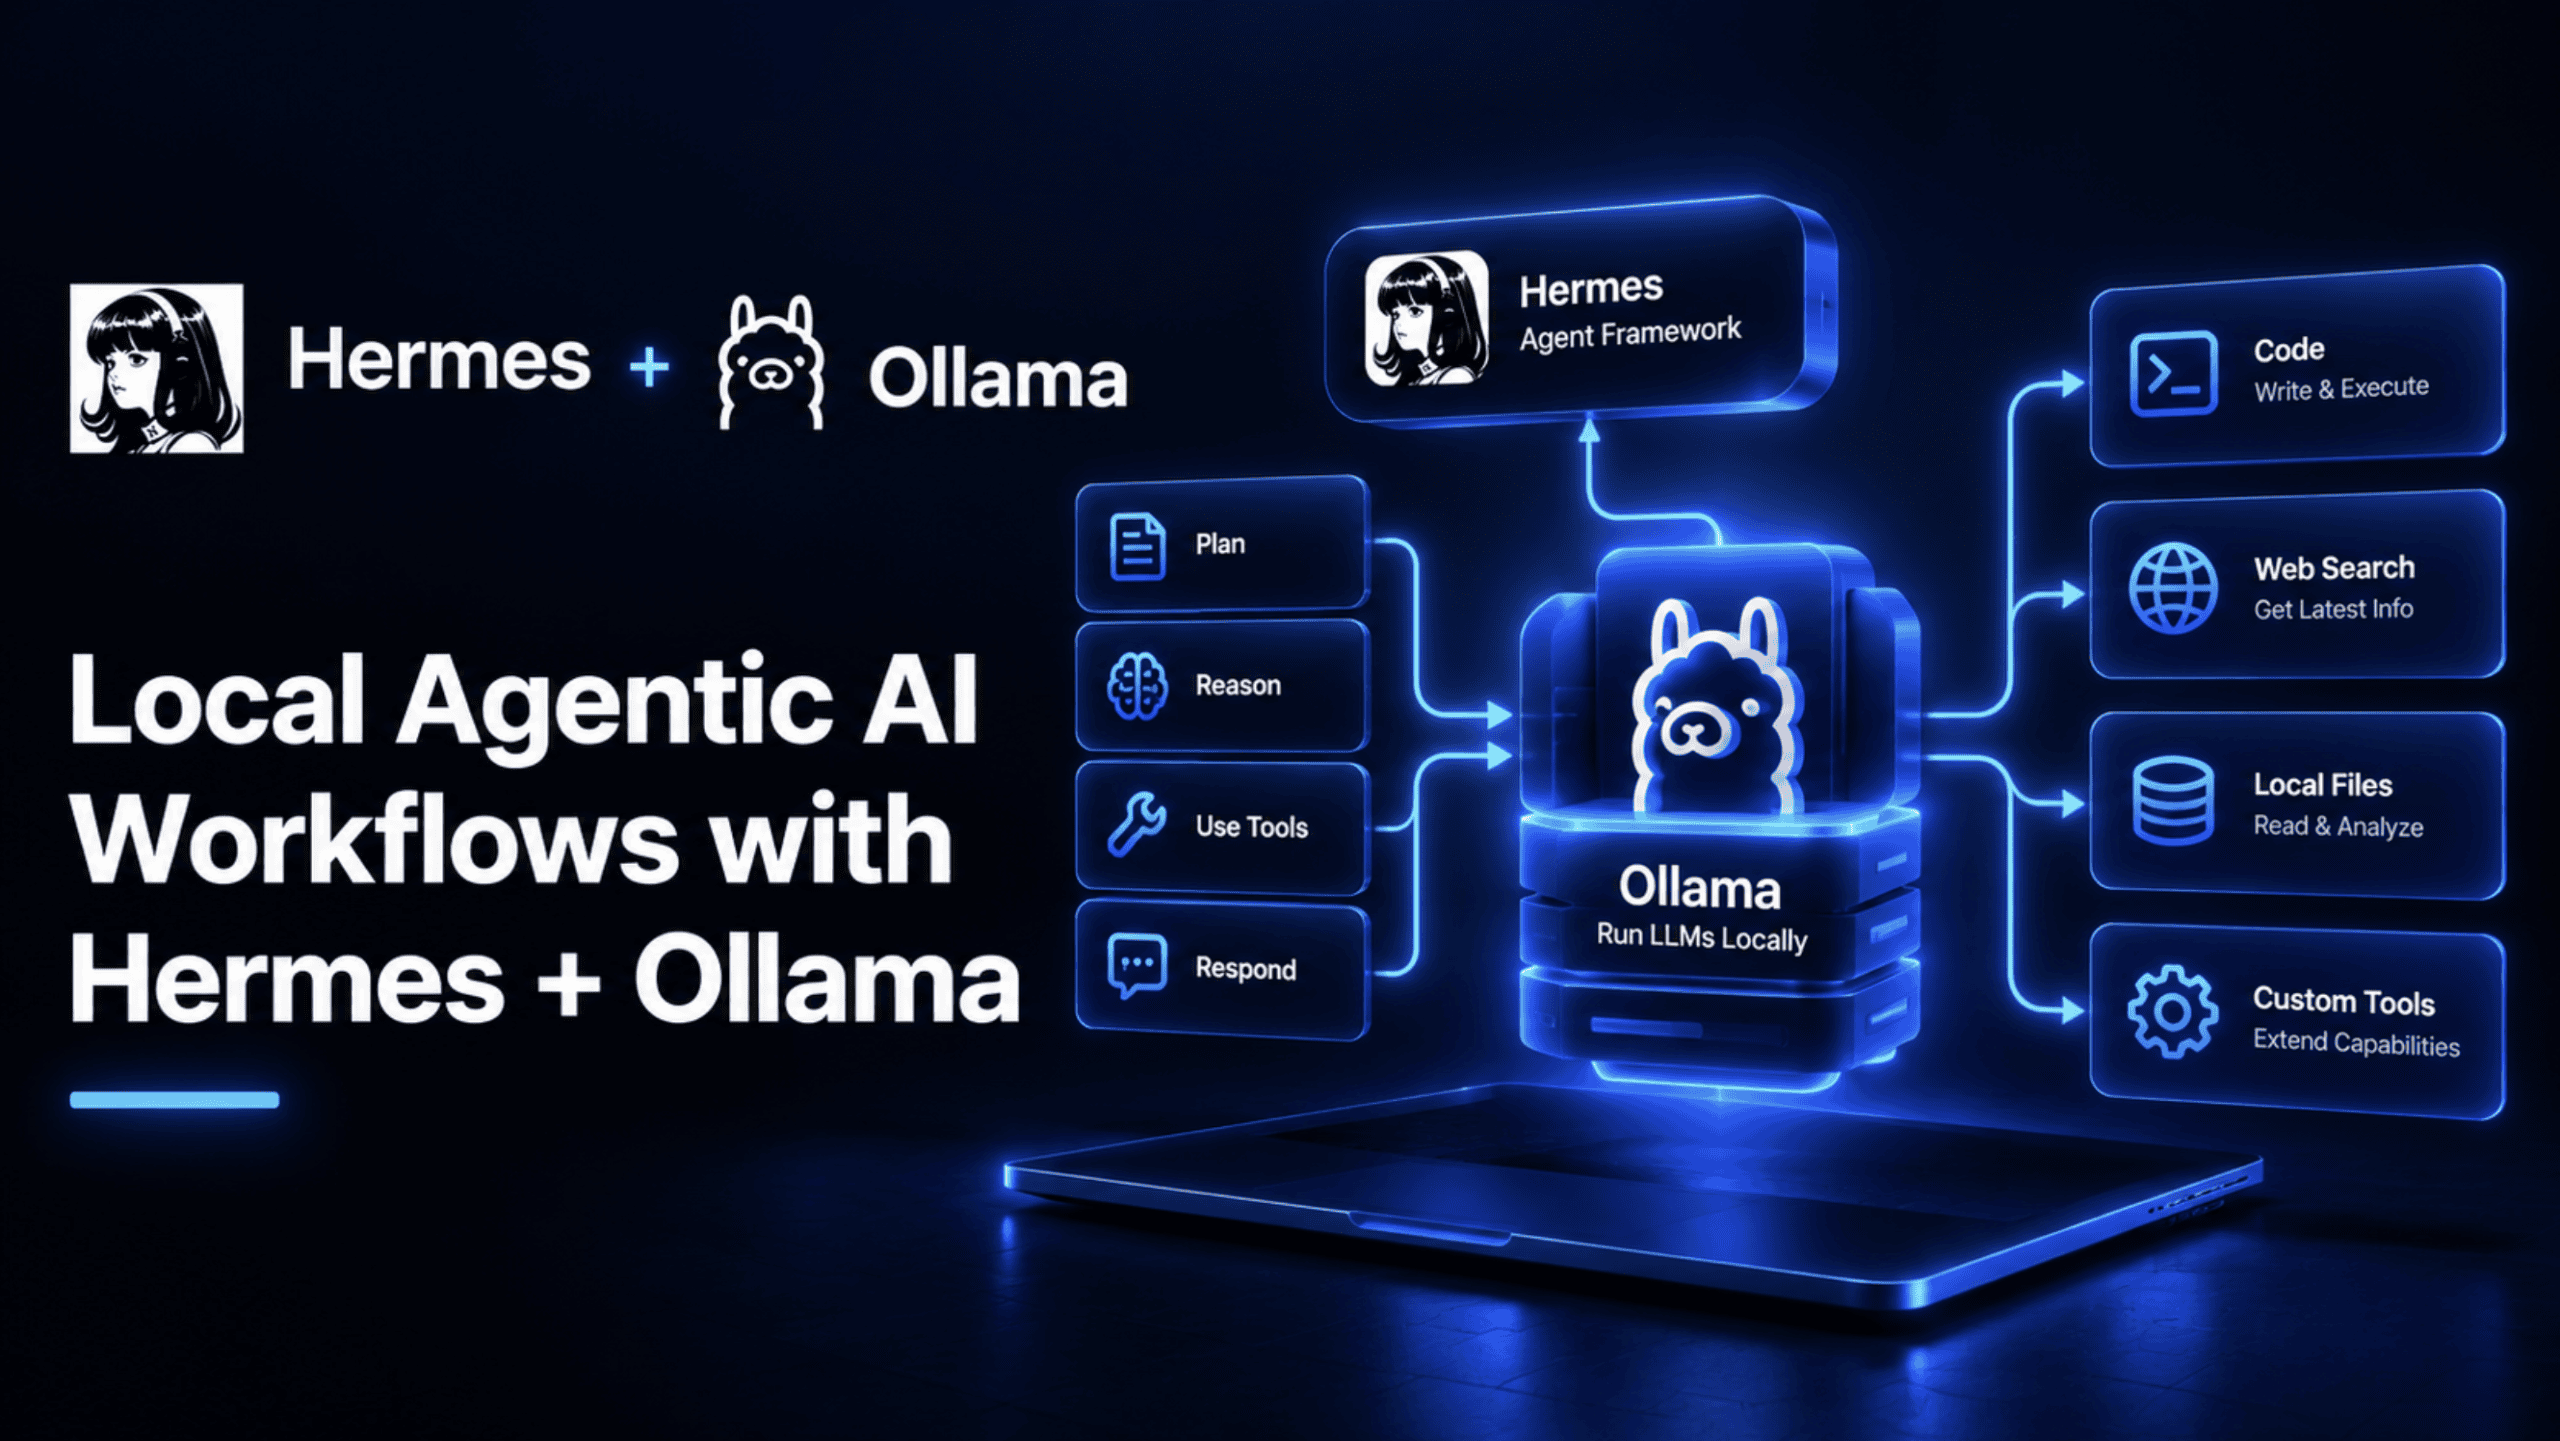
Local Agentic AI Workflows with Hermes + Ollama
Level:Intermediate
For:AI Engineers
✦TL;DR
This article demonstrates how to construct a completely local, zero‑cost agentic AI workflow by combining Hermes Agent with the Ollama runtime, enabling on‑device processing of files without external API calls. Engineers can leverage the Hermes Agent’s planning capabilities together with Ollama’s local model serving to build self‑contained automation pipelines. The approach removes reliance on cloud services, reducing latency and operational expense for production AI systems.
⚡ Key Takeaways
- Hermes Agent is used as the core planning component in the workflow.
- Ollama provides the local model serving environment for executing the agent’s actions.
- The solution operates with zero monetary cost by running entirely on local hardware.
- Integration requires configuring Hermes Agent to invoke Ollama for model inference.
- No external APIs or cloud services are required, so network connectivity is not a prerequisite.
🔧 Tools & Libraries
Hermes AgentOllama
💡 Why It Matters
By eliminating cloud dependencies, engineers can deploy secure, low‑latency AI agents on edge devices or isolated environments, accelerating iteration and cutting operational spend.
✅ Practical Steps
- Apply the concepts from this article to your own system design.
Want the full story? Read the original article.
Read on Machine Learning Mastery ↗More like this
New in AWS Quick: More capable flows, an updated web experience, and agents that work together
AWS ML Blog•#agents
How Google Duplex evolved to also call businesses for you in Gemini
Google Research•#agents
Genie ZeroOps, now in public beta: An autonomous agent that fixes data pipelines, with lessons from 80,000 customer issues
Databricks Blog•#agents
Towards a Science of Capable Autonomous Agents & Provable Safety — Part II
CMU ML Blog•#agents