Machine Learning Mastery
Interpretable Text Classification: Probing Scikit-LLM Embedding Spaces
✦TL;DR
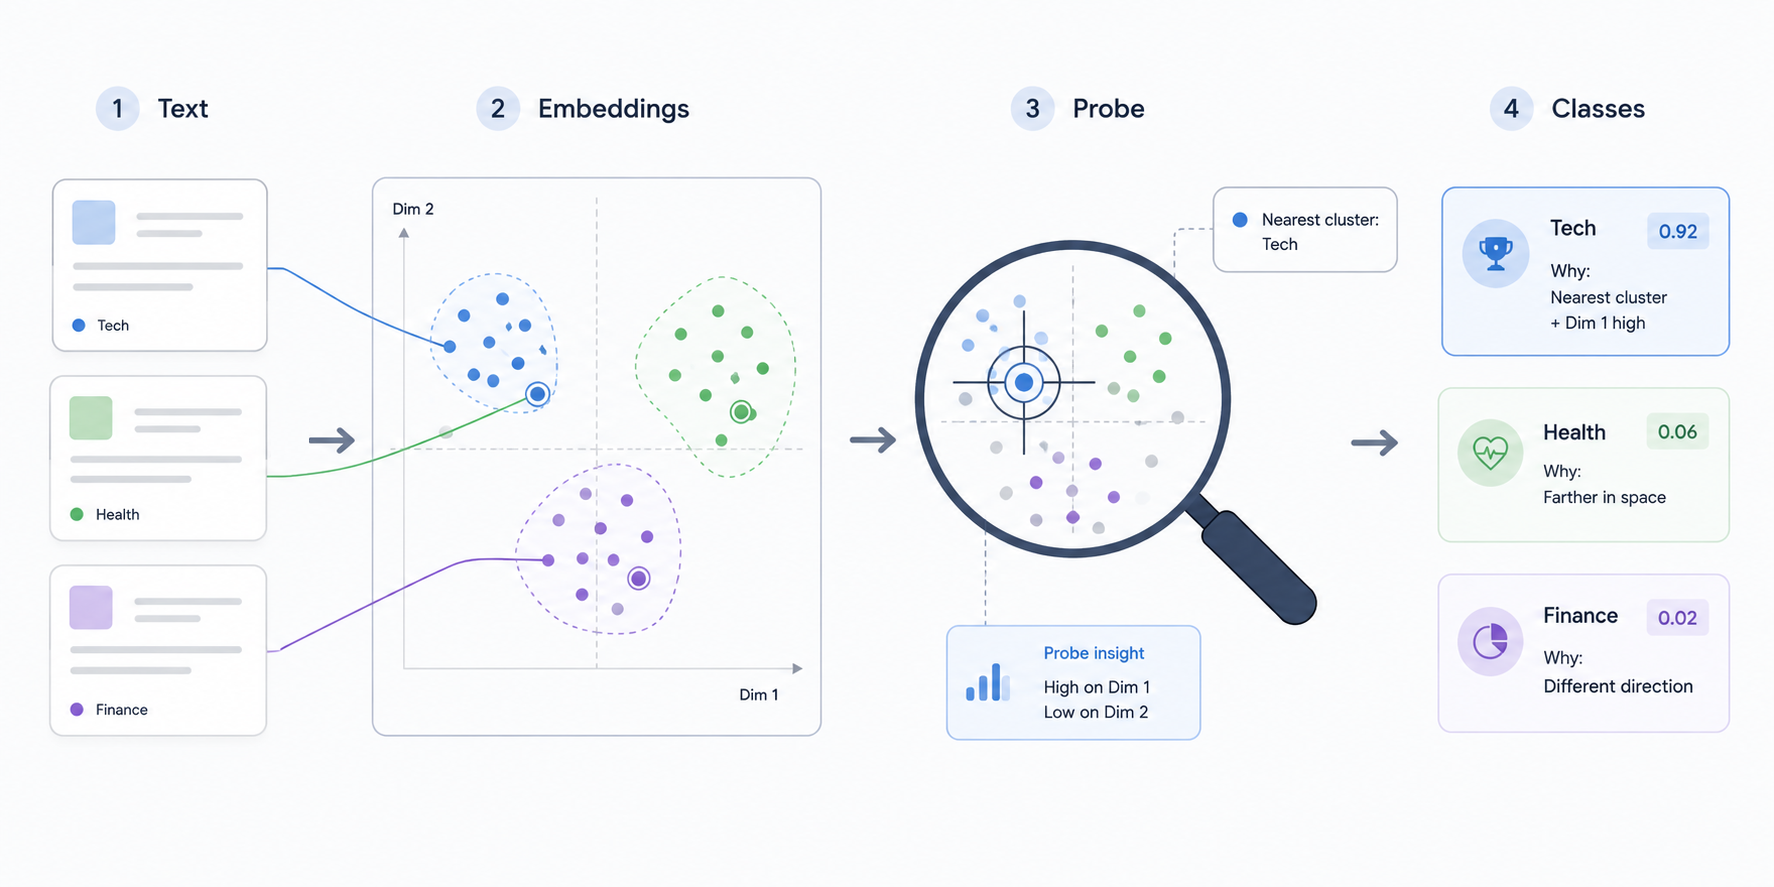
The article demonstrates how to assess the semantic quality of text embeddings produced by scikit‑LLM by training lightweight probing classifiers, visualizing embedding clusters with UMAP, and attributing feature importance with SHAP. It shows that probing accuracy can reveal class‑specific signal strengths, while UMAP plots expose cluster separability, and SHAP values pinpoint which tokens drive embedding distinctions. The approach offers a practical, model‑agnostic pipeline for diagnosing embedding shortcomings before deploying downstream classifiers.
⚡ Key Takeaways
- scikit‑LLM embeddings can be evaluated using a probing classifier that reports class‑wise accuracy on
Want the full story? Read the original article.
Read on Machine Learning Mastery ↗More like this
Censored vs. Truncated Regression in Python, Explained
Towards Data Science•#llm
How Google Duplex evolved to also call businesses for you in Gemini
Google Research•#agents
Q&A: Enabling more human-like interactions and understanding in multimodal foundation models
MIT News AI•#llm
Welcome Inkling 2 Mini, Cutting-edge Performance for your Local Setup
Hugging Face Blog•#llm