Machine Learning Mastery
Automating Knowledge Graph Population: Extracting Entities and Triples from Unstructured Text with an LLM
Level:Intermediate
For:ML Engineers
✦TL;DR
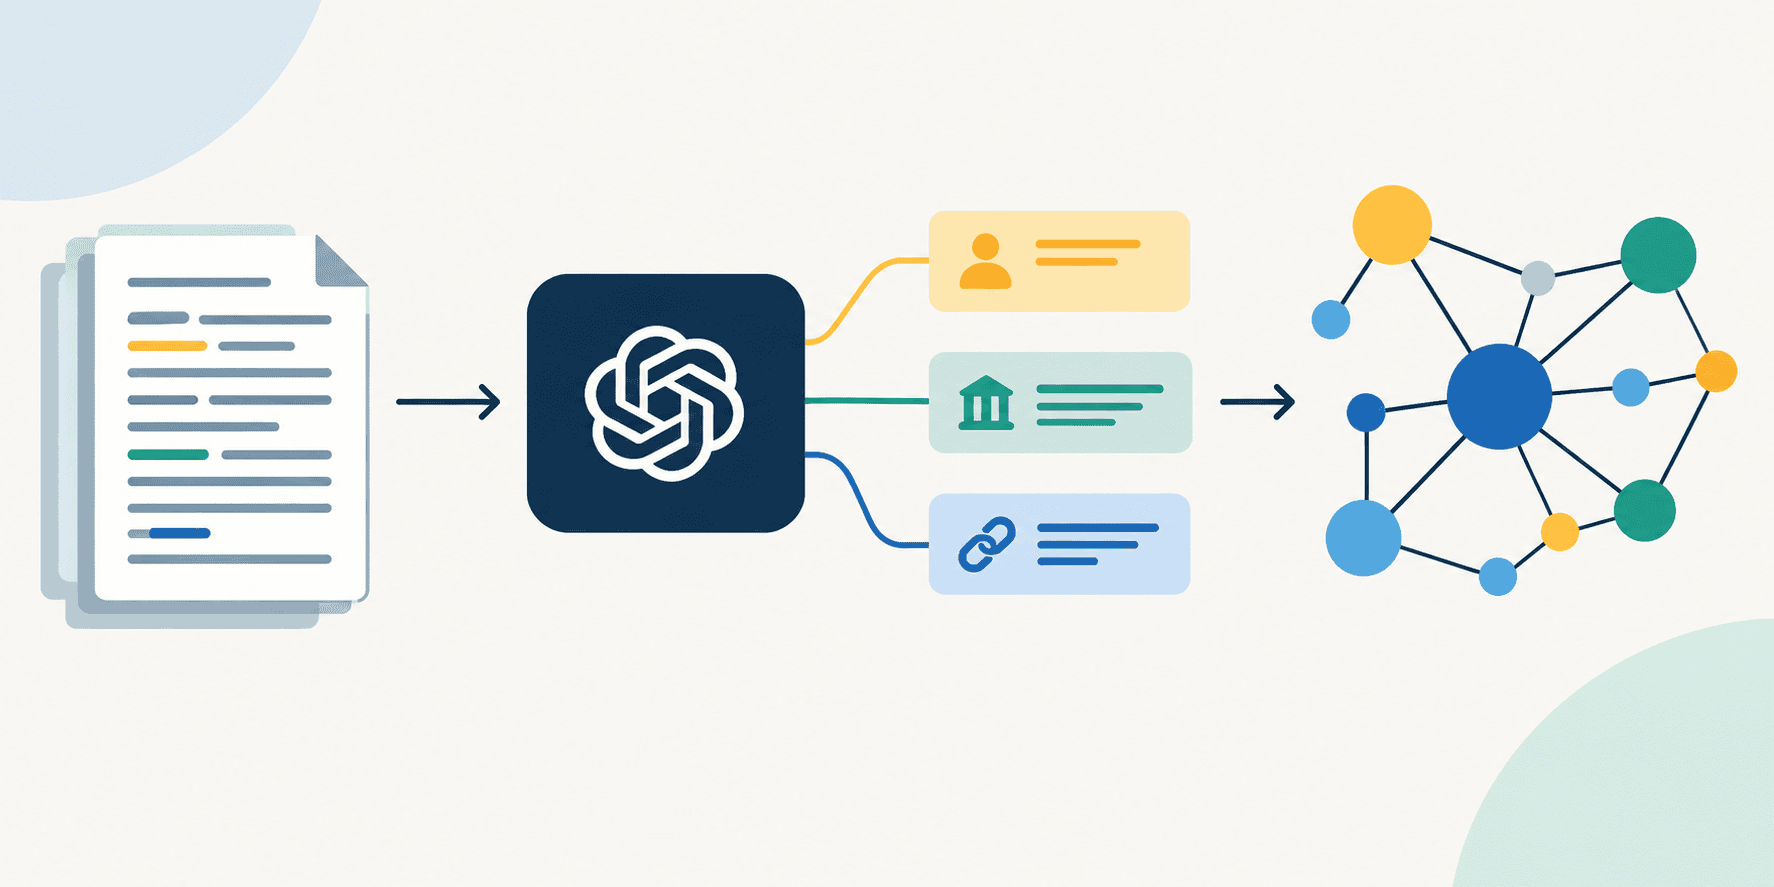
The article introduces a method for automatically extracting subject‑predicate‑object‑context (SPOC) quads from raw, unstructured text using a large language model (LLM) to populate a knowledge graph. It outlines a pipeline that transforms free‑form text into structured triples, enabling downstream graph‑based reasoning. By leveraging LLM‑driven extraction, engineers can streamline knowledge graph construction without manual annotation. This approach reduces data preparation effort for graph‑centric AI applications.
⚡ Key Takeaways
- The workflow focuses on extracting SPOC quads (subject‑predicate‑object‑context) from unstructured text.
- It relies on an LLM to perform entity and relation extraction.
- The resulting triples are directly ingestible into a knowledge graph for downstream use.
💡 Why It Matters
Automating triple extraction with an LLM cuts manual curation time, allowing production teams to scale knowledge graph building and accelerate graph‑based AI features.
✅ Practical Steps
- Apply the concepts from this article to your own system design.
Want the full story? Read the original article.
Read on Machine Learning Mastery ↗More like this
Censored vs. Truncated Regression in Python, Explained
Towards Data Science•#llm
How Google Duplex evolved to also call businesses for you in Gemini
Google Research•#agents
Q&A: Enabling more human-like interactions and understanding in multimodal foundation models
MIT News AI•#llm
Welcome Inkling 2 Mini, Cutting-edge Performance for your Local Setup
Hugging Face Blog•#llm